

Variational Quantum Algorithms
A variational quantum algorithm (VQA) optimizes a classical parameter vector using quantities estimated from a parameterized quantum circuit. In a common form,
and the task is encoded in an objective such as
The quantum processor prepares states and samples measurements; a classical routine constructs cost or gradient estimates and proposes the next parameters. The loop is repeated until a declared stopping rule is met.
Useful applications include VQE, which minimizes an energy, and QAOA, which optimizes a cost using alternating operators. The general questions are shared: can the circuit reach a useful state, can measurements resolve improvements, and can the classical search find them at acceptable total cost? A decreasing cost alone does not answer all three.
Helpful background. Circuit models describes gate sequences, expectation values connects states to measured averages, and variance and covariance explains the uncertainty of weighted estimates.
Variational objectives and repeated measurements
Section titled “Variational objectives and repeated measurements”Choose an initial state, parameterized circuit, objective and a criterion for useful output. Then repeatedly prepare the circuit state, measure the required observables, and use the resulting cost or gradient estimates to propose new parameters. Stop when the task criterion or resource budget is reached, and evaluate the selected parameters with fresh measurements. The introductory treatments of McClean and collaborators and Cerezo and collaborators develop this hybrid structure.
The output might be a parameter vector, a quantum state or a measured number. For a state-preparation task, the optimized objective must constrain the properties that actually matter. For a numerical estimate, uncertainty and acquisition cost remain part of the answer. Optimization can also select favorable measurement noise: the lowest estimate among many trials tends to be too low. Fresh measurements assess the chosen state without reusing that selection fluctuation.
Changing parameters may bind new angles in one compiled circuit or trigger a different decomposition. Those choices can change both cost and noise. Likewise, adaptive shot allocations mean that measurements collected at different stages generally are not identically distributed samples of one fixed state.
Objective, Estimand, and Estimator
Section titled “Objective, Estimand, and Estimator”Three objects are easy to conflate:
- the ideal objective defined by the mathematical problem;
- the implemented estimand defined by the compiled circuit and physical experiment;
- the finite-data estimator computed from observed records.
For an ideal pure-state objective,
Compilation approximation and noise produce a physical state , so the hardware estimand is
where denotes time-dependent context. A sample mean estimates , not automatically . The useful decomposition is
The first term is statistical error. The second includes coherent miscalibration, decoherence, readout error, drift, compilation approximation, and any mismatch between the intended and realized observable. More shots reduce the first term but need not reduce the second.
Objectives built from many observables
Section titled “Objectives built from many observables”Suppose
With separately estimated terms,
For independent, stationary settings, let term receive shots with single-shot variance . Then
For fixed total shots , the continuous optimum is
A Lagrange multiplier gives , which yields this allocation. The resulting minimum variance is . Terms with nonzero variance need positive allocations; a variance inferred as zero from a small pilot sample is not a proof that the term is deterministic.
Uniform allocation is therefore not generally optimal. In practice, is unknown and can be learned from pilot data. Commuting terms can sometimes share measurement settings, but grouping introduces covariance and changes circuit count, basis-change depth, and statistical analysis. The measurement design must be optimized as a whole rather than term by term.
Nonlinear postprocessing
Section titled “Nonlinear postprocessing”Ratios, logarithms, normalization by estimated quantities, postselected conditional means, and mitigation inverses can be biased at finite sample size. For a nonlinear map ,
in general. Bootstrap intervals can help with irregular estimators, but only if resampling respects the experimental hierarchy. Analytic propagation, likelihood methods, or simulation-based calibration may be preferable.
Parameterized Circuit Families
Section titled “Parameterized Circuit Families”An ansatz is the map
Its reachable set is a manifold or stratified subset of state space, often of far lower dimension than the full Hilbert space. The key question is not whether the family can approximate arbitrary states, but whether it can reach useful states for the target instance at acceptable depth and can be searched with available precision.
Problem-inspired circuits
Section titled “Problem-inspired circuits”Problem-inspired ansatzes use generators, symmetries, conserved quantities, or known limiting states from the application. A layered form is
If the generators commute with a symmetry and the initial state lies in one symmetry sector, then the circuit remains there:
This can exclude invalid states and reduce the search space. It can also exclude the solution if the sector, encoding, or assumed symmetry is wrong. Constraints should therefore be justified from the problem, not imposed only because they simplify optimization.
Hardware-efficient circuits
Section titled “Hardware-efficient circuits”Hardware-efficient ansatzes alternate native single-qubit rotations and entangling layers chosen to match connectivity. They can minimize compiled depth for a given number of layers, but the phrase does not mean efficient optimization or favorable asymptotic scaling. Deep, highly random families can be expressive while producing concentrated costs and gradients. Native gates can also drift, crosstalk, and vary strongly across qubits.
Adaptive and growing circuits
Section titled “Adaptive and growing circuits”An adaptive method adds generators or layers according to measured information. This can keep early circuits shallow and allocate parameters where they appear useful. It also creates a nested selection process: each proposed operator, gradient estimate, and stopping decision consumes measurements. Comparisons must count the rejected candidates and all intermediate circuits, not only the final compact ansatz.
Expressibility is not the objective
Section titled “Expressibility is not the objective”One expressibility diagnostic compares the distribution of state overlaps generated by the ansatz with the Haar distribution. Such metrics can rank circuit families, but closeness to Haar-random states is not synonymous with task performance. An ansatz may be:
- too restricted to represent the target;
- expressive enough for the target but easy to train;
- highly expressive yet redundant and statistically untrainable;
- expressive in ideal simulation but ineffective after noise.
The desired family is task sufficient, symmetry appropriate, compilable, and trainable under the actual estimator. Maximum generic expressibility is usually neither necessary nor desirable.
Exact Quantum Gradients
Section titled “Exact Quantum Gradients”For
a derivative can often be written as a linear combination of expectation values evaluated by shifted circuits. This avoids differentiating sampled bit strings as though they were deterministic floating-point outputs.
Two-eigenvalue parameter-shift rule
Section titled “Two-eigenvalue parameter-shift rule”Consider one gate
where the Hermitian generator has eigenvalues . Holding all other gates fixed,
For
one has and therefore
This identity is exact for the ideal expectation function. Its finite-shot implementation remains a noisy gradient estimator. If one parameter controls several gates, the chain rule contributes once per occurrence unless a generalized rule exploits the full Fourier spectrum.
Generators with more than two distinct eigenvalues generally require more shifted evaluations or stochastic rules. Fixed, parameter-independent quantum channels before and after the shifted gate preserve the rule for the noisy expectation value, because the channel and expectation are linear. The result need not be the ideal gradient. Parameter-dependent noise, a compilation change or nonlinear conditional normalization can invalidate the two-point identity. For a postselected ratio , differentiate the numerator and acceptance probability and use the quotient rule; do not simply shift the ratio.
The derivations of Mitarai and collaborators and Schuld and collaborators apply the gate’s frequency structure. Wierichs and collaborators give generalized shift rules; Banchi and Crooks develop a stochastic rule for more general evolution.
Gradient-estimator variance
Section titled “Gradient-estimator variance”If the two shifted sample means are independent with variances and , the Pauli-rotation rule gives
For independent shots, ; these are not the single-shot variances. Using common random numbers is not usually literal on hardware, because measurement outcomes from distinct quantum circuits are independent. Correlated calibration blocks or paired execution schedules can nevertheless reduce drift mismatch, and covariance must then be included explicitly.
For parameters, a naive full parameter-shift gradient can require order objective evaluations per iteration, each of which may contain many measurement settings. This multiplicative cost is often more important than the nominal depth of one ansatz circuit.
Finite differences
Section titled “Finite differences”The centered finite difference
has truncation bias of order for a smooth objective, while its sampling variance scales as order . Making smaller reduces truncation bias but amplifies shot noise, calibration quantization, and drift. A finite-difference step therefore requires an explicit bias-variance choice.
Simultaneous perturbation
Section titled “Simultaneous perturbation”Simultaneous perturbation stochastic approximation (SPSA) draws a random direction , often with independent entries in , and uses two cost evaluations:
Its circuit-evaluation count does not grow linearly with per stochastic gradient estimate, but the estimate can have high variance and requires careful gain schedules. “Two evaluations” is not “two shots”: each cost may still require many circuits and measurements.
Classical Optimization
Section titled “Classical Optimization”No optimizer is uniformly best for VQAs. The relevant regime combines noisy function evaluations, periodic parameters, constraints, heterogeneous curvature, device drift, expensive batches, and sometimes discrete ansatz choices.
First-order stochastic methods
Section titled “First-order stochastic methods”An elementary update is
Stochastic-gradient methods can converge with unbiased finite-variance estimators under regularity and step-size assumptions. VQA gradients may be estimated by sampling shots, observable terms, data records, or combinations of these. Such convergence statements do not guarantee reaching the global minimum of a nonconvex objective, and they do not rescue exponentially small signals.
Momentum and adaptive coordinate scaling can improve empirical behavior, but their hyperparameters and stopping rules are part of the algorithm. Tuning them on the reported instances without accounting for selection exaggerates performance.
Derivative-free methods
Section titled “Derivative-free methods”Nelder–Mead, Powell-type searches, coordinate methods, Bayesian optimization, and trust-region model building can be useful when gradients are unavailable or very noisy. Their decisions still depend on resolving cost differences. In a barren plateau those differences can be exponentially suppressed, so choosing a gradient-free optimizer does not by itself remove the information problem.
Curvature and trust regions
Section titled “Curvature and trust regions”Quasi-Newton and trust-region methods use local models to adapt steps to curvature and uncertainty. They can reduce iteration count but may require additional evaluations, stable Hessian approximations, or bounds on model error. A noisy optimizer should reject or shrink a step when the predicted improvement is not statistically resolved, rather than treating every fluctuation as a descent direction.
Quantum Geometry and Natural Gradient
Section titled “Quantum Geometry and Natural Gradient”The same physical state can have many parameter descriptions, and equal Euclidean parameter steps need not represent equal changes in state. For a normalized pure-state family, the Fubini–Study metric is
It defines the local line element
For pure states, the quantum Fisher information matrix is under a common convention. Because authors differ by this factor, an implementation should state which matrix it uses.
Quantum natural gradient chooses a step by solving
The construction of Stokes and collaborators uses the geometry of quantum states. With and nonsingular , the infinitesimal natural-gradient direction transforms correctly under a smooth invertible change of coordinates. At a rank-deficient point, restrict to identifiable tangent directions or handle the null directions explicitly.
Adding stabilizes a numerical solve, but selects a Euclidean metric in the chosen coordinates and generally breaks that invariance. Diagonal approximations and finite Euler steps also need not be invariant. For example, if and , then . The unregularized steps describe the same physical tangent; applying the same positive in both coordinate systems generally does not.
Geometry is not free. Estimating can require additional circuits and shots, and inverting an ill-conditioned matrix amplifies estimator noise. The comparison that matters is total cost to a validated answer, not iterations to a low training objective.
Redundant parameters
Section titled “Redundant parameters”If a nonzero vector satisfies
then the corresponding tangent has zero Fubini–Study length: its first-order change is at most a global phase. The state can still change at higher order along that coordinate direction. Such null directions can come from repeated generators, circuit identities, symmetries, or state-dependent stabilizers. They create flat directions without necessarily creating a many-qubit barren plateau.
The effective local dimension is
When , reporting only the number of trainable parameters overstates the local capacity. For an exact redundancy, such as two consecutive rotations about the same axis, combining parameters removes the redundant coordinate without changing the states. A metric that loses rank only at an isolated point does not by itself justify deleting a parameter from the whole ansatz.
Barren Plateaus
Section titled “Barren Plateaus”A barren plateau is a scaling phenomenon, not merely a plot that looks flat. For an ensemble of instances or random initializations, a common diagnostic is
for some as the number of qubits grows. Typical gradients then become exponentially small. Resolving their sign or relative size with incoherent sampling can require exponentially many measurements.
This definition is about a sequence of problem sizes and a specified sampling ensemble. A small gradient at one point may instead indicate a local optimum, a saddle, a symmetry, a redundant parameter, an insensitive observable, or a poor coordinate scale. Conversely, visibly nonzero gradients on eight qubits do not establish polynomial trainability.
Randomness and unitary designs
Section titled “Randomness and unitary designs”For sufficiently expressive randomly initialized circuits, parts of the circuit can approximate unitary 2-designs. Under the assumptions of the standard results, concentration of measure makes expectation gradients exponentially small. Depth, connectivity, gate ensemble, initial state, and observable all affect when that regime appears.
The lesson is not that every deep circuit has a barren plateau. It is that generic expressibility can erase the structured signal the optimizer needs. Random initialization should be treated as a substantive algorithmic choice.
Global and local costs
Section titled “Global and local costs”The support of the measured observable matters. Global costs can concentrate even for shallow circuits. In particular models, replacing a global fidelity- like objective with a sum of local costs changes exponential gradient scaling to polynomial scaling while preserving the same exact optimum.
That is not a universal license to localize every objective. A surrogate local cost must remain operational: low surrogate loss should imply success on the original task, with a quantitative bound if possible. Otherwise trainability is purchased by optimizing the wrong quantity.
Noise-induced plateaus
Section titled “Noise-induced plateaus”Noise contracts distinguishable states and can suppress both objective variation and gradients. The theorem of Wang and collaborators assumes layerwise local Pauli noise that strictly contracts every nonidentity Pauli component, together with its stated circuit and observable bounds. It gives exponential gradient suppression with depth; polynomial prefactors do not offset that suppression when depth grows linearly with . A dephasing channel that preserves , or the identity channel, does not satisfy the strict-contraction premise.
Nonunital noise requires a separate analysis. Singkanipa and Lidar identify noise-induced limit sets, but do not imply that every parameter’s gradient vanishes for every nonunital circuit. For instance, amplitude-damping steps leave fixed; a final still gives for every . If the rotation precedes the damping instead, with excitation survival probability per step, then
Noise type and the position of the parameter in the circuit both matter.
This mechanism differs from random-circuit concentration. A carefully initialized problem-inspired ansatz can still lose trainable signal as noisy depth grows. Error mitigation may reduce bias, but its sampling overhead and stability must be included before claiming that it restores trainability.
Gradient-free optimization does not evade concentration
Section titled “Gradient-free optimization does not evade concentration”Derivative-free methods compare nearby or modeled cost values. In a barren plateau, those differences are suppressed along with gradients. Resolving them still demands high precision. Changing optimizers can improve finite-size behavior, but it does not remove an information-theoretic signal-to-noise bottleneck.
Worst-case hardness
Section titled “Worst-case hardness”Bittel and Kliesch show that training broad classes of variational algorithms is NP-hard in the worst case, even for some systems whose underlying quantum dynamics are classically tractable. This result rules out a universal efficient classical optimizer under standard complexity assumptions. It does not prove that every physical instance, ansatz, or initialization is hard. Complexity statements must retain their quantifiers.
Designing for Trainability
Section titled “Designing for Trainability”There is no single cure, but several design principles can improve the available signal.
Use structure before capacity
Section titled “Use structure before capacity”Choose initial states, generators, symmetries, and connectivity from the problem. Verify that the target is reachable in the chosen sector. Add depth only when a shallower family fails a prespecified approximation test.
Problem inspiration is not itself a proof against barren plateaus. The dynamical Lie algebra generated by the ansatz, the initial state, and the observable can still produce concentration. Numerical gradient scaling over a range of sizes is useful evidence, but a narrow range should not be fitted to an asymptotic law with false confidence.
Initialize near a meaningful map
Section titled “Initialize near a meaningful map”Options include:
- parameters corresponding to a known limiting solution;
- identity-block initialization, where new gate blocks initially compose to the identity;
- parameter transfer from a nearby instance or smaller system;
- layerwise growth, with new layers initialized not to perturb the current state;
- restricted randomization around a structured point.
These methods can preserve initial gradients. They can also bias the search toward one basin, so multiple structured seeds and transparent failure reporting remain important.
Match the cost to the information scale
Section titled “Match the cost to the information scale”Prefer observables whose changes are resolvable at the available shot budget. Normalize weighted sums so that one large coefficient does not dominate optimizer scaling. For constraints on expectation values, one possible penalty is
This penalizes ; it does not generally enforce the stronger condition . For a Hermitian operator, does enforce support in its kernel. For example, let and . The state has but and no one-particle component. A penalty on detects that violation.
Squaring a sample mean adds another distinction: for independent shots. Thus even the intended mean-value penalty has a finite-sample bias unless corrected or estimated with independent batches. Penalties also change curvature and measurement cost. A coefficient too small permits invalid states; one too large can make the landscape ill-conditioned. Report the chosen scale and a constraint-violation curve.
Grow precision with optimization
Section titled “Grow precision with optimization”Early iterations may need only the direction of a large improvement. Late iterations may require enough shots to distinguish small changes. An adaptive policy can increase shots according to estimated variance, gradient norm, or trust-region acceptance.
For an estimated component with standard error , a simple signal diagnostic is
This ratio is not a universal stopping test, especially after selecting the largest component, but it exposes updates driven mainly by measurement noise. Prespecify how the shot budget changes when is small.
Noise, Drift, and Mitigation
Section titled “Noise, Drift, and Mitigation”On hardware, optimization targets the time-dependent implemented objective . If calibration changes during the loop, the optimizer sees a moving surface:
The first term on the right is intended optimization; the last term is drift. Interleaving reference circuits, randomizing execution order, and blocking paired parameter-shift circuits can help distinguish them. A single calibration snapshot before a long run is rarely enough to establish stationarity.
Noise can have several qualitatively different effects:
- bias: the minimum value and minimizer move;
- variance: shot-to-shot outcomes broaden;
- smoothing: high-frequency landscape features are attenuated;
- false structure: coherent errors introduce new parameter dependence;
- leakage or loss: the effective state space and retention probability change;
- nonstationarity: the objective changes during training.
Error mitigation changes the estimator. Readout correction, probabilistic error cancellation, zero-noise extrapolation, symmetry verification, and postselection have different assumptions and overheads. A mitigated objective can have lower bias and much larger variance. Optimization on mitigated values also creates adaptive selection effects. Compare raw and mitigated estimates with their uncertainties and rejected-trial costs. The noise overview explains the physical channels; each mitigation method needs its own assumptions about calibration and sampling.
A One-Qubit Worked Example
Section titled “A One-Qubit Worked Example”Take
The exact state is
so
The parameter-shift rule returns
Each measurement is a random variable with
With shots at each shifted angle, the gradient estimator has variance
At , the two shifted means are and , so the derivative is . With shots per shifted point, its standard error is . This costs state preparations, even though the derivative formula has only two terms.
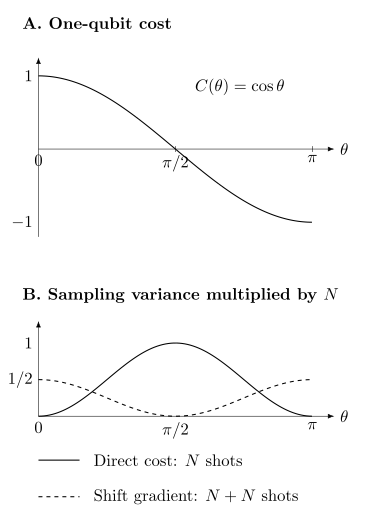
For measured in , the cost is . The lower panel plots variance multiplied by : for direct shots, and for shots at each of two shifted angles. The gradient estimate therefore uses twice as many preparations as the direct cost estimate.
Near , the gradient is small because this point is a maximum of the cost, not because of a barren plateau: there is no system-size scaling here. Near , both shifted circuits have deterministic ideal outcomes, but hardware noise can reintroduce variance and bias. Even this trivial example separates exact calculus, shot statistics, and physical implementation.
Stopping without mistaking noise for improvement
Section titled “Stopping without mistaking noise for improvement”A small estimated gradient can mean a stationary point, inadequate shots or a poor parameterization. A stopping rule should distinguish “the task criterion is met” from “no further useful improvement was resolved before the budget ran out.” Fresh measurements of the selected point help separate its actual performance from favorable noise encountered during selection.
For repeated statistical tests, a fixed-point confidence interval does not automatically remain valid after choosing when to stop. Use a simultaneous error allocation or a method valid under the stated adaptive sampling. Exercise8 gives a simple conservative construction. For a claim across instances, also evaluate new instances from a specified distribution; fresh shots on one selected instance answer a different question.
Check small cases with exact simulation and assess properties not fixed by the training objective, such as constraint violations or held-out observables. The algorithmic benchmarking page develops comparisons across problem instances.
Resource Accounting
Section titled “Resource Accounting”Let iteration request circuit configurations with attempted shot counts , including subsequently rejected outcomes. A basic quantum acquisition count is
Counting attempted shots prevents postselection from hiding rejected trials. Reset time, extra calibration or mitigation circuits, queueing and classical work still affect elapsed time. One possible decomposition is
For a batch-access device, quantum–classical round trips may dominate. Two optimizers with the same iteration count can request very different numbers of shots, shifted circuits or metric measurements. Compare total work, including failed seeds and tuning, at the same task accuracy and success probability. Resource estimation explains conversions from abstract circuit counts to a specified implementation.
The appropriate classical comparison depends on the task: exact diagonalization, tensor networks, Monte Carlo, classical variational families or optimization heuristics may be relevant. A small instance that is classically simulable can validate an experiment without showing an advantage. A broader advantage claim requires representative scaling and a comparably tuned classical method, as discussed in verification of quantum advantage.
Common pitfalls
Section titled “Common pitfalls”An ansatz is not yet an algorithm. The parameterized circuit needs an objective, a measurement procedure and an update rule. Useful output must be assessed separately from a decreasing training trace.
A flat trace is not by itself a barren plateau. Check ordinary stationarity, inactive parameters, measurement resolution and drift before studying gradient scaling across sizes and initializations.
A best-of-many run is not typical performance. Fresh measurements can assess that selected run, but all attempted runs contribute to its acquisition cost. Report a typical-run claim and a best-of-many procedure separately.
Where Variational Algorithms Are Used
Section titled “Where Variational Algorithms Are Used”VQAs appear in ground- and excited-state estimation, combinatorial optimization, dynamical simulation, linear-system objectives, state preparation, compilation, error correction, quantum machine learning, and metrology. These applications share hybrid optimization but differ in what their objectives certify.
The connection to Optimal Control is especially close: both optimize parameterized quantum evolution. Control usually treats physical pulse fields and dynamical constraints as primary, whereas circuit VQAs often treat a gate-level ansatz and an algorithmic objective as primary. The mathematical tools overlap, but their physical constraints and useful outputs differ.
The hybrid architecture, gate-specific gradient identities and cited concentration theorems are established mathematical tools. Their combination does not guarantee efficient optimization of arbitrary instances. Current questions about scalable trainability and utility are discussed in quantum algorithm discovery and negative results and limitations.
Exercises
Section titled “Exercises”1. Derive the parameter-shift rule
Section titled “1. Derive the parameter-shift rule”Let
Show directly that an expectation is a trigonometric polynomial of the form , and derive the two-point shift rule.
Solution
Because ,
Substituting this expression and its adjoint around the observable produces terms proportional to , , and . Double-angle identities therefore give
Its derivative is
Meanwhile,
Thus the shifted expression equals exactly.
2. Allocate shots between observables
Section titled “2. Allocate shots between observables”An objective is
Pilot measurements estimate single-shot standard deviations and . Allocate shots to minimize the variance when the terms are measured independently.
Solution
The continuous optimum obeys
The weights are
Therefore
and
Integer rounding can be adjusted to preserve the total. The derivation assumes independent settings and known stable variances; grouping or drift changes the allocation problem.
3. Separate bias from variance
Section titled “3. Separate bias from variance”A simulator predicts . Hardware repetitions give with standard error . Explain what increasing the shot count by a factor of can and cannot establish.
Solution
Under independent stationary sampling, the standard error falls by a factor of , to about . This measures the hardware estimand more precisely. It does not force that estimand toward . The observed difference of may be physical bias from noise, compilation, readout, or drift. More shots distinguish a stable discrepancy more sharply but do not diagnose or remove it.
4. Identify a redundant parameter
Section titled “4. Identify a redundant parameter”Consider
acting on an arbitrary state. Find a null direction of the state-space metric.
Solution
Because rotations about the same axis compose,
Only the sum matters. The displacement
leaves the unitary exactly unchanged, so is a null direction of the Fubini–Study metric for every input state. The two-coordinate model has at most one effective local dimension.
5. Diagnose a flat trace
Section titled “5. Diagnose a flat trace”A ten-qubit run shows nearly constant cost for 50 iterations. List four checks needed before calling this a barren plateau.
Solution
Check whether:
- gradients and cost differences are below the estimator’s resolution;
- the initialization is already near a stationary point;
- symmetries or redundant parameters make the chosen directions inactive;
- calibration drift or optimizer step sizes obscure genuine changes.
Then study gradient distributions over initializations and a sequence of problem sizes. A barren-plateau claim requires exponential scaling under a specified ensemble, not one flat optimization history.
6. Count a naive gradient batch
Section titled “6. Count a naive gradient batch”An objective has 40 independently measured groups. A circuit has 120 parameters, each appearing in one Pauli rotation. A full parameter-shift gradient uses 2,000 shots per group and shifted point. How many shots does one gradient batch use?
Solution
There are two shifted points per parameter, so the number of group evaluations is
At 2,000 shots each,
This excludes the unshifted objective, metric estimation, calibration, validation, rejected trials, and repeated seeds. The example shows why circuit depth alone is a poor proxy for VQA cost.
7. A correct mean can hide the wrong particle number
Section titled “7. A correct mean can hide the wrong particle number”For , compare with . Compute , and the probability of measuring . Then explain the finite-sample bias of estimating by the square of a sample mean.
Solution
Both states have . For , with certainty and . For , the outcomes are and with equal probabilities, so the squared deviation is always and never occurs. Matching the mean is not the same as occupying the one-particle sector.
On the Bell state, measuring gives equally. For independent samples, , even though . One unbiased estimator of the squared mean is the average product of distinct samples,
It can be negative on one finite data set; unbiasedness is a statement about its mean over repeated experiments. Alternatively, multiply sample means from two independent batches.
8. Design a stopping rule under shot noise
Section titled “8. Design a stopping rule under shot noise”Suppose at most candidate points are assessed, possibly chosen adaptively. At assessment , collect fresh independent outcomes in at the selected point. Construct simultaneous bounds with total failure probability at most , and give a rule for accepting a target . Assume each assessment samples a stable mean; this does not bound physical model bias.
Solution
Conditioned on the preceding history, Hoeffding’s inequality gives
Choose . Each assessment then fails with probability at most , including after averaging over the history. A union bound shows that all intervals hold together with probability at least .
Accept a point only when . Otherwise continue, or stop at the fixed budget and report that the target was not established. The guarantee survives adaptive choice of the points because each test uses fresh shots and the total error was allocated across all possible assessments. It does not prove that an unaccepted point is bad, that the selected point is a global optimum, or that the physical mean equals the ideal objective.
References
Section titled “References”- A. Arrasmith, M. Cerezo, P. Czarnik, L. Cincio, and P. J. Coles, “Effect of barren plateaus on gradient-free optimization,” Quantum 5, 558 (2021), doi:10.22331/q-2021-10-05-558.
- L. Banchi and G. E. Crooks, “Measuring analytic gradients of general quantum evolution with the stochastic parameter shift rule,” Quantum 5, 386 (2021), doi:10.22331/q-2021-01-25-386.
- K. Bharti et al., “Noisy intermediate-scale quantum algorithms,” Reviews of Modern Physics 94, 015004 (2022), doi:10.1103/RevModPhys.94.015004.
- L. Bittel and M. Kliesch, “Training variational quantum algorithms is NP-hard,” Physical Review Letters 127, 120502 (2021), doi:10.1103/PhysRevLett.127.120502.
- M. Cerezo et al., “Variational quantum algorithms,” Nature Reviews Physics 3, 625–644 (2021), doi:10.1038/s42254-021-00348-9.
- M. Cerezo, A. Sone, T. Volkoff, L. Cincio, and P. J. Coles, “Cost function dependent barren plateaus in shallow parametrized quantum circuits,” Nature Communications 12, 1791 (2021), doi:10.1038/s41467-021-21728-w.
- S. Endo, Z. Cai, S. C. Benjamin, and X. Yuan, “Hybrid quantum-classical algorithms and quantum error mitigation,” Journal of the Physical Society of Japan 90, 032001 (2021), doi:10.7566/JPSJ.90.032001.
- E. Grant, L. Wossnig, M. Ostaszewski, and M. Benedetti, “An initialization strategy for addressing barren plateaus in parametrized quantum circuits,” Quantum 3, 214 (2019), doi:10.22331/q-2019-12-09-214.
- T. Haug, K. Bharti, and M. S. Kim, “Capacity and quantum geometry of parametrized quantum circuits,” PRX Quantum 2, 040309 (2021), doi:10.1103/PRXQuantum.2.040309.
- Z. Holmes, K. Sharma, M. Cerezo, and P. J. Coles, “Connecting ansatz expressibility to gradient magnitudes and barren plateaus,” PRX Quantum 3, 010313 (2022), doi:10.1103/PRXQuantum.3.010313.
- J. M. Kübler, A. Arrasmith, L. Cincio, and P. J. Coles, “An adaptive optimizer for measurement-frugal variational algorithms,” Quantum 4, 263 (2020), doi:10.22331/q-2020-05-11-263.
- M. Larocca et al., “Diagnosing barren plateaus with tools from quantum optimal control,” Quantum 6, 824 (2022), doi:10.22331/q-2022-09-29-824.
- J. R. McClean, J. Romero, R. Babbush, and A. Aspuru-Guzik, “The theory of variational hybrid quantum-classical algorithms,” New Journal of Physics 18, 023023 (2016), doi:10.1088/1367-2630/18/2/023023.
- J. R. McClean, S. Boixo, V. N. Smelyanskiy, R. Babbush, and H. Neven, “Barren plateaus in quantum neural network training landscapes,” Nature Communications 9, 4812 (2018), doi:10.1038/s41467-018-07090-4.
- K. Mitarai, M. Negoro, M. Kitagawa, and K. Fujii, “Quantum circuit learning,” Physical Review A 98, 032309 (2018), doi:10.1103/PhysRevA.98.032309.
- A. Peruzzo et al., “A variational eigenvalue solver on a photonic quantum processor,” Nature Communications 5, 4213 (2014), doi:10.1038/ncomms5213.
- J. Preskill, “Quantum computing in the NISQ era and beyond,” Quantum 2, 79 (2018), doi:10.22331/q-2018-08-06-79.
- M. Schuld, V. Bergholm, C. Gogolin, J. Izaac, and N. Killoran, “Evaluating analytic gradients on quantum hardware,” Physical Review A 99, 032331 (2019), doi:10.1103/PhysRevA.99.032331.
- S. Sim, P. D. Johnson, and A. Aspuru-Guzik, “Expressibility and entangling capability of parameterized quantum circuits for hybrid quantum-classical algorithms,” Advanced Quantum Technologies 2, 1900070 (2019), doi:10.1002/qute.201900070.
- P. Singkanipa and D. A. Lidar, “Beyond unital noise in variational quantum algorithms: noise-induced barren plateaus and limit sets,” Quantum 9, 1617 (2025), doi:10.22331/q-2025-01-30-1617.
- A. Skolik, J. R. McClean, M. Mohseni, P. van der Smagt, and M. Leib, “Layerwise learning for quantum neural networks,” Quantum Machine Intelligence 3, 5 (2021), doi:10.1007/s42484-020-00036-4.
- J. C. Spall, “Multivariate stochastic approximation using a simultaneous perturbation gradient approximation,” IEEE Transactions on Automatic Control 37, 332–341 (1992), doi:10.1109/9.119632.
- J. Stokes, J. Izaac, N. Killoran, and G. Carleo, “Quantum natural gradient,” Quantum 4, 269 (2020), doi:10.22331/q-2020-05-25-269.
- R. Sweke et al., “Stochastic gradient descent for hybrid quantum-classical optimization,” Quantum 4, 314 (2020), doi:10.22331/q-2020-08-31-314.
- B. van Straaten and B. Koczor, “Measurement cost of metric-aware variational quantum algorithms,” PRX Quantum 2, 030324 (2021), doi:10.1103/PRXQuantum.2.030324.
- S. Wang et al., “Noise-induced barren plateaus in variational quantum algorithms,” Nature Communications 12, 6961 (2021), doi:10.1038/s41467-021-27045-6.
- D. Wierichs, J. Izaac, C. Wang, and C. Y.-Y. Lin, “General parameter-shift rules for quantum gradients,” Quantum 6, 677 (2022), doi:10.22331/q-2022-03-30-677.