

QAOA
QAOA is a family of parameterized quantum states built by alternating an objective-dependent phase separator with a mixer. This page uses one maximization convention throughout: larger eigenvalues of the diagonal cost operator are better, and the circuit applies before in each layer. The original construction is the quantum approximate optimization algorithm of Farhi, Goldstone, and Gutmann (2014); constrained and more general variants are often called the quantum alternating operator ansatz. The ansatz supports exact finite-depth analysis and useful family-specific results, but neither its form nor any result below establishes a generic end-to-end practical speedup over classical optimization.
Helpful background. Variational quantum algorithms explains how repeated measurements guide parameter optimization. Pauli matrices supplies the spin rotations used below.
QAOA as Alternating Cost-and-Mixer Dynamics
Section titled “QAOA as Alternating Cost-and-Mixer Dynamics”Let a classical score be assigned to each -bit string. Its diagonal operator and the standard transverse-field mixer are
The corresponding unitaries are
changes phases according to objective value but leaves computational-basis probabilities unchanged. then mixes amplitudes between strings that differ in one bit. Alternating the two can turn relative phases into a probability bias toward high-scoring strings. That interference mechanism is more precise than saying that the circuit “searches all answers at once”: useful bias depends on the encoded objective, initial state, mixer, angles, and depth.
“QAOA” is used for three related objects that should not be conflated. The original quantum approximate optimization algorithm uses a cost operator, the transverse-field mixer, the uniform initial state, and shared angles at a fixed level . The broader quantum alternating operator ansatz replaces the initial state, phase separator, or mixer to encode constraints and problem structure, as formalized by Hadfield et al. (2019). A Hamiltonian variational ansatz alternates physically motivated noncommuting Hamiltonian terms and may target a quantum state rather than a classical bit string; early examples appear in Wecker, Hastings, and Troyer (2015). The last usage is QAOA-like, but a computational-basis measurement is not generally an energy sample for a non-diagonal target Hamiltonian.
To use this state family for optimization, choose the angles, measure bitstrings, score them and return a candidate. The choice of angles can use analytic formulas, classical simulation or a measurement-based optimizer. A low circuit depth alone does not specify how much work that search requires. The examples below first fix the angles analytically so that their quantum probabilities can be studied independently of optimization.
From a Classical Objective to a Cost Hamiltonian
Section titled “From a Classical Objective to a Cost Hamiltonian”Binary variables and diagonal operators
Section titled “Binary variables and diagonal operators”For , the computational-basis eigenvalue relation gives
Thus a quadratic unconstrained binary objective
becomes an Ising operator containing a constant, one-body terms, and two-body terms. The substitution is an equality on every basis state, not a continuous relaxation. Higher-degree monomials similarly become products of diagonal Pauli operators, although reducing their locality may require ancillas and penalties whose costs belong in the encoding.
Here the quadratic sum is over distinct variables. If a QUBO matrix notation includes diagonal terms, reduce them first with and absorb their coefficients into the linear terms before applying the two-variable substitution.
For weighted MaxCut, an edge is cut exactly when the endpoint bits differ. Its indicator is
so, for weights ,
Every term is diagonal and all terms commute. Consequently,
is an exact factorization. Calling it a Trotter approximation would introduce an error that is absent. A compiler may discard the product of constant-term phases, but it must retain the coefficient scale that determines the useful angle and the physical rotation precision.
Penalties and objective scale
Section titled “Penalties and objective scale”Constraints can be encoded by maximizing
where the feasible set is nonempty, on feasible strings and on infeasible strings. If the unpenalized objective is bounded by on all strings, then the crude sufficient condition
makes every infeasible penalized value at most , whereas every feasible value is at least . This condition is sufficient, not necessary. A tighter problem-specific gap can permit a much smaller penalty. Large coefficients expand the phase range, demand finer control, can worsen objective-estimation variance, and may require additional high-locality decomposition or ancillas. “Unconstrained” in QUBO therefore does not mean cost-free encoding.
Affine changes also require care. For
the identity contribution produces only the global phase , while rescales the effective angle from to . Positive preserves the maximizing strings; negative reverses their ranking, and removes all objective dependence. It is safe to drop during state preparation if its value is restored when reporting the original objective. It is not safe to assume an approximation ratio is shift invariant: and are generally different. Keep the original objective and its offset when comparing a mean score with the optimum.
The Standard Depth-p Circuit
Section titled “The Standard Depth-p Circuit”Shared angles and operator order
Section titled “Shared angles and operator order”At level , the declared state is
The rightmost operation acts first. The standard unconstrained construction uses
so the phase separator acts on a uniform superposition before the mixer in each layer. There are shared real parameters: every cost term uses the same and every mixer term uses the same within layer . Parameter sharing is part of the ansatz and is distinct from a more general circuit that assigns an angle to each edge or vertex.
The maximization signs matter. Authors who minimize a problem Hamiltonian, define , reverse the mixer sign, or write products in the opposite order obtain angle formulas related by sign changes or reordered coordinates. Transcribing a reported optimum without transcribing its generator and order conventions is therefore unsafe.
The ideal expectation and output distribution are
is an average score. It is not the probability of sampling an optimum, nor does it determine the whole tail of . Two angle sets can have the same expectation but very different probabilities of returning a usable candidate. If the aim is to obtain a good bitstring, examine the high-score part of the distribution as well as its mean.
MaxCut at p = 1
Section titled “MaxCut at p = 1”The general depth-one edge formula
Section titled “The general depth-one edge formula”Consider unweighted MaxCut on a simple graph under the exact convention above, with and . For an edge , let
and let be the number of triangles containing that edge. Then the ideal expected contribution of is
The result follows by evaluating the edge observable in the Heisenberg picture. Mixer conjugation sends each endpoint into a linear combination of and with angle . Cost terms incident on one endpoint rotate the resulting into components. Expectation in the plus state removes every Pauli string containing a remaining or . Neighbors unique to one endpoint supply powers of ; common neighbors create paired paths whose interference produces the final triangle term. Terms outside the radius-one edge neighborhood cancel from this local expectation.
This is the corrected depth-one expression of Wang et al.. The last term vanishes only when (or at special angles), so the triangle-free expression cannot be applied to a graph merely because it is regular. The hypotheses also exclude weighted edges unless the angle dependence is rederived with each incident weight.
For one isolated edge, , and the expression reduces to
At and , the cut expectation is one. The complete distribution is derived in Exercise 2: each of the two cut bitstrings has probability one half.
Triangle-free regular graphs
Section titled “Triangle-free regular graphs”For a simple triangle-free -regular graph with , every edge has and . Summing identical edge expectations gives
Choose the positive branch. The factor is maximized by . For ,
An interior maximum in therefore satisfies
Substitution yields
This formula gives the ideal depth-one mean divided by the number of edges, not an optimum-hit probability. For a nonempty graph the maximum cut obeys , so
Thus the displayed fraction is a lower bound on the expected approximation ratio, even when is unknown. It equals that ratio for a bipartite graph, whose entire edge set can be cut. It need not equal it for a nonbipartite triangle-free graph. Neither quantity guarantees the score of every individual measurement. The case is the isolated-edge value at .
For and nine edges, the formula gives . At its representative optimum the ideal Hessian is diagonal:
Those curvatures describe this two-parameter ideal landscape locally; they do not measure finite-shot optimizer difficulty or noise sensitivity by themselves.
Expectation, Sampling, and Approximation Quality
Section titled “Expectation, Sampling, and Approximation Quality”Expected score and threshold success
Section titled “Expected score and threshold success”QAOA produces a distribution, so “performance” is incomplete without a functional of that distribution and an acceptance rule. For a score bounded by and , the normalized expectation
lies in when . If the true optimum is known and the nonnegative objective has not been shifted, is an expected approximation ratio. These normalizations answer different questions and can rank methods differently after offsets or penalties.
| Quantity | Definition | Interpretation |
|---|---|---|
| Expected objective | Mean score of one draw. | |
| Expected approximation ratio | Mean divided by the positive optimum of an unshifted nonnegative objective. | |
| Threshold probability | Chance that one draw meets the target score. | |
| Best of samples | Score of the candidate returned after independent draws. | |
| Feasibility probability | Fraction of draws satisfying the constraint before any rejection. |
An expectation does not fix a tail probability. A distribution concentrated just below can have a larger expectation but a smaller than a broader distribution. Conversely, a rare optimum can coexist with a modest mean. If the application consumes one best candidate, report the empirical or modeled distribution of and the total cost of all draws, not only the value of the selected string.
For one-shot threshold probability , independent repetitions hit the threshold at least once with probability . Requiring failure probability at most gives
The expression is interpreted at its boundaries: if , no finite number of repetitions can succeed; if , one draw suffices and the logarithmic quotient is replaced by that direct conclusion. Independence is an assumption. Drift or adaptive changes between runs can invalidate the geometric model.
Shot uncertainty and independent validation
Section titled “Shot uncertainty and independent validation”Suppose independent computational-basis shots produce scores in and . Hoeffding’s inequality gives
For normalized cut fractions in , demanding absolute error with failure probability is guaranteed by
This distribution-free bound is conservative and addresses estimation of a fixed state’s mean. It does not say that 2952 shots find an optimum, estimate every bucket probability accurately, or suffice for an adaptive optimizer. Empirical Bernstein, likelihood, or exact binomial methods can be sharper when their assumptions and stopping rules are declared.
Choosing the best-looking angles from noisy estimates tends to select favorable measurement fluctuations. Fresh measurements at the selected angles estimate their performance without reusing the fluctuation that made those angles look favorable. Generalizing a fitted parameter rule to other graphs also requires testing on graphs that were not used to choose it. Count both the measurements used to choose the angles and those used to assess or sample the final state.
Parameter Domains, Optimization, and Transfer
Section titled “Parameter Domains, Optimization, and Transfer”Conditional periodicities
Section titled “Conditional periodicities”Period reductions depend on spectra and symmetries. Since , the transverse mixer satisfies
so has period up to a global phase for the standard mixer. For an unweighted MaxCut objective, every eigenvalue is an integer and
Arbitrary real edge weights need not have a common nonzero period. Commensurate rationally related weights can recover a rescaled period, but it must be derived from the actual spectrum rather than assumed from the unweighted case.
For the usual MaxCut initial state, a stronger symmetry holds. Let . Weighted or unweighted MaxCut satisfies , the standard mixer satisfies , and . Since
a shift of any one mixer angle changes the complete standard QAOA state only by a global phase. Every bitstring probability is unchanged, and complementary bitstrings already have equal probabilities. A bitstring-dependent scoring rule cannot distinguish these two identical distributions.
For an asymmetric initial state, the same shift instead complements the output distribution; the cut mean remains invariant but individual bitstring probabilities need not. Local fields, pinned variables or different mixer generators require a fresh symmetry calculation. A smaller parameter domain should follow from the actual state and generators, not from the name QAOA.
Layer growth and parameter transfer
Section titled “Layer growth and parameter transfer”Let be the globally optimized ideal expectation over all level- angles. Appending a layer with applies the identity, so the level- family is embedded in level and
This expressivity statement assumes exact gates and a global optimum. A finite optimizer can miss the embedded point; a noisy implementation can make an added identity only nominally identity; and increased compilation, estimation, or calibration cost can reduce achieved quality. Observed best-of-budget performance therefore need not be monotone in .
Reachability can also fail at insufficient depth even before optimization and noise are considered, as emphasized by Akshay et al. (2020). Parameter interpolation from level to , smooth Fourier parameterizations, and transfer across graph ensembles can reduce search cost on some structured families; Zhou et al. (2020) develops representative strategies and mechanisms. These are heuristics. Angles learned for one graph family or coefficient scale may perform poorly on another. Smooth-looking schedules do not by themselves prove convergence.
Hard Constraints and Alternating Operators
Section titled “Hard Constraints and Alternating Operators”Feasibility preservation is not connectivity
Section titled “Feasibility preservation is not connectivity”For a feasible set , define
If the initial state lies in the feasible subspace and
then preserves that subspace. A diagonal phase separator also preserves it. This removes infeasible measurement outcomes in the ideal circuit, but the commutator condition is not enough for a useful search. Construct a graph whose vertices are feasible strings and whose edges join pairs connected by a nonzero off-diagonal matrix element of . If that transition graph is disconnected, no choice of angles can move amplitude between its components. Any component absent from the initial support stays absent. If useful solutions lie only in such components, change the preparation or mixer. Initial support in several components is possible, but their total probabilities remain separately conserved.
The standard example for a fixed Hamming-weight constraint is
Writing
shows that
each term exchanges 10 and 01 while annihilating 00 and 11. It
therefore commutes with the number operator
If the mixer graph is connected, sequences of exchanges connect all bitstrings of a fixed nontrivial weight. If it is disconnected, the number of ones in each component is separately conserved, fragmenting the feasible space even though total Hamming weight is preserved.
Graph connectivity is not full quantum controllability. For example, in the one-excitation sector of three qubits, take the complete-graph XY mixer and assign scores to the three basis states. From their uniform superposition, both the cost and mixer preserve exchange of the first two states. Those amplitudes remain equal at every level, so neither optimal bitstring can acquire probability above , although the transition graph is connected. The circuit can favor the pair without preparing either member alone.
There is also a compilation distinction from MaxCut. XY terms on overlapping edges generally do not commute. For ,
at generic . Disjoint-edge terms do commute. A specified sequence of edge-exchange gates is a valid alternating-operator mixer and preserves Hamming weight exactly, but it is a different unitary from the exponential of their sum unless an approximation with controlled error is intended.
This approach differs from the penalty . A penalty retains an easy transverse mixer but visits infeasible strings and introduces the coefficient-range and compilation costs discussed above. A constrained mixer can avoid penalties, but preparing a feasible superposition and compiling a connected mixer may be difficult. Neither approach dominates without an instance-specific resource and reachability analysis. The alternating-operator framework of Hadfield et al. (2019) makes these choices explicit.
Compiling cost and mixer layers
Section titled “Compiling cost and mixer layers”Logical layer costs
Section titled “Logical layer costs”For unweighted MaxCut, one logical cost layer contains two-qubit interactions, and one standard mixer layer contains single-qubit rotations because
Under all-to-all connectivity, disjoint edges can execute together. For a simple graph, an edge coloring partitions into matchings, and Vizing’s theorem gives
With one native interaction per edge, the two-qubit depth of a cost layer is and its mixer adds one single-qubit layer, giving logical alternating depth under these assumptions. The native two-qubit interaction count is and two-qubit depth is . Multigraphs require a different edge-coloring bound; restricted connectivity and crosstalk exclusions can require additional matchings or routing.
Compiled and experimental costs
Section titled “Compiled and experimental costs”Up to a global phase, an edge separator is a rotation. With , one conventional implementation is a CNOT––CNOT sequence. It uses entangling gates, whereas a native implementation uses . On a matching, the two CNOT rounds are sequential, so the ideal entangling depth becomes rather than the native- depth ; the intervening single-qubit rotations and mixer layers must also be scheduled. Gate orientation, echoed implementations, synthesis, and hardware topology can change both counts and depth.
These counts describe one circuit execution. For example, evaluated angle sets with shots each already require state preparations, before final sampling. Routing, state preparation, calibration, mitigation and discarded outcomes can add further work. Noise changes the implemented probability distribution: increasing the number of shots reduces sampling uncertainty but does not remove this systematic difference from the ideal model. See resource estimation for conversion to a physical implementation.
There is one important measurement simplification. A computational-basis shot supplies a complete bitstring, from which every diagonal MaxCut clause can be evaluated simultaneously. Thus clauses do not imply noncommuting measurement settings. That property is special to a diagonal classical objective. For a QAOA-like ansatz targeting a non-diagonal Hamiltonian, basis rotations, grouping, covariance, and termwise allocation return, as explained in VQE.
Guarantees, Locality, and Classical Competition
Section titled “Guarantees, Locality, and Classical Competition”Fixed-depth locality
Section titled “Fixed-depth locality”At level , a local edge observable propagated backward through the circuit can only spread through rounds of incident cost interactions. On a graph of maximum degree , a cycle-free radius- neighborhood about the two endpoints contains at most
vertices. For , the corresponding bound is . Cycles and overlap can reduce the actual neighborhood. An exact local expectation can therefore be computed from a statevector on this light cone, with cost exponential in but independent of the total when and are fixed.
This observation explains both analytic tractability at low depth and a limitation of local information. Farhi, Gamarnik, and Gutmann (2020) construct worst-case graph examples and depth regimes in which failure to see the whole graph limits what local QAOA can distinguish. The light-cone calculation does not by itself provide an efficient classical sampler for the complete correlated output distribution. Local expectation computation, marginal recovery, exact sampling, approximate sampling, and optimization are separate computational tasks.
For a sum of bounded local clauses on a bounded-degree graph at fixed , only clauses with overlapping light cones can have nonzero covariance in the ideal plus-state calculation. Each clause overlaps only a bounded number of others, so . This supports concentration of the extensive score under those hypotheses, but it still does not determine the rare optimum tail.
Comparing optimization guarantees
Section titled “Comparing optimization guarantees”Several statements commonly grouped under “QAOA performance” are logically independent. Reachability asks whether the ansatz contains a useful state. Trainability asks whether an allowed procedure can find useful parameters. Symmetry protection can either exclude invalid states or trap the circuit in an unhelpful sector; Bravyi et al. (2020) prove such obstacles for specified symmetric shallow variational settings. Conditional output- sampling hardness, such as the complexity-theoretic route proposed by Farhi and Harrow (2016), does not imply that sampled strings have high objective value or that a complete optimization procedure beats classical solvers.
For nonnegative-weight MaxCut, a central classical reference point is the Goemans–Williamson semidefinite relaxation and randomized hyperplane rounding. Its worst-case guarantee is
as proved by Goemans and Williamson (1995). The guarantee, an achieved instance score, and QAOA’s expected cut fraction are different quantities, but a comparison must nevertheless use the same graph, weights, output rule, and total-cost boundary. Exact branch-and-cut, semidefinite variants, local search, message passing, tensor methods, and modern heuristic portfolios may be more relevant than one universal baseline. Random assignment, with mean half the total weight, is a sanity check rather than a competitive comparator.
Classical local algorithms can also outperform the standard depth-one QAOA benchmark in stated triangle-free bounded-degree regimes; Hastings (2019) gives explicit bounded-depth comparisons. Such a result does not rule out deeper QAOA, different mixers, or other families. It does rule out presenting the depth-one analytic value as an uncontested classical separation. The durable conclusion is narrower: QAOA is a rich and analyzable ansatz framework with important family-dependent results, while shallow depth, a smooth landscape, sampling hardness, or beating random assignment alone establishes no generic end-to-end practical advantage.
Relations to Variational, Adiabatic, and Annealing Methods
Section titled “Relations to Variational, Adiabatic, and Annealing Methods”QAOA is a VQA once its angles are chosen by an adaptive classical search. The general estimator, optimizer, barren-plateau, geometry, noise, and validation questions remain at Variational Quantum Algorithms; this page adds the alternating-operator structure, MaxCut formulas, output metrics, and constrained mixers. Hamiltonian variational ansatzes use the same alternating idea for quantum-state objectives, but non-diagonal energy measurement must not be replaced by scoring one computational-basis string.
There is also a controlled relation to adiabatic evolution. Under this page’s maximization convention, an adiabatic path can interpolate from a Hamiltonian whose ground state is , such as , toward . A product-formula discretization produces alternating exponentials with angles fixed by time steps and schedule coefficients; because the Hamiltonians carry minus signs, those angles must be translated carefully into the convention. Such digitized schedules form a special subset of QAOA parameters. Arbitrarily optimized angles can be strongly nonadiabatic and need not approximate any monotone continuous path.
Conversely, a large- existence argument based on increasingly fine digitization supplies neither polynomially bounded , a trainable schedule, a noise-tolerant implementation, nor a practical runtime. Adiabatic Quantum Computation explains the relevant spectral-gap and schedule assumptions. Quantum annealing also treats finite-time dynamics and environmental effects, which are absent from the ideal unitary circuit above.
Device implementations, including the planar superconducting-processor study of Harrigan et al. (2021), are valuable finite experiments rather than timeless algorithmic guarantees. For experimental interpretation and comparisons, see optimization case studies.
Quantum algorithms for optimization compares this approach with search, quantum walks, adiabatic methods and other optimization procedures.
Small graphs: mean score and returned solutions
Section titled “Small graphs: mean score and returned solutions”A two-vertex graph gives the simplest interference calculation: the angles , put equal probability on 01 and 10 and zero probability on 00 and 11. Exercise 2 derives this result. The next two examples show why triangles and probability distributions matter.
The triangle correction
Section titled “The triangle correction”For the three-cycle , every edge has . At , the general formula gives, per edge,
and therefore
The only possible cut values of a triangle are zero and two. Hence the optimum-hit probability is not but
Dropping the triangle term would predict a different expectation. This small graph therefore gives a useful test of the common-neighbor term.
K₃,₃ expectation and sampling
Section titled “K₃,₃ expectation and sampling”Label the two parts of by and , with all nine cross edges. This is a simple, triangle-free, -regular graph. At
the regular-graph formula gives
and, because the optimum is ,
Complete enumeration gives the following distribution. The middle column is the number of the 64 bitstrings with that classical cut value; the last column sums their ideal probabilities, rounded to six decimal places.
| Cut value | Bitstring count | Probability (rounded) |
|---|---|---|
| 0 | 2 | 0.000867 |
| 3 | 12 | 0.070428 |
| 4 | 18 | 0.080112 |
| 5 | 18 | 0.393846 |
| 6 | 12 | 0.120545 |
| 9 | 2 | 0.334202 |
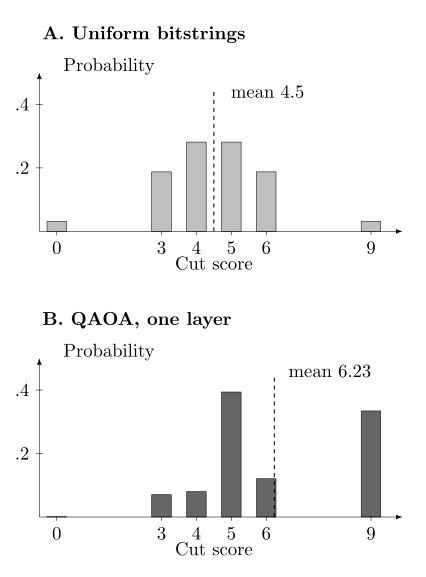
The same six possible cut scores have different probabilities before and after the cost–mixer layer. Dashed vertical lines mark the mean score, which rises from to about . The probability of the optimum, score nine, rises from to about . A higher mean and a larger optimum probability are distinct properties of this calculated distribution.
Thus . Independent repetitions hit an optimum with probability after eleven draws and after twelve. The least reaching is therefore . Complementary bitstrings have equal probability, as required by global bit-flip symmetry. This six-qubit bipartite instance is classically trivial—the bipartition itself is an optimum—so it validates only the ideal implementation and summary calculations.
The following NumPy calculation prepares this state and prints its mean and score probabilities. The score array is obtained directly from the edge list; no analytic expectation formula is inserted into the propagation.
import numpy as npfrom functools import reduce
n = 6edges = [(u, v) for u in range(3) for v in range(3, 6)]cost = np.array([sum(((z >> u) ^ (z >> v)) & 1 for u, v in edges)                 for z in range(2**n)])gamma, beta = np.arctan(1 / np.sqrt(2)), np.pi / 8psi = np.exp(-1j * gamma * cost) / np.sqrt(2**n)x_rotation = np.array([[np.cos(beta), -1j*np.sin(beta)],                       [-1j*np.sin(beta), np.cos(beta)]])psi = reduce(np.kron, [x_rotation] * n) @ psiprobability = abs(psi)**2print("Mean:", cost @ probability)for score in np.unique(cost):    print(score, probability[cost == score].sum())
The array index uses vertex as bit , with the least significant bit. Every qubit has the same mixer, so the displayed tensor product is unaffected by the ordering of its identical factors. The full matrix is convenient for six qubits; its exponential memory cost makes it unsuitable for large graphs. The separate edge formula provides an analytic comparison for the calculated mean.
Common pitfalls
Section titled “Common pitfalls”Cost first, then mixer. Acting first with the transverse mixer on changes only a global phase. A circuit-order mistake can therefore remove the desired interference rather than merely shift the best angles.
Regular does not mean triangle-free. The degrees alone do not determine the depth-one edge expectation. Common neighbors contribute the last term in the general formula.
A promising mean is not a success probability. The probability of obtaining a useful bitstring depends on the score distribution. Best-of-many sampling also consumes many executions; counting only the circuit that produced the best candidate omits that cost.
Exercises
Section titled “Exercises”1. Map a QUBO to Pauli operators
Section titled “1. Map a QUBO to Pauli operators”Let for . Derive its diagonal Pauli representation, including the constant. If the input instead contains diagonal terms, state how they are reduced. Explain how omitting the constant affects state preparation and how it can affect a reported ratio.
Solution
Substituting and gives
where
Any diagonal contribution is first replaced by because , so it enters the corresponding linear coefficient rather than the two-variable substitution.
On a basis state, has eigenvalue , so substitution back into the last expression recovers exactly. The factor is a global phase and can be omitted from the circuit. The classical score must still restore . For example, dividing an expected value and optimum by their shifted values gives , which is generally not ; a ratio is not invariant under an objective offset.
2. Solve one edge at depth one
Section titled “2. Solve one edge at depth one”For , start from and use . Derive the expected cut and evaluate the complete output distribution at .
Solution
After the phase separator,
Conjugating by the two rotations, or multiplying the four amplitudes, gives
At the stated angles both sine factors equal one, so . Because the score is binary, expectation one already implies zero probability on the uncut strings. Direct amplitude evaluation gives
The result depends on applying first. If the rightmost order or a generator sign is changed, the same numerical angles cannot be assumed to remain optimal.
3. Optimize the regular-graph formula
Section titled “3. Optimize the regular-graph formula”Starting from the triangle-free -regular depth-one expression, find a representative optimum for in the positive branch and derive the expected cut fraction. Explain its relation to the expected approximation ratio when the optimum is unknown.
Solution
For positive , maximize by choosing . Differentiating the remaining factor gives
The interior maximum has and . Hence
This is the expected fraction of all edges cut by the ideal depth-one distribution under the stated simple, unweighted, triangle-free, regular hypotheses. An approximation ratio instead divides by the instance optimum, which need not equal . Since , the cut fraction is a lower bound on the ratio, and the two coincide for bipartite graphs. The case is obtained separately from the isolated-edge formula as .
4. Reproduce the K₃,₃ distribution
Section titled “4. Reproduce the K₃,₃ distribution”Enumerate the 64 basis strings of , propagate the declared depth-one state at and , and recover the expectation, optimum probability, six probability buckets, and repetitions required for a optimum hit.
Solution
Apply to each uniform initial amplitude and then apply pairwise on each of the six bit axes. Summing gives
Grouping by cut value reproduces the six probability rows in the table above.
Their degeneracies are and the exact probabilities sum to one. Brute force finds , so . Therefore
Eleven and twelve draws give hit probabilities and , respectively. The graph is an exactly soluble illustration: its bipartition already gives a classical optimum.
5. Prove that an XY mixer preserves Hamming weight
Section titled “5. Prove that an XY mixer preserves Hamming weight”Prove . Then explain why this conservation law does not by itself show that the mixer reaches every weight- bitstring.
Solution
For one mixer edge,
Each summand moves one excitation from one endpoint to the other, so it commutes with the pair number , where . It also commutes with every off that edge. Summing over mixer edges gives
Thus every preserves each fixed-weight subspace. But a conserved subspace can contain disconnected dynamical sectors. If the mixer graph has two components, the excitation count in each component is conserved separately, so strings with different component-wise counts cannot mix. If the mixer graph is connected, edge exchanges generate paths between any two weight- strings; this removes that particular disconnected-component obstruction. It does not imply arbitrary state preparation or efficient optimization. The exchange-symmetric three-state example in the text shows the additional restriction imposed by a common symmetry of the initial state and both generators.
6. Compare estimation shots with hit-probability repetitions
Section titled “6. Compare estimation shots with hit-probability repetitions”For normalized scores, compute the Hoeffding allocation for and . Contrast it with the repetitions needed to sample a optimum with probability at least .
Solution
Hoeffding’s bound requires
shots to guarantee the fixed-state normalized mean is within with failure probability at most . For the calculated optimum probability , independent best-of- solution sampling needs
so . The smaller number does not estimate the mean accurately; it only controls whether at least one threshold event occurs when is already known. In an optimization run, estimating , selecting angles and assessing the selected state consume additional fresh samples. If , retries cannot help; if , one draw suffices.
7. Count logical and compiled MaxCut resources
Section titled “7. Count logical and compiled MaxCut resources”Count interactions, rotations, and ideal all-to-all depths for level- QAOA on . Compare native gates with a CNOT––CNOT decomposition, and identify the hypothesis behind the general bound.
Solution
has , , maximum degree three, and an edge coloring with three matchings. Per level it therefore uses nine logical edge interactions and six mixer rotations. With native gates, the cost has two-qubit depth three; adding the parallel mixer gives logical alternating depth four, hence counts , , and depth over levels.
The CNOT––CNOT form uses CNOTs. The two CNOT rounds for each matching are sequential, giving ideal entangling depth , plus the single-qubit and mixer scheduling. A native implementation instead uses two-qubit gates at two-qubit depth .
For a general simple graph, Vizing’s theorem supplies . attains the sharper bipartite value . Neither statement includes routing, crosstalk restrictions, orientation, calibration, shots, or optimizer evaluations.
8. Bound success from a mean score
Section titled “8. Bound success from a mean score”Suppose an integer score satisfies , and success means , where . Derive upper and lower bounds on from its mean . Then construct two distributions with mean five and maximum possible score nine but different optimum probabilities.
Solution
Successful scores are at least , while unsuccessful scores are at most . Therefore
Rearrangement gives
The integer-score assumption is essential to the bound. For a real-valued score, use the appropriate upper bound on scores that fail the threshold.
One distribution assigns probability one to score five. Another assigns probability to score nine and to score zero. Both have mean five, but their optimum probabilities are zero and . These are probability examples rather than an assertion that both are attainable in a particular QAOA family. They show why a mean alone cannot determine the number of retries needed to obtain an optimum.
References
Section titled “References”- V. Akshay, H. Philathong, M. E. S. Morales, and J. D. Biamonte, “Reachability Deficits in Quantum Approximate Optimization,” Physical Review Letters 124, 090504 (2020), doi:10.1103/PhysRevLett.124.090504.
- S. Bravyi, A. Kliesch, R. Koenig, and E. Tang, “Obstacles to Variational Quantum Optimization from Symmetry Protection,” Physical Review Letters 125, 260505 (2020), doi:10.1103/PhysRevLett.125.260505.
- E. Farhi, D. Gamarnik, and S. Gutmann, “The Quantum Approximate Optimization Algorithm Needs to See the Whole Graph: Worst Case Examples,” arXiv:2005.08747 [quant-ph] (2020), doi:10.48550/arXiv.2005.08747.
- E. Farhi, J. Goldstone, and S. Gutmann, “A Quantum Approximate Optimization Algorithm,” arXiv:1411.4028 [quant-ph] (2014), doi:10.48550/arXiv.1411.4028.
- E. Farhi and A. W. Harrow, “Quantum Supremacy through the Quantum Approximate Optimization Algorithm,” arXiv:1602.07674 [quant-ph] (2016), doi:10.48550/arXiv.1602.07674.
- M. X. Goemans and D. P. Williamson, “Improved Approximation Algorithms for Maximum Cut and Satisfiability Problems Using Semidefinite Programming,” Journal of the ACM 42, 1115–1145 (1995), doi:10.1145/227683.227684.
- S. Hadfield, Z. Wang, B. O’Gorman, E. G. Rieffel, D. Venturelli, and R. Biswas, “From the Quantum Approximate Optimization Algorithm to a Quantum Alternating Operator Ansatz,” Algorithms 12, 34 (2019), doi:10.3390/a12020034.
- M. P. Harrigan et al., “Quantum Approximate Optimization of Non-Planar Graph Problems on a Planar Superconducting Processor,” Nature Physics 17, 332–336 (2021), doi:10.1038/s41567-020-01105-y.
- M. B. Hastings, “Classical and Quantum Bounded Depth Approximation Algorithms,” Quantum Information & Computation 19, 1116–1140 (2019), doi:10.26421/QIC19.13-14-3.
- Z. Wang, S. Hadfield, Z. Jiang, and E. G. Rieffel, “Quantum Approximate Optimization Algorithm for MaxCut: A Fermionic View,” Physical Review A 97, 022304 (2018), doi:10.1103/PhysRevA.97.022304; corrected expression in arXiv:1706.02998v2.
- D. Wecker, M. B. Hastings, and M. Troyer, “Progress towards Practical Quantum Variational Algorithms,” Physical Review A 92, 042303 (2015), doi:10.1103/PhysRevA.92.042303.
- L. Zhou, S.-T. Wang, S. Choi, H. Pichler, and M. D. Lukin, “Quantum Approximate Optimization Algorithm: Performance, Mechanism, and Implementation on Near-Term Devices,” Physical Review X 10, 021067 (2020), doi:10.1103/PhysRevX.10.021067.