

Metrics for Quantum Hardware
A quantum hardware metric estimates a specified property of a component, operation, logical system, or workload. Its formula, measurement protocol, operating conditions, and uncertainty determine what can be inferred from it. For example, state fidelity, average gate fidelity, assignment accuracy, and circuit success probability answer different questions even when all are reported as percentages.
Helpful background. Hardware overview distinguishes physical encodings, channels, and measurements; noise in quantum information introduces error mechanisms, and quantum measurement as estimation explains likelihoods and uncertainty.
Estimands and estimates
Section titled “Estimands and estimates”An estimand is the quantity of interest, such as a specified decay time or an average gate overlap. An estimator is a function of the acquired data . The distinction matters: a fitted exponential time can change when the fit window changes, even if the physical noise has not. Its uncertainty is conditional on the model used in the fit.
Name the target operation, input ensemble, device subset, simultaneous activity, and time window. State the sampling unit: repeated shots on one random circuit and independently drawn circuits supply different information. Component measurements become predictions for a full task only through a composition model that includes scheduling, leakage, correlations, and classical control. Eisert and colleagues (2020) review these different characterization questions.
Component Coherence Metrics
Section titled “Component Coherence Metrics”Energy relaxation time
Section titled “Energy relaxation time”For an effective two-level system prepared in , an idealized relaxation experiment may fit
is the fitted population-relaxation timescale for that transition and operating condition. The offset can represent thermal population or readout bias; absorbs imperfect preparation and contrast. A single-exponential fit is a model, not a definition guaranteed by nature. Multiple decay channels, drift, quasiparticle events, atom loss, shelving states, or non-Markovian baths can produce nonexponential curves.
Report at least:
- prepared state and transition;
- idle point, control configuration, and environmental conditions;
- fit function, time range, residuals, and confidence interval;
- repetition schedule and observed drift;
- whether loss is distinguished from relaxation within the computational subspace.
Dephasing times
Section titled “Dephasing times”A Ramsey experiment often fits a signal such as
is an inhomogeneous dephasing time for the Ramsey protocol. The exponent parametrizes the fitted envelope; it does not uniquely identify a noise spectrum. The detuning is measured relative to the chosen oscillator reference. Hahn echo or longer dynamical-decoupling sequences define different coherence times because they filter low-frequency noise differently. They should not all be labeled simply without the pulse sequence.
For a stationary two-level model with independent Markovian population relaxation and pure dephasing in the energy basis,
Within that model, . This relation is a diagnostic model check, not a universal fitting constraint. Dephasing versus Dissipation develops the physical distinction.
Dephasing and amplitude damping connects these times and the equilibrium population to a finite channel, including its physicality and composition assumptions.
Thermal population and state occupancy
Section titled “Thermal population and state occupancy”An effective qubit may have equilibrium excited-state population
only when a two-level Gibbs model at temperature is justified. In practice, residual population may arise from nonequilibrium radiation, imperfect reset, leakage, collisions, or detector bias. “Effective temperature” is then a parametrization of one population ratio, not evidence that every device degree of freedom is thermalized at that temperature.
Operation-to-coherence ratio
Section titled “Operation-to-coherence ratio”For operation duration ,
is a useful timescale ratio. It is not a gate count or executable circuit depth. It omits control infidelity, relaxation during other operations, idle periods, routing, leakage, crosstalk, measurement, reset, and error accumulation outside the fitted coherence model.
Preparation, Readout, and Reset
Section titled “Preparation, Readout, and Reset”Assignment probabilities
Section titled “Assignment probabilities”For binary outcomes, write the assignment matrix
A commonly reported mean assignment fidelity is
The two conditional errors should also be reported because the average hides asymmetry. The metric usually includes errors in the reference-state preparations, so it is often a state-preparation-and-measurement quantity rather than a detector-only property.
SPAM errors explains preparation–detector identifiability. A basis-state assignment matrix predicts arbitrary input probabilities only when the effects are diagonal in that basis, or the input has already been dephased there. Measurement error mitigation then treats inference under the calibrated response model, including its uncertainty and noise amplification.
When loss or leakage is possible, a forced binary classifier can turn a third physical outcome into a misleading bit assignment. Report the confusion matrix over all resolved outcomes, the fraction of rejected or heralded events, and whether rejection is included in the success probability.
Readout fidelity is not one concept
Section titled “Readout fidelity is not one concept”Distinct properties include:
- assignment accuracy: agreement between prepared labels and reported labels;
- quantum non-demolition behavior: whether the postmeasurement state remains in the measured eigenspace;
- measurement efficiency: a protocol-specific measure, such as detected photons per incident photon or a defined information-rate/backaction ratio in continuous monitoring; these conventions are not interchangeable;
- latency: time from the start of readout to a usable classical decision;
- crosstalk: dependence of one result on simultaneous readout of other carriers;
- leakage discrimination: ability to distinguish computational and noncomputational states;
- destructiveness: whether the carrier survives and can be reused.
Repeated agreement of two outcomes is not, by itself, a complete quantum non-demolition metric. Both measurements could be biased, and the first measurement could prepare the state that the second detects.
Initialization and reset
Section titled “Initialization and reset”Initialization fidelity should name the target state and whether it is unconditional, heralded, or postselected. Reset needs both a residual-error probability and a duration. A fast active reset with error can be more useful than waiting several times, but it may add leakage or correlated disturbance.
For error correction, reset throughput and latency can matter as much as isolated reset fidelity because fresh ancillas must be supplied every syndrome round.
Gate and Channel Metrics
Section titled “Gate and Channel Metrics”Average gate fidelity
Section titled “Average gate fidelity”Let be a completely positive, trace-preserving map on a -dimensional computational space and the target. The average gate fidelity is
The average gate infidelity is
The integral is over pure input states with Haar measure. Thus is an average over one use of the channel. It does not describe the worst input, temporal correlation, simultaneous context, or composition over a long circuit.
For , define the entanglement fidelity
Nielsen (2002) relates this normalized-Choi overlap to the average:
For a completely positive trace-nonincreasing computational branch , the corresponding unnormalized overlaps instead obey
To see the difference, write . The Haar second moment gives
The two numerator terms are and . Renormalizing each surviving output changes the quantity and generally destroys linearity; it cannot be inserted into the trace-preserving identity above.
“Process fidelity” is used inconsistently across communities. Some authors mean , some mean an overlap of process matrices, and some report a quantity normalized to equal . A paper should give the formula, not only the label.
Worst-case channel distance
Section titled “Worst-case channel distance”A composable worst-case error measure is the diamond distance
The ancillary extension in the diamond norm permits the input to be entangled with another system. This makes the distance suitable for bounding distinguishability. Errors of a fixed sequence of compatible channels add by a telescoping bound and contractivity. A history-dependent device needs bounds on the relevant conditional processes or a multi-time description; a set of isolated-gate averages does not supply them. Diamond distance is also much harder to estimate experimentally than average fidelity.
For two channels on the same -dimensional space, with the target unitary, general bounds relate infidelity and diamond distance (Kueng et al., 2016):
The wide gap is physically consequential. A small coherent over-rotation can have quadratic in its angle while is linear. Therefore an average infidelity should not be inserted directly into a worst-case fault-tolerance theorem without a justified noise model or randomization argument. Trace Distance and Fidelity give the reference definitions.
For a qubit rotation and a stochastic channel , choose . They have the same , but channel distances and respectively. Exercise 4 derives this distinction.
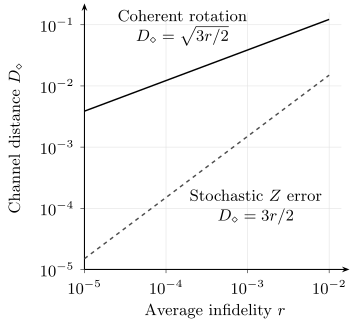
Both axes are logarithmic. The exact qubit formulas show that equal average infidelity can conceal very different worst-case distinguishability. These curves describe the two specified channels, not all coherent or stochastic noise models.
Infidelity is not always an error probability
Section titled “Infidelity is not always an error probability”For a stochastic Pauli channel, infidelity can be proportional to a fault probability. For coherent, nonunital, leakage, or gate-dependent noise, that interpretation can fail. Calling “the probability the gate failed” silently assumes a stochastic model that the experiment may not establish.
Also declare whether the channel is:
- conditioned on no loss or averaged over loss;
- projected back into the computational subspace;
- corrected for preparation and measurement;
- measured in isolation or during simultaneous operation;
- averaged over a gate set or associated with one target gate.
Characterization and Benchmarking Protocols
Section titled “Characterization and Benchmarking Protocols”No protocol returns “the true fidelity” without assumptions. Each trades information, scalability, and robustness to state-preparation-and-measurement error.
Process tomography
Section titled “Process tomography”Process Tomography prepares an informationally complete set of inputs and measures an informationally complete set of outputs, or uses an ancilla-assisted equivalent. It can reconstruct a detailed channel model, but its experimental and statistical cost grows rapidly with system size. Ordinary process tomography treats state preparations and measurements as trusted; their errors can be misattributed to the gate.
Tomography is valuable for diagnosing small systems, inspecting coherent structure, and testing models. It is not automatically a scalable system benchmark.
Gate-set tomography
Section titled “Gate-set tomography”Gate-set tomography jointly estimates preparations, measurements, and a set of gates from self-consistent circuits; long sequences amplify small gate errors (Nielsen et al., 2021). It can reveal coherent and non-Markovian model violations more richly than a single decay parameter. The reconstructed representation has gauge freedom: observable probabilities are unchanged by certain simultaneous transformations of states, measurements, and gates. Gauge-dependent quantities require careful interpretation.
Gate-set tomography is information rich but experimentally and computationally demanding. Its result describes the tested gate-set model and time window, not every circuit context.
Randomized benchmarking
Section titled “Randomized benchmarking”Randomized Benchmarking develops the sequence construction, sampling design, fit diagnostics, and variants. Here we compare the decay parameter with other hardware metrics.
In reference randomized benchmarking, random gate sequences of length compose ideally to an inversion. A common fit is
and absorb state-preparation-and-measurement contrast under the model. For a -dimensional depolarizing channel with decay parameter ,
This conversion is exact for the declared depolarizing model. Under gate-dependent, context-dependent, or non-Markovian noise, the fitted RB decay still can be stable and useful, but its relationship to an arithmetic mean of individual gate infidelities is subtler. Report the sampled gate group, compilation into native pulses, sequence lengths, number of random sequences, shots, fit model, residuals, and uncertainty.
RB is comparatively insensitive to fixed state-preparation-and-measurement offsets in the decay rate. It is not immune to drift, leakage, sequence-dependent sampling, or model failure, and it does not identify the physical error mechanism.
Interleaved randomized benchmarking
Section titled “Interleaved randomized benchmarking”Interleaved RB alternates a target gate with random reference gates. Under standard assumptions, an estimate is
where and are fitted decay parameters. Gate dependence and interaction between the interleaved gate’s error and the reference errors require bounds or additional analysis. The ratio should not be presented as model free.
Cycle and simultaneous benchmarking
Section titled “Cycle and simultaneous benchmarking”Cycle Benchmarking explains scheduled layers, Pauli-orbit decays, dressed-cycle process fidelity, and what the experiment can identify.
A cycle is a layer of operations intended to execute in parallel. Cycle benchmarking estimates an error property of the complete implemented cycle, including some simultaneous effects that isolated gate tests miss. Direct randomized benchmarking and related scalable protocols probe larger regions or native gate sets without reconstructing a full process.
These protocols are especially important because a processor executes schedules, not isolated data-sheet gates. A reported cycle metric must state which operations were simultaneous, which qubits were idle, how randomization was implemented, and whether spectator effects were included.
Leakage, Seepage, Loss, and Erasure
Section titled “Leakage, Seepage, Loss, and Erasure”Leakage and crosstalk derives full-space dynamics, survival branches, imperfect flags, and coherent return. The scalar metrics below summarize specific averages of that dynamics (Wood and Gambetta, 2018).
Let and project onto computational and leakage subspaces of dimensions and . One average leakage rate for channel is
An average seepage rate back into the computational subspace is
These formulas assume finite positive dimensions and complementary subspaces. An infinite leakage space has no maximally mixed state ; instead specify a finite cutoff or a prepared leakage ensemble.
If each cycle really induces a closed, time-homogeneous two-population Markov model, the leakage population satisfies
For , its unique stationary fraction is
Writing this fraction as gives . Convergence from every initial population requires . If both rates vanish, every population is stationary. If , the populations alternate unless initialized at . These scalar averages alone do not prove closure: state dependence, coherent return, multiple leakage levels, or intervention can invalidate the two-population model.
Loss means the physical carrier or excitation leaves the accepted system. An erasure is a failure whose location is reliably known to the decoder. Loss becomes an erasure only when it is detected with characterized false-positive and false-negative rates. Postselecting lost trials can improve conditional fidelity while reducing unconditional success; both must be reported.
Crosstalk, Addressability, and Drift
Section titled “Crosstalk, Addressability, and Drift”Crosstalk is context dependence: the implemented operation or observation on one subsystem changes when controls, measurements, or states elsewhere change. It can arise from stray fields, shared modes, spectral collisions, classical electronics, detector coupling, heating, or calibration dependencies.
A simple diagnostic compares isolated and simultaneous errors:
This difference is useful but not a complete crosstalk model. Crosstalk may create correlated faults even when marginal error rates change little. A serious test varies contexts, checks conditional dependencies, and identifies whether effects are local, pairwise, many-body, static, or time dependent.
Drift means the effective process changes over time. If is a fitted parameter, reporting only
can hide excursions that invalidate a computation. Include time traces, calibration events, acquisition ordering, and stability intervals. Randomizing the order of experimental settings can reduce confounding between condition and time.
Connectivity, Parallelism, and Scale
Section titled “Connectivity, Parallelism, and Scale”Connectivity
Section titled “Connectivity”Represent directly available two-body interactions by a graph . Useful graph properties include degree, diameter, geometry, edge quality, directionality, and whether edges can be reconfigured. Report the gate or interaction that defines an edge and the operating conditions under which multiple edges are usable simultaneously.
A complete system also needs a conflict graph or scheduling rule. Two edges may each work well in isolation but not at the same time. Connectivity without parallelism can overstate executable depth.
Counts and yield
Section titled “Counts and yield”Distinguish:
- fabricated or available sites;
- occupied carriers;
- detected carriers;
- individually addressable carriers;
- calibrated qubits or modes;
- qubits participating simultaneously in the benchmark;
- data and ancilla qubits in an encoded experiment;
- logical qubits with declared code distance;
- logical qubits supporting the reported operation set.
Calibration yield can be written
The criteria and test duration must be stated. Selecting a high-performing connected subset is legitimate for a benchmark, but the selection rule and fraction of the full device should be visible.
Latency and throughput
Section titled “Latency and throughput”For a serial cycle without overlapping stages,
For overlapping or pipelined operation, use the actual dependency and resource schedule instead. Quantum error correction needs decoder throughput sufficient to avoid an accumulating backlog and decision latency compatible with adaptive operations; it need not require each decode to finish before the next syndrome round.
A shot rate
is meaningful only with workload, batch size, reset, compilation, data transfer, and queue boundaries defined. Peak pulse repetition rate is not end-to-end throughput.
Availability may be reported as
The specification should include calibration validity and disabled components. A record obtained during one selected minute and a sustained daily service metric answer different questions.
System-Level Benchmarks
Section titled “System-Level Benchmarks”A system benchmark combines width, connectivity, compilation, gates, and readout through a circuit family. It is more representative than one component number but remains task specific.
Cross-entropy benchmarking
Section titled “Cross-entropy benchmarking”Cross-Entropy Benchmarking scores random-circuit samples using ideal probabilities for the same compiled circuits. It probes system-level correlation across gates, concurrency, readout, compilation, and depth, but its interpretation depends on the circuit ensemble, normalization, scrambling regime, noise model, classical reference, and sampling hierarchy.
A linear XEB score is not automatically a state fidelity, distributional distance, or proof of computational advantage. Comparisons require the same circuit family, score convention, postselection policy, probability-computation accuracy, and dated classical baseline.
Quantum volume
Section titled “Quantum volume”Quantum Volume and Application Benchmarks develops the full protocol, statistical unit, volumetric generalization, and application-suite comparison rules. The quantum-volume protocol uses random square model circuits whose width equals their depth. For each width , the compiled device samples outputs, and a heavy-output test determines whether performance exceeds a specified statistical threshold. The reported quantum volume is conventionally
where is the largest passing square-circuit size under the protocol.
Quantum volume tests a particular random-circuit family and includes effects of compilation and connectivity. It is not a physical volume, logical-qubit count, general application score, or asymptotic complexity measure. Comparisons require the same protocol version, confidence rule, compiler freedoms, and treatment of selected qubit subsets.
Benchmark families, not universal scores
Section titled “Benchmark families, not universal scores”Other useful system tests include mirror circuits, random circuit sampling, algorithmic benchmark suites, Hamiltonian-simulation tasks, and application-specific validation. No finite suite proves performance on every circuit. A benchmark should expose:
- circuit distribution and instance-selection rule;
- width, depth, native compilation, and optimization budget;
- shots and confidence criteria;
- use of mitigation, postselection, or heralding;
- classical verification cost;
- total wall-clock and classical resources;
- whether the instances were fixed before tuning.
A single-number score is useful for tracking a fixed protocol. It should not erase the underlying performance surface.
Logical Metrics
Section titled “Logical Metrics”Logical failure probability
Section titled “Logical failure probability”A logical failure probability is an estimand for a specified experiment. For independent, identically distributed completed trials with an observable binary success criterion, its direct estimator is
A per-round probability is often inferred from a decay model, not from counting detected errors in every round. In an ideal logical bit-flip model, independent flips of probability per round give terminal disagreement after rounds
Two flips cancel in this readout, so is only a small- approximation to . Coherent or correlated logical noise, preparation/readout offsets, and postselection need different models. Logical benchmarking develops these encoded-channel and decay interpretations.
State the code, distance, syndrome schedule, decoder, boundary conditions, leakage treatment, and discarded trials. An error per complete memory experiment, per logical gate, and per inferred syndrome round cannot be compared without their respective durations and inference model.
Suppression with code size
Section titled “Suppression with code size”For a family of odd-distance codes, a local suppression factor can be defined as
means the larger tested code performed better under the declared conditions. Sustained below-threshold evidence requires suppression over increasing distances with matched noise, circuits, and decoding. One favorable pair does not prove an asymptotic threshold.
Break-even
Section titled “Break-even”An encoded memory reaches break-even only relative to a declared physical baseline. Possible baselines include the best constituent qubit, the average constituent, an unencoded qubit operated for the same wall-clock time, or the best available physical carrier. The baseline should experience comparable preparation, idle time, and measurement opportunities.
Fault tolerance is stronger than break-even. A circuit is fault tolerant when a bounded number of faults cannot spread into an uncorrectable error according to the code and gadget design. Low logical error after postselection is not automatically fault-tolerant correction.
Overhead and logical rate
Section titled “Overhead and logical rate”Report physical qubits or modes, ancillas, spacetime volume, syndrome rounds, decoder resources, distilled resource states, discarded runs, and wall-clock time per logical operation. Logical reliability without rate can hide an architecture that cannot finish the task before drift, memory decay, or practical time limits dominate.
Correctability and the surface code explain the code and syndrome-circuit assumptions behind logical comparisons.
Workload Metrics
Section titled “Workload Metrics”The final metric should match the intended task: energy error, sampling distance, decision success, key rate, sensing uncertainty, entanglement-generation rate, or another scientifically meaningful output.
For independent repeated trials with success probability and per-trial time , the number required for probability at least of one or more successes is
The corresponding idealized time to solution is
Here and ; needs one trial, while can never succeed. The formula assumes independent stationary trials and a fixed binary success criterion. It treats as known. If is estimated, uncertainty in that estimate must be propagated; using a statistically justified lower bound is one conservative option. Verification, queueing, compilation, calibration, and classical postprocessing must be added when they lie inside the operational boundary.
A complete workload resource record can be written schematically as
where is scheduled depth, is output error, and is the required success probability in the repeated-trial model above. A confidence level for an estimated parameter is a separate quantity. Not every study needs every component, but the resource boundary should be explicit.
Uncertainty, Sampling, and Selection
Section titled “Uncertainty, Sampling, and Selection”For observed failures in independent Bernoulli opportunities,
The normal approximation fails near or and for small counts. Wilson, likelihood-ratio, Bayesian, or exact intervals are better choices depending on the sampling model and whether coverage or posterior probability is intended. Observing zero failures does not prove ; the exact one-sided binomial upper limit is . It requires a fixed sample size and independent trials with a common failure probability. Optional stopping needs a sequentially valid analysis.
Quantum-hardware data often violate independent, identically distributed assumptions:
- drift changes the rate during acquisition;
- calibration is chosen using some of the same data;
- errors are temporally or spatially correlated;
- device subsets are selected after inspection;
- failed preparations or lost carriers are discarded;
- random sequence instances have heterogeneous difficulty.
Use blocked or time-resolved analysis, hierarchical models, held-out validation, and preregistered selection rules where appropriate. At minimum, publish acquisition order, timestamps, calibration interventions, number of discarded runs, and uncertainty method.
Worked comparison of measured quantities
Section titled “Worked comparison of measured quantities”Suppose a report gives the following values for a qubit processor:
| Observation | Reported value |
|---|---|
| Ramsey coherence | |
| physical gate duration | |
| qubit RB decay | |
| readout conditionals | , |
| leakage and seepage | , |
| isolated and simultaneous infidelity | , |
| logical failures per round | , |
The timescale ratio is
For qubit RB under the depolarizing conversion,
The mean assignment fidelity is
but the asymmetric conditionals remain visible. The two-population stationary leakage estimate is
Simultaneous operation increases the reported infidelity by
or relative to the isolated value. Finally,
The point estimates favor distance five over distance three in the tested logical-memory protocol; error bars are needed to establish statistical significance. They do not establish that a depth-2000 circuit succeeds, that all gate errors are stochastic, that the readout is quantum non-demolition, that leakage is state independent, or that suppression continues at larger distance. Each conclusion stays at the layer actually measured.
Exercises
Section titled “Exercises”1. A relaxation time depends on the offset
Section titled “1. A relaxation time depends on the offset”At an initially excited qubit has population 0.25. Infer first for , then for thermal equilibrium population 0.10 and .
Solution
The zero-offset estimate is . With the known thermal offset, , giving . One population at one time does not determine both offset and decay time. A real fit needs multiple delays, calibrated populations, and model checks.
2. Fidelity when survival is incomplete
Section titled “2. Fidelity when survival is incomplete”A qubit has computational branch , with . Find its average target overlap and entanglement overlap relative to the identity. Does the trace-preserving conversion apply?
Solution
Every pure-state overlap is , and applying the branch to half of gives . Also , so . Incorrectly setting would give . For , conditioning on survival gives fidelity 1, which conceals the loss unless the survival probability is also supplied.
3. An interleaved estimate can be negative
Section titled “3. An interleaved estimate can be negative”Suppose every implemented reference Clifford is followed by , while an interleaved identity is followed by . Ideal inversion/SPAM effects are confined to the prefactor. Why can the usual interleaved ratio suggest a negative infidelity?
Solution
Clifford twirling of the reference error gives for a small nonzero angle. The two errors cancel in each interleaved pair, so . The ratio estimate is negative, even though the isolated target error has positive infidelity . The negative result signals a failed conversion assumption, not a gate better than perfect. Correlated coherent cancellation must be covered by a justified bound or a different protocol.
4. Equal infidelity, unequal channel distance
Section titled “4. Equal infidelity, unequal channel distance”Compare with the stochastic channel , where and .
Solution
For the unitary, . For the Pauli channel, orthogonality of the identity and Choi states also gives . Hence both have . Their half diamond distances from identity are
An equatorial pure state attains these distinguishabilities; the unitary spectral formula and the Pauli-mixture triangle bound show that ancillas cannot increase them here. For , the common infidelity is approximately , but the distances are about 0.01 and . The figure plots the exact formulas.
5. Stationary leakage and convergence
Section titled “5. Stationary leakage and convergence”Take and per cycle in the closed population model. Find the stationary leakage and its relaxation factor. Contrast this with .
Solution
The stationary fraction is , and converges to it. With both rates 1, instead. There is a stationary distribution at , but any other initial population alternates forever. Stationarity does not itself imply convergence.
6. No observed failures
Section titled “6. No observed failures”A fixed experiment records zero failures in 10,000 independent trials with common failure probability . Find an exact one-sided 95% upper confidence bound.
Solution
The probability of zero failures is . Solving it equal to 0.05 gives
This is close to . It is a confidence-bound construction, not a 95% posterior probability for a fixed unknown . Correlation, drift, or outcome-dependent stopping requires a model-appropriate analysis; there is no universal effective-sample-size replacement.
7. Infer a per-round logical probability
Section titled “7. Infer a per-round logical probability”In the independent logical bit-flip model, and a trial lasts 100 rounds. Find terminal disagreement and compare division by 100 with the correct inverse model.
Solution
. Dividing by 100 gives 0.004337, not 0.01. For the small-error branch , the correct inverse is
An endpoint measurement sees the parity of flips, not their count. Near saturation at , inversion also becomes statistically ill-conditioned.
8. Logical suppression and extrapolation
Section titled “8. Logical suppression and extrapolation”Matched experiments estimate and . Find the estimated suppression factor and a distance-nine projection if that factor persists.
Solution
The ratio of point estimates is . Maintaining that factor would give . The latter is an extrapolation, not a measurement. Uncertainty in both probabilities propagates into their ratio, and larger devices may have different correlations, leakage, or decoder bottlenecks.
References
Section titled “References”- A. W. Cross, L. S. Bishop, S. Sheldon, P. D. Nation, and J. M. Gambetta, “Validating quantum computers using randomized model circuits,” Physical Review A 100, 032328 (2019), doi:10.1103/PhysRevA.100.032328.
- J. Eisert et al., “Quantum certification and benchmarking,” Nature Reviews Physics 2, 382–390 (2020), doi:10.1038/s42254-020-0186-4.
- A. Erhard et al., “Characterizing large-scale quantum computers via cycle benchmarking,” Nature Communications 10, 5347 (2019), doi:10.1038/s41467-019-13068-7.
- A. Gilchrist, N. K. Langford, and M. A. Nielsen, “Distance measures to compare real and ideal quantum processes,” Physical Review A 71, 062310 (2005), doi:10.1103/PhysRevA.71.062310.
- P. Krantz et al., “A quantum engineer’s guide to superconducting qubits,” Applied Physics Reviews 6, 021318 (2019), doi:10.1063/1.5089550.
- R. Kueng, D. M. Long, A. C. Doherty, and S. T. Flammia, “Comparing experiments to the fault-tolerance threshold,” Physical Review Letters 117, 170502 (2016), doi:10.1103/PhysRevLett.117.170502.
- E. Magesan, J. M. Gambetta, and J. Emerson, “Scalable and robust randomized benchmarking of quantum processes,” Physical Review Letters 106, 180504 (2011), doi:10.1103/PhysRevLett.106.180504.
- E. Magesan et al., “Efficient measurement of quantum gate error by interleaved randomized benchmarking,” Physical Review Letters 109, 080505 (2012), doi:10.1103/PhysRevLett.109.080505.
- E. Nielsen, J. K. Gamble, K. Rudinger, T. Scholten, K. Young, and R. Blume-Kohout, “Gate set tomography,” Quantum 5, 557 (2021), doi:10.22331/q-2021-10-05-557.
- M. A. Nielsen, “A simple formula for the average gate fidelity of a quantum dynamical operation,” Physics Letters A 303, 249–252 (2002), doi:10.1016/S0375-9601(02)01272-0.
- T. Proctor, K. Rudinger, K. Young, M. Sarovar, and R. Blume-Kohout, “What randomized benchmarking actually measures,” Physical Review Letters 119, 130502 (2017), doi:10.1103/PhysRevLett.119.130502.
- T. Proctor et al., “Detecting and tracking drift in quantum information processors,” Nature Communications 11, 5396 (2020), doi:10.1038/s41467-020-19074-4.
- M. Sarovar, T. Proctor, K. Rudinger, K. Young, E. Nielsen, and R. Blume-Kohout, “Detecting crosstalk errors in quantum information processors,” Quantum 4, 321 (2020), doi:10.22331/q-2020-09-11-321.
- J. J. Wallman and S. T. Flammia, “Randomized benchmarking with confidence,” New Journal of Physics 16, 103032 (2014), doi:10.1088/1367-2630/16/10/103032.
- C. J. Wood and J. M. Gambetta, “Quantification and characterization of leakage errors,” Physical Review A 97, 032306 (2018), doi:10.1103/PhysRevA.97.032306.