

Network Verification
Quantum-network verification asks what delivered quantum systems can be used for, and how reliably finite measurements support that conclusion. A Bell pair can be entangled yet fall below a required fidelity; a high-fidelity pair can arrive too late; and a network correlation can reject one model without identifying the physical wiring. The statistical statement must match the object, population and assumptions actually tested.
We begin with endpoint Bell-pair tests, then distinguish sampling, dishonest devices, independent sources and channel verification. The same reasoning explains why testing measured pairs does not automatically certify retained pairs or future deliveries.
Required background. Network architectures explains delivered-pair services and timing. Entanglement certification supplies witnesses and Bell tests; state tomography and quantum channels supply density operators and noisy maps.
Bell-pair quality as a statistical question
Section titled “Bell-pair quality as a statistical question”Suppose two endpoints need pairs with fidelity above relative to a specified Bell state. A useful test separates a bad-source hypothesis from an alternative with a positive margin:
The probability of accepting under is the false-certification error. The probability of accepting a specified good alternative is the power. Neither is a posterior probability that the source is good. The margin matters: distinguishing states arbitrarily close to the threshold requires arbitrarily many samples at fixed error targets.
Also specify which pairs the statement concerns. A day’s mean fidelity, the fidelity on one route, and the fidelity of pairs delivered before a deadline are different quantities. Discarding slow or unfavorable events can change the state ensemble. An endpoint test therefore needs both its quantum measurement model and a rule defining eligible deliveries.
From three correlations to fidelity
Section titled “From three correlations to fidelity”For the target
the projector has the Pauli expansion
For any two-qubit state , not merely a Bell-diagonal state,
where . If simultaneous one-sided confidence bounds give
then a conservative fidelity bound is
Every separable two-qubit state has overlap at most with a maximally entangled state. Thus certifies entanglement under the calibrated qubit-and-measurement model. A service requirement is stricter: an entanglement certificate can pass while the service-quality certificate fails.
Suppose the intervals are
Then
This certifies entanglement but does not certify a minimum. The lower bound, rather than a rounded point estimate, determines the decision.
The target also depends on a frame convention. If a herald identifies and software records a Pauli-frame update to , the correlators must be interpreted using that exact record. Mixing uncorrected Bell labels can make individually good pairs look maximally mixed.
Random local tests and the verification gap
Section titled “Random local tests and the verification gap”An especially simple test chooses , or uniformly. Alice and Bob each measure the chosen Pauli observable. Accept equal outcomes in the bases and opposite outcomes in the basis. Here means , and similarly for the other two products. The pass operators are
Every test accepts with certainty. Each other Bell state passes exactly one of the three tests, so the average pass operator is
Its eigenvalues are . The gap between the target eigenvalue and the largest unwanted eigenvalue is therefore . This is a concrete instance of local state verification developed by Pallister, Linden and Montanaro (2018).
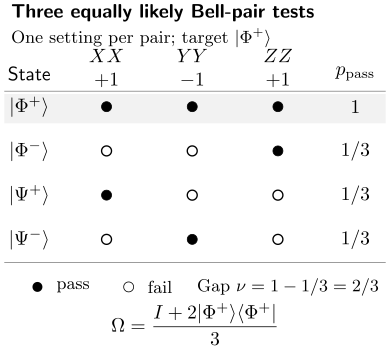
One randomly chosen setting is measured on each pair. Filled circles mark passing eigenstates; open circles mark failing eigenstates. The target passes with probability , while every state in the orthogonal Bell subspace passes with probability . The separation determines how quickly repeated tests reject infidelity. The diagram lists possible outcomes for different input states; it does not prescribe three successive measurements on one pair.
More generally, let accept a pure target with certainty, and let its largest eigenvalue on the orthogonal subspace be . For target fidelity at most ,
The reason is that the target part can pass with probability one, while the remaining weight has pass probability at most . If independent copies of the same bad state are tested, the all-pass probability is bounded by
Thus is sufficient for false acceptance at most . The same multiplication bound holds when each next conditional state, given the preceding record, satisfies the stated bad-state bound and the test choice is fresh. For a correlated batch, a bound on its average single-copy fidelity does not alone imply this product bound. Inferring the quality of an unmeasured output requires a further sampling argument.
An all-pass rule can have poor power when an acceptable source has a nonzero failure probability: requiring a very long flawless run can reject good sources. A threshold permitting some failures needs an explicit good-state noise model and finite-sample bounds for both errors. Correlated or adversarial batches require a theorem for that setting; blindly raising an IID binomial probability to the th power is not such a theorem.
Tested pairs, retained pairs and trusted devices
Section titled “Tested pairs, retained pairs and trusted devices”Local projective measurements used to estimate destroy the Bell pair’s entanglement. This is not a property of the observable alone: an ideal joint nondemolition parity measurement can preserve a Bell eigenstate. The measurement procedure determines what remains available. Standard endpoint tomography and the local tests above consume the tested pairs as entanglement resources.
For a batch of deliveries, choose a private random subset for testing and retain its complement . The source must not know which systems will be used before it commits their preparation. Under an IID model, test results constrain the common state. A finite-population sampling argument can instead relate random samples to a fixed population; Serfling (1974) gives classical bounds for sampling without replacement. A quantum adversarial batch, including entanglement between systems and conditioning on acceptance, needs an applicable quantum verification theorem. Exchangeability alone is not such a theorem.
Heralded selection is not intrinsically invalid. One may define the population as all pairs passing a specified herald and randomly sample within that population. Prespecified route or age strata can also be useful. Choosing favorable settings, outcomes or exclusions after inspecting the test data changes the experiment and can invalidate its error bound. Always distinguish optical attempts, heralded pairs and application-accepted pairs when stating probabilities.
The measurement assumptions determine which conclusion is possible:
| Approach | Trusted elements | What the test can establish |
|---|---|---|
| Calibrated endpoints | dimension, measurements, labels | fidelity or a witness value |
| Untrusted source | endpoint measurements and private choices | a protocol-specific source-quality bound |
| One trusted endpoint | that endpoint’s laboratory | steering or a suitable target-state bound |
| Device independent | input generation and causal isolation | a conclusion from Bell correlations |
| Network device independent | these conditions and a source model | incompatibility with that network-local model |
Device independence does not remove assumptions about random inputs, allowed communication or recorded outputs. Each local device receives its own setting; forbidden access to distant settings and advance correlations with the setting choices are what must be controlled. Loss cannot be removed by an arbitrary favorable coincidence selection. A Bell violation alone also does not supply the separate security proof required by device-independent QKD.
Multipartite resources and dishonest parties
Section titled “Multipartite resources and dishonest parties”For a graph , define commuting stabilizer generators and their positive-outcome projectors by
Their joint positive eigenspace is the graph state, so
The second relation is the ordinary union bound applied in their common eigenbasis: failing at least one check is no more likely than the sum of the individual failure probabilities. Taking an expectation gives
Use simultaneous lower confidence bounds for the generator expectations to obtain a finite-data fidelity bound. Raw sample means alone do not provide that guarantee; a negative lower bound is replaced by the trivial bound zero. Compatible generators can share a local measurement setting, and other verification operators may need fewer samples.
This argument trusts the measured observables. If participants can lie about outcomes or collude with the source, it no longer establishes the same claim. Unnikrishnan and Markham (2022) construct graph-state protocols with an untrusted source and possibly dishonest parties. Such results specify the honest verifier, private challenges, classical communication and selection of the retained state. A guarantee about the honest parties’ subsystem is different from asserting that every party received the ideal full state. See graph states for the underlying stabilizer construction.
Bilocality tests the source-independence model
Section titled “Bilocality tests the source-independence model”Ordinary Bell locality uses one shared hidden variable. In an entanglement-swapping chain, Branciard et al. (2012) instead consider two independent sources. Take endpoint settings and one joint measurement at the middle node. A bilocal model factors as
The product is the source-independence assumption. A general Bell-local model may replace it with a correlated , so the bilocal set is smaller and generally nonconvex.
The endpoint outputs take values . The middle node returns two bits from its one joint measurement. Let and define
Bilocal correlations satisfy
A statistically significant violation rejects this model under its input-choice, communication, loss and sampling assumptions. It does not demonstrate the physical independence of the sources; that independence is a premise of the null hypothesis. Shared classical randomness can violate the inequality when independence fails, as Exercise 4 shows. Nor does the statistic by itself determine a Bell-state fidelity or identify a faulty component.
What self-testing and topology tests identify
Section titled “What self-testing and topology tests identify”In the terminology reviewed by Šupić and Bowles (2020), self-testing infers that every compatible realization contains a target state and measurements, up to local isometries and irrelevant auxiliary systems. A robust statement has the schematic form
where is a specified distance and for a product of local isometries . The auxiliary state accounts for unused systems, and as . The exact robustness function is protocol-specific. A statement of ideal self-testing without the finite-noise bound needed by the experiment is incomplete.
The state guarantee must be read together with any stated equivalence for measurements, including possible complex-conjugation ambiguities. Network constraints can also test candidate causal structures. Given observed , one may ask whether any states and measurements arranged on a proposed source graph can reproduce the data. Inflation and related relaxations generate necessary constraints on that model. Violating one excludes the candidate structure within the assumptions; Ulibarrena et al. (2024) demonstrate this approach with quantum inflation.
This conclusion is usually an equivalence-class statement, not a photograph of cables. Two physical networks can produce the same observable statistics, and finite tests rarely identify one unique internal realization. The certificate must state which candidate models were excluded and which alternatives remain.
Channels, loss and heralding
Section titled “Channels, loss and heralding”A network often promises a channel rather than a fixed state. For a trace-preserving map on dimension , define the normalized Choi state
with
Its entanglement fidelity relative to the identity is
For a trace-preserving channel with equal input and output dimension, the Haar-average pure-state fidelity relative to the identity satisfies the Nielsen (2002) relation
This relation does not license silent conditioning on loss. A heralded branch is a completely positive trace-nonincreasing map . Its Choi operator is subnormalized:
The superscript reminds us that is the success probability for the maximally mixed input represented by the Choi experiment. If success depends strongly on the input, one number does not certify uniform transmission. Report success behavior and conditional quality together, including the failed trials in the attempt count. Only when success is input independent does division of by its constant success probability give a trace-preserving conditional channel. Process tomography explains the reconstruction problem.
Herald timing matters. For an event-ready Bell test, the event definition and herald must be fixed before the endpoint settings are chosen. Otherwise the herald can become outcome- or setting-dependent postselection.
Quality, delivery and simultaneous confidence
Section titled “Quality, delivery and simultaneous confidence”An application may require fidelity above , delivered rate above and latency below a deadline with probability at least . It also needs correct endpoint, memory-slot and Pauli-frame labels. These are distinct requirements: a highly accurate state delivered rarely or under the wrong label does not satisfy them.
There are two different statistical questions. To publish several component statements with a guarantee that none is false, a simple sufficient allocation is
The union bound does not require independence. Four separately published 99% confidence intervals need not have 99% simultaneous coverage.
Alternatively, suppose the only output is accept the whole service if every component test passes. Its bad-service null is the union of the component failures. If each component test has false-pass probability at most whenever its own null holds, uniformly over the other parameters, the entire conjunction already has false-pass probability at most . At least one component is bad, and passing every test entails falsely passing that bad component. This intersection-union test does not require dividing by the number of components. It provides the global accept/reject guarantee, not simultaneous coverage of all reported intervals.
Neither construction justifies pooling distinct request classes. Routes, memory ages, deadlines and calibration epochs can have different performance. Test the class of deliveries the application will actually receive; a weighted average can conceal a consistently poor route.
Diagnosing routes and monitoring drift
Section titled “Diagnosing routes and monitoring drift”End-to-end failure should be detected end to end. Component tests are then useful for localization. Testing only components can miss correlated phase errors, wrong Bell labels, timing mismatches, swap-feed-forward faults, and software identity errors that appear only after composition.
In a simplified additive model, route statistic depends on link parameters through
or in vector form
All link parameters are identifiable only if the probe-route matrix has the required rank. If has a nontrivial null space, several internal fault patterns produce the same end-to-end data. More trials reduce statistical noise but do not cure structural nonidentifiability.
The additive model itself must be validated. Coherent errors can interfere, memory noise depends on stochastic waiting time, swapping can correlate branches, and purification changes both state quality and selection. Network tomography is therefore model-based diagnosis, not a substitute for direct service verification.
Finite statistics
Section titled “Finite statistics”For independent bounded observations , Hoeffding’s inequality gives
Here . Independence is required in this form; identical distributions and stationarity are not. If the means drift, the bound concerns their average over these trials and need not describe tomorrow’s state. Hoeffding (1963) supplies the bounded-variable inequality.
For example, independent Pauli products measured on copies of a fixed state have one-sided radius
for each of the three correlators, with error apiece. Taking the lower bounds for and the upper bound for , clipped to , gives the joint fidelity bound above with error at most . Measurement calibration error must be included separately; more shots cannot remove it.
Bursts, shared calibration noise and adaptive routing may violate independence. Dirkse et al. (2020) develop witness estimation and rejection methods allowing correlated state preparations and bounded measurement imperfections. Such a method’s assumptions must match the actual setting choices and devices; simply replacing a binomial error bar by a smaller one does not handle memory.
Repeated monitoring introduces another issue. An ordinary fixed-horizon interval is not automatically valid whenever a dashboard happens to be checked. Confidence sequences control coverage across an allowed sequence of stopping times under their model (Howard et al., 2021). A confidence sequence for a constant mean does not by itself detect arbitrary instantaneous drift. Route-specific windows, change-point tests or models for evolving conditional means need their own guarantees.
Finally, a lower confidence bound falling below a threshold means the data no longer establish the required quality. To establish quality below the threshold, one needs an upper confidence bound below it. Withdrawing a service guarantee can therefore be reasonable before there is enough information to demonstrate a failure.
Matching outcomes to the delivered systems
Section titled “Matching outcomes to the delivered systems”A test can be biased by missing attempts, replayed heralds or incorrect endpoint labels even when the quantum measurements are accurate. Keep the attempt identifiers, timing, heralds, no-clicks, exclusions and frame information needed to reconstruct the defined sample. Authentication can reveal some alterations and substitutions; it does not make a dishonest device’s report true. Endpoint comparisons and causal timing checks remain physical parts of the experiment.
A physical Bell-pair test also does not automatically certify a remote logical gate. Encoding, syndrome extraction, decoder behavior, leakage and feed-forward delays enter the application. Distributed quantum computing explains those operations. Distributed sensing may additionally require phase stability and simultaneous availability; cryptographic use requires its own secrecy proof. Choose the measured quantity from the application’s required guarantee.
Exercises
Section titled “Exercises”1. Bell-pair lower bound
Section titled “1. Bell-pair lower bound”Simultaneous confidence intervals give
Find a lower bound on . Does it certify entanglement? Does it certify a service threshold ?
Solution
Use the lower bounds for the positive terms and the upper bound for , because it enters with a minus sign:
Since , the result certifies entanglement under the trusted two-qubit measurement model. It does not certify .
2. Verification sample size
Section titled “2. Verification sample size”A verification operator has gap . How many all-pass trials are sufficient, using the exponential bound, to reject states with infidelity at least at false-acceptance probability ?
Solution
The sufficient bound is
Thus trials suffice. This calculation assumes the all-pass protocol and the product or conditional bad-state promise used in its proof.
3. Conditional quality versus delivery
Section titled “3. Conditional quality versus delivery”A link makes attempts in one hour, heralds pairs, and estimates conditional Bell-state fidelity . State the delivery probability and explain why the fidelity alone does not certify an application requiring at least one pair per ten seconds.
Solution
The empirical herald probability is
The delivered rate is , before any additional application rejection. The average rate is therefore below one pair per ten seconds. The conditional fidelity concerns states given a herald; it does not guarantee rate, latency quantiles, or availability.
4. A classical violation when sources share a bit
Section titled “4. A classical violation when sources share a bit”Let Alice and Charlie share one fair bit . If , both output for either setting. If , they output and . Bob always returns . Find and explain why the result does not show quantum nonlocality.
Solution
For , the four endpoint products are all , giving . For , their signs are , giving . Averaging the two strategies gives
This is an ordinary local model: each output depends only on the shared bit and the local setting. It is not a model with independent sources, because Alice’s and Charlie’s strategy bits are identical. If their strategy bits were independent and fair, and the bound would be saturated. A violation excludes the source-independent null; a common classical cause remains possible when that premise fails.
5. Graph-state fidelity bound
Section titled “5. Graph-state fidelity bound”Four stabilizer generators have simultaneous lower confidence bounds
Use the generator union bound to lower-bound the graph-state fidelity.
Solution
The total generator failure bound is
Therefore
This is a conservative target-state bound under the trusted stabilizer measurement model, not a device-independent statement.
6. Identifiability of three links
Section titled “6. Identifiability of three links”Three unknown link-error parameters are . Two route probes give
Are all links identifiable? What additional route makes the linear system identifiable?
Solution
The first probe matrix is
which has rank . The vector lies in its null space, so the three errors are not identifiable. Adding
gives
whose determinant is , so the linearized parameters are identifiable.
7. Joint intervals and one global decision
Section titled “7. Joint intervals and one global decision”Four metrics are tested: fidelity, delivered rate, latency and resource identity. Give a simple error allocation for publishing all four component statements with total false-statement probability at most . Would the same division be necessary if the only output were a global acceptance requiring all four tests to pass?
Solution
For simultaneous component statements, use . Then the probability of any false statement is at most , without an independence assumption. Four independent intervals with individual coverage would instead have joint coverage .
For the single global decision, each component may have false-pass probability , provided this bound holds uniformly whenever that component is bad. If the service is bad, select any bad component . Then
This proves the global false-acceptance bound. It does not promote separately reported intervals to simultaneous 99% coverage.
8. Design a drift-aware route test
Section titled “8. Design a drift-aware route test”A three-node network alternates between two routes and recalibrates every hour. Sketch a verification design that distinguishes a daily fidelity requirement from detection of a forty-minute outage. Explain what can and cannot be concluded when a lower confidence bound crosses the threshold.
Solution
Stratify by route and calibration epoch, and randomly interleave test and application requests. Preserve attempts, heralds, no-clicks and frame data. Test both the daily aggregate and prespecified shorter windows, with simultaneous or valid sequential error control.
If a lower confidence bound drops below the required fidelity, withdraw the quality guarantee or collect more data. This does not prove the fidelity is too low: that conclusion needs an upper bound below threshold. Conversely, a daily average can remain high throughout a short outage, even with extremely narrow daily confidence intervals.
Detecting a forty-minute outage requires enough tests on the affected route within that interval and sufficient separation between good and bad performance. Specify the failure size and desired detection probability when choosing the sampling rate. Time-uniform coverage alone supplies neither this detection power nor immunity to an incorrectly stationary model.
References
Section titled “References”- C. Branciard, D. Rosset, N. Gisin, and S. Pironio, “Bilocal versus nonbilocal correlations in entanglement-swapping experiments,” Physical Review A 85, 032119 (2012), doi:10.1103/PhysRevA.85.032119.
- B. Dirkse, M. Pompili, R. Hanson, M. Walter, and S. Wehner, “Witnessing entanglement in experiments with correlated noise,” Quantum Science and Technology 5, 035007 (2020), doi:10.1088/2058-9565/ab8d88.
- W. Hoeffding, “Probability inequalities for sums of bounded random variables,” Journal of the American Statistical Association 58, 13–30 (1963), doi:10.1080/01621459.1963.10500830.
- S. R. Howard, A. Ramdas, J. McAuliffe, and J. Sekhon, “Time-uniform, nonparametric, nonasymptotic confidence sequences,” The Annals of Statistics 49, 1055–1080 (2021), doi:10.1214/20-AOS1991.
- M. A. Nielsen, “A simple formula for the average gate fidelity of a quantum dynamical operation,” Physics Letters A 303, 249–252 (2002), doi:10.1016/S0375-9601(02)01272-0.
- S. Pallister, N. Linden, and A. Montanaro, “Optimal verification of entangled states with local measurements,” Physical Review Letters 120, 170502 (2018), doi:10.1103/PhysRevLett.120.170502.
- R. J. Serfling, “Probability inequalities for the sum in sampling without replacement,” The Annals of Statistics 2, 39–48 (1974), doi:10.1214/aos/1176342611.
- I. Šupić and J. Bowles, “Self-testing of quantum systems: a review,” Quantum 4, 337 (2020), doi:10.22331/q-2020-09-30-337.
- A. Ulibarrena et al., “Guarantees on the structure of experimental quantum networks,” npj Quantum Information 10, 117 (2024), doi:10.1038/s41534-024-00911-z.
- A. Unnikrishnan and D. Markham, “Verification of graph states in an untrusted network,” Physical Review A 105, 052420 (2022), doi:10.1103/PhysRevA.105.052420.