

Variance and Standard Deviation
The variance of an observable quantifies the intrinsic spread of its Born-rule measurement outcomes about their expectation value. For a state and a self-adjoint observable , define the centered observable
The variance and standard deviation are
and
The standard deviation has the same physical units as ; the variance has squared units. Neither quantity is, by itself, an apparatus error or a claim about measurement disturbance. It is a property of the observable’s outcome distribution in the specified state.
This page develops the quantum interpretation, operator forms, domain conditions, and examples. For the probability theory behind these formulas, see Variance and Covariance, while the inequalities relating spreads of two observables belong at General Uncertainty Relations.
Required background. Expectation Values supplies the first and second moments used here.
Helpful background. Functions of Operators supplies squared and centered observables.
Spread around the expectation
Section titled “Spread around the expectation”Let be the Born probability measure of . If its second moment is finite, then
The integrand is nonnegative and measures the squared displacement of each outcome from the mean. Outcomes twice as far from the mean contribute four times as much, so variance is especially sensitive to tails and outliers.
Two distributions can have the same expectation but very different spreads.
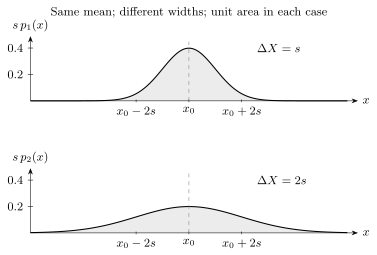
Both distributions are centered at , but the lower distribution has the larger standard deviation. A mean identifies a center; it does not determine the width or shape of the outcome law.
Variance is therefore information beyond the expectation value. It still does not determine the full distribution: laws with different skewness, tails, or multiple peaks can share both mean and variance.
A simple example is a Pauli measurement with equally likely outcomes and . Its mean is zero, but every outcome lies one unit from that mean, so its variance and standard deviation are both one. A zero average can therefore coexist with substantial uncertainty about each individual result.
Equivalent moment formula
Section titled “Equivalent moment formula”Expanding the centered square gives
Thus
The central-moment form and raw-moment form are mathematically equivalent when the moments exist. The central form is often numerically safer because and can be large, nearly equal numbers whose subtraction loses floating-point precision.
Discrete outcomes
Section titled “Discrete outcomes”For a discrete spectral decomposition
the probability of outcome is
The variance is the ordinary discrete second central moment:
Equivalently,
Degeneracy is already included because projects onto the entire eigenspace. The probabilities themselves are developed at Born Rule for Discrete Spectra.
Continuous and mixed outcomes
Section titled “Continuous and mixed outcomes”If the spectral probability measure has density , then
For one-dimensional position,
For a mixed spectral law with atomic weights at and continuous density ,
The density, atoms, and coordinate-measure rules are treated at Born Rule for Continuous Spectra.
Pure-state norm form
Section titled “Pure-state norm form”For a normalized pure state, define
Then
This form immediately proves
It also supplies the vectors used in the Cauchy–Schwarz derivation of quantum uncertainty relations. The norm form is more than a proof trick: for unbounded operators, it expresses the second spectral moment without unnecessarily requiring to exist as a vector.
Domain and finite-moment conditions
Section titled “Domain and finite-moment conditions”For a pure state and self-adjoint , a finite second moment requires
This is equivalent to
and then
The notation in a variance formula should therefore be understood as this second spectral moment or quadratic form. Requiring the operator expression would demand , a stronger condition that is not needed merely to define the variance.
A normalized state can have a finite mean but infinite second moment. In that case the standard deviation is infinite, and formulas that assume a finite variance, such as the usual standard error of a sample mean, do not apply.
Density-operator formula
Section titled “Density-operator formula”For a density operator and a bounded observable ,
Equivalently,
For unbounded , these traces require the corresponding finite-moment and domain conditions. The full trace formalism is at Trace Rule for Expectation Values.
Spread within and between preparation components
Section titled “Spread within and between preparation components”Suppose a preparation is represented as
Let
The law of total variance gives
The first term averages the outcome spreads within the component states; the second is the spread of their means. A component may itself be mixed, so this is not a unique separation into quantum and classical noise. This decomposition depends on the chosen ensemble realization of , whereas the total variance depends only on . Because a density operator generally has many ensemble decompositions, the two terms are not intrinsic state invariants separately.
Affine transformations and units
Section titled “Affine transformations and units”For real and ,
and
Adding a constant shifts every outcome and the mean by the same amount, so it does not change the spread. Multiplying the observable rescales every deviation.
For example, if , then
This scaling is also a dimensional check: standard deviation carries the observable’s units, while variance carries their square.
Two-outcome formula
Section titled “Two-outcome formula”Let have outcomes and with probabilities and . Its expectation is
Direct calculation gives
The variance vanishes at or , when the outcome is certain, and is maximal at . For fixed outcomes,
This compact formula covers projective measurements of any two-level observable.
Example: spin one-half
Section titled “Example: spin one-half”Consider
For ,
Therefore
For the physical spin component,
The phase does not affect the -outcome probabilities, but it affects spreads of spin components along other directions. The eigenstates have zero variance, while an equatorial state has the maximal value .
Qubit form for arbitrary direction
Section titled “Qubit form for arbitrary direction”Let
and measure
Because ,
A pure state with has a definite outcome and zero variance. The maximally mixed state has and unit variance for every spin direction, even though every spin expectation vanishes.
Example: Gaussian position spread
Section titled “Example: Gaussian position spread”Consider the normalized position density
Its first two raw moments are
Consequently,
Wavefunctions are often parameterized with symbols called “width” that differ by factors of or . Computing the variance identifies the physical standard deviation independent of naming convention.
Zero variance and definite values
Section titled “Zero variance and definite values”For a pure state, the norm form implies
if and only if
Thus the state is an eigenvector of with eigenvalue .
For a mixed state, zero variance means that the support of lies entirely inside one eigenspace of :
The state may still be mixed within a degenerate eigenspace. Zero variance therefore implies a definite measurement value, not necessarily a pure state.
Spectral bounds on variance
Section titled “Spectral bounds on variance”If the spectrum relevant to the measurement lies in , then the Bhatia–Davis bound gives
Since the product on the right is at most ,
For a qubit observable with outcomes , this yields . Such bounds are strong sanity checks for analytic and numerical calculations.
Estimating variance from data
Section titled “Estimating variance from data”For independent outcomes from the same preparation and measurement, define the sample mean
The usual unbiased estimator of the population variance is
The factor corrects the bias introduced by estimating the mean from the same data. The quantum prediction is the population quantity that repeated experiments estimate; one should not confuse it with a particular finite-sample value .
When the variance is finite, the standard deviation of the sample mean is
This describes independent statistical fluctuations. Correlated trials, drifting preparations, and detector systematics require a more complete error model.
Intrinsic spread and detector noise
Section titled “Intrinsic spread and detector noise”Suppose a recorded value has the additive form
where the ideal quantum outcome and detector noise are independent and have finite variances. Then
This decomposition is a model assumption, not a universal measurement law. Correlated noise, nonlinear response, and general POVMs require different treatments. It nevertheless illustrates why intrinsic quantum spread and instrumental resolution should be specified separately.
Numerical stability
Section titled “Numerical stability”The identity
can suffer catastrophic cancellation when both terms are large compared with their difference. In numerical work, prefer a centered calculation such as
or a stable online variance algorithm for sampled data. A tiny negative result at the level of floating-point roundoff should be diagnosed and clipped only after verifying normalization and Hermiticity; a materially negative variance signals an error.
Bridge to uncertainty relations
Section titled “Bridge to uncertainty relations”For two observables, define centered-state vectors
for with . Their norms are and . Cauchy–Schwarz therefore constrains the product of the two standard deviations. Separating commutator and anticommutator contributions leads to the Robertson and Schrödinger uncertainty relations.
The familiar bound
uses the operator commutator when its products are defined on the state. On the weaker domain , replace its right side by . Both forms concern outcome-distribution spreads in one state. It is not, by itself, a statement about detector precision or how one measurement disturbs another. For the derivation, domains, and equality conditions, see General Uncertainty Relations.
Common pitfalls
Section titled “Common pitfalls”Use the operator square. In , means , not the entrywise square of a matrix. Subtract the square of the mean afterward.
Do not identify spread with detector error. The ideal Born distribution can have nonzero variance with a perfectly resolved detector. Additional instrumental noise requires a measurement model.
Check the second moment. Normalization and even a finite mean do not guarantee finite variance. For a pure state, the relevant condition is membership in , not the stronger .
Exercises
Section titled “Exercises”1. Spin variance from Born probabilities
Section titled “1. Spin variance from Born probabilities”Let and
Compute , , and .
Solution
The probabilities of and are and . Hence
Since ,
2. General two-outcome variance
Section titled “2. General two-outcome variance”An observable returns with probability and with probability . Derive
and find the probability that maximizes it.
Solution
The mean is . The deviations are
and
Therefore
The factor is maximal at , where it equals .
3. Gaussian position distribution
Section titled “3. Gaussian position distribution”Suppose
Given and , compute the variance after the shifted observable is introduced, where has units of length.
Solution
First,
The constant shift does not affect variance, while multiplication by multiplies it by :
4. Zero variance for a mixed state
Section titled “4. Zero variance for a mixed state”Let have a degenerate eigenvalue with orthonormal eigenvectors and . Consider
Compute the variance of and explain why zero variance does not imply that is pure.
Solution
Every state in the support of has the same outcome . Therefore
and
For , the density operator is mixed, but its support lies entirely in one degenerate eigenspace. The observable cannot distinguish mixtures within that eigenspace.
5. Total variance of a preparation mixture
Section titled “5. Total variance of a preparation mixture”Two preparation procedures are selected with probabilities and . Their outcome means are and , and their variances are and . Derive the total variance.
Solution
The total mean is
The law of total variance gives
For two components, the between-means term simplifies to
Thus
6. Finite mean and infinite variance
Section titled “6. Finite mean and infinite variance”Consider the even density
Verify normalization, show that exists, and show that the variance diverges.
Solution
Normalization follows from
The absolute first moment is finite:
Hence evenness legitimately gives . But
diverges logarithmically because the integrand behaves as at large . The mean exists, but the variance is infinite.
7. Qubit variance in Bloch form
Section titled “7. Qubit variance in Bloch form”For
and with , derive the variance. Evaluate it for the maximally mixed state.
Solution
The Pauli algebra gives , while
Therefore
For the maximally mixed state, , so the variance is for every measurement direction. Its vanishing spin expectation does not mean a sharp zero outcome; the only outcomes are and they are equally likely.
8. Sample size for a mean estimate
Section titled “8. Sample size for a mean estimate”An observable has in a fixed state. Assuming independent trials and negligible systematics, how many measurements make the standard deviation of the sample mean no larger than ?
Solution
Use
The requirement
implies , hence
This is a statistical requirement only. Increasing does not automatically remove systematic preparation or detector errors.
References
Section titled “References”- L. E. Ballentine, Quantum Mechanics: A Modern Development, 2nd ed., World Scientific, 2014, Chapters 2–3.
- R. Bhatia and C. Davis, “A Better Bound on the Variance,” American Mathematical Monthly 107, 353–357 (2000).
- B. C. Hall, Quantum Theory for Mathematicians, Springer, 2013, Chapters 7–10.
- M. Reed and B. Simon, Methods of Modern Mathematical Physics, Vol. I: Functional Analysis, revised and enlarged ed., Academic Press, 1980, Sections VII.1–VII.3 and VIII.3.
- J. J. Sakurai and J. Napolitano, Modern Quantum Mechanics, 3rd ed., Cambridge University Press, 2020, Chapters 1–2.
- R. Shankar, Principles of Quantum Mechanics, 2nd ed., Springer, 1994, Chapters 1 and 4.
- J. von Neumann, Mathematical Foundations of Quantum Mechanics, Princeton University Press, 1955, Chapters II–III.