

Born Rule for Continuous Spectra
For an observable with continuously varying outcomes, the Born rule assigns probabilities to measurable sets of outcomes. A probability density is a useful derivative of that probability law when such a derivative exists; it is not the probability of an exact value.
This distinction is easy to blur in notation. The familiar statement is correct for position in the standard representation, but the logically prior statement is
where is the spectral projector associated with a measurable set . This page develops densities, interval probabilities, coordinate changes, mixed spectra, and finite resolution from that measure-first formulation. The general probability postulate is explained in Born Rule; the companion page Born Rule for Discrete Spectra handles countable outcomes.
Required background. The Born Rule supplies probabilities for measurement events.
Helpful background. Wavefunctions as Representations supplies continuous-basis amplitudes; Spectra distinguishes discrete, continuous, and mixed cases. Familiarity with integrating probability densities and transforming them with Jacobians is assumed.
Position probabilities in a region
Section titled “Position probabilities in a region”For a normalized one-dimensional wavefunction ,
The position density with respect to is
and therefore
In the position representation, the spectral projector acts by multiplying a wavefunction by the indicator function of the set:
It follows directly that
The density has units of inverse length in one dimension. Its value at one isolated point can be changed without changing the physical state as an element of or changing any interval probability.
Why probabilities belong to sets
Section titled “Why probabilities belong to sets”A measuring device reports an event in a set: a pixel, an energy channel, a time window, or a numerical bin. The probability of that event is the measure of the set. A density value is not itself a probability and is defined only almost everywhere, so it depends on the chosen representative and reference measure. Sets are therefore both the mathematically natural events and the experimentally natural ones.
Let be self-adjoint, let be its projection-valued measure, and let be a density operator. Define
for each Borel set . The map is a probability measure:
whenever the sets are pairwise disjoint. For a pure state, , this becomes
The observable supplies the spectral projectors; the state supplies their probabilities. Consequently, the relevant probability law is always state-dependent even though the spectrum of is not.
From a probability measure to a density
Section titled “From a probability measure to a density”Suppose the spectral probability measure is absolutely continuous with respect to Lebesgue measure . Then there is a nonnegative function , defined up to changes on sets of Lebesgue measure zero, such that
In measure-theoretic language, the density is the Radon–Nikodym derivative
It obeys
If carries physical units , then has units . Only the product is a dimensionless probability.
Not every spectral measure admits a density with respect to . Discrete components give atoms, and singular-continuous measures can occur in more specialized spectral problems. The measure is always the safe starting point; a density is an additional representation of its absolutely continuous part.
Probability is area, not height
Section titled “Probability is area, not height”When a density exists, an interval probability is the area under the density:
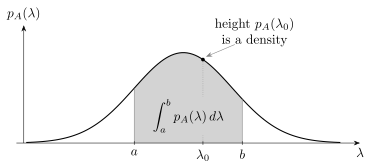
For an absolutely continuous probability law, the shaded area is . The height is a density, not the probability of the exact value ; an atomic component would have to be represented separately.
A narrow bin of width centered at has probability
If is continuous near and the bin is sufficiently narrow,
This local approximation explains why histograms estimate density by dividing bin frequencies by bin width.
Exact values, null sets, and atoms
Section titled “Exact values, null sets, and atoms”For an absolutely continuous probability law,
The conclusion follows because a singleton has zero Lebesgue measure. It does not mean that the measurement cannot return a numerical value. It means that no preselected exact value has positive probability under the idealized continuous law.
The qualifier “absolutely continuous” matters. For any self-adjoint ,
is the projector onto the eigenspace at . If the state has a nonzero component in that eigenspace, then
Such a point mass is called an atom. An observable can have bound-state eigenvalues and a scattering continuum at the same time, so the slogan “exact values have probability zero” must never be applied indiscriminately to a mixed spectrum.
Endpoint conventions
Section titled “Endpoint conventions”For a purely absolutely continuous law, the intervals , , , and have the same probability because their differences are singletons. Thus
in that case.
If an endpoint is an atom, brackets matter. For example, if , then
This is one reason spectral events should be written as explicit sets rather than inferred from an integral alone.
Generalized eigenvectors and delta normalization
Section titled “Generalized eigenvectors and delta normalization”The notation
is a useful generalized-basis expression. It is not a sum over normalizable Hilbert-space vectors. The position kets satisfy the distributional relations
interpreted in the appropriate weak or rigged-Hilbert-space sense. The delta function and generalized eigenvectors explain the distributional meaning of this notation.
More generally, suppose a continuous spectral sector is labeled by and a discrete degeneracy index . With the convention
write
Then the density with respect to is
with an integral replacing the sum if the degeneracy label is itself continuous. The amplitudes inherit units from the delta-normalization convention; is dimensionless.
Momentum probability density
Section titled “Momentum probability density”In the momentum representation,
Thus
The ket is delta-normalized, whereas a physical wave packet is normalizable. The Fourier transform relating and depends on convention, but a consistent convention always preserves normalization. See Momentum-Space Representation for that transformation and its factors of and .
Densities change under relabeling
Section titled “Densities change under relabeling”A density is always a density with respect to a specified measure and variable. Let , with one-to-one and differentiable and with a differentiable inverse on the relevant domain. Probability in corresponding small intervals satisfies
so
If several regular inverse branches contribute, their probabilities add:
This formula is the continuous analogue of summing probabilities over distinct fine-grained outcomes that produce the same coarse-grained result.
For example, implies
not merely . The factor of supplies the Jacobian and the correct units.
Worked example: a Gaussian interval
Section titled “Worked example: a Gaussian interval”Consider the normalized density
For an interval centered at with half-width ,
The density at the center is , whose numerical value can exceed one in a chosen length unit when is small in that unit. There is no contradiction: a density is not constrained to be at most one. Only integrated probabilities must lie in .
Free-particle energy and degeneracy
Section titled “Free-particle energy and degeneracy”For a one-dimensional free particle,
Every receives contributions from two momentum values, . Applying the many-branch change-of-variable rule gives
The factor is the Jacobian . The two terms are the right-moving and left-moving degeneracy branches. Although the density may have an integrable behavior near zero, normalization is preserved:
In higher dimensions or in scattering with internal channels, direction, angular momentum, polarization, or spin can provide additional degeneracy labels. One must sum or integrate over every unobserved label.
Three-dimensional position measurements
Section titled “Three-dimensional position measurements”For a wavefunction normalized with respect to Euclidean volume,
the probability of a spatial region is
Here is a density with respect to the geometric volume measure , not with respect to an arbitrary triple of coordinate differentials.
In spherical coordinates,
so
The factor is a coordinate Jacobian. Omitting it changes the probability measure.
Marginal and radial densities
Section titled “Marginal and radial densities”If an experiment records only the radius, angular outcomes must be integrated out. The radial density with respect to is
It satisfies
For a separated central-potential state
with normalized spherical harmonic, the radial density is
Thus alone is not the probability density for radius. If one instead defines the reduced radial function , then is the radial density with respect to .
Density operators in a continuous basis
Section titled “Density operators in a continuous basis”For a density operator, choose a positive-state decomposition
with normalized wavefunctions . The position density is the nonnegative, almost-everywhere finite sum
The Born probability of a region is consequently
Normalization follows by interchanging the nonnegative sum and integral:
The density is conventionally written . Here the diagonal comes from the positive-state sum, not from restricting an arbitrary kernel representative: changing a kernel only on leaves its integral operator unchanged. Brislawn’s Theorem 3.1 gives a precise construction of a traceable diagonal. The representation issue is explained in Wavefunctions as Representations.
For a concrete check, take on and zero elsewhere. On that interval the pure-state kernel is . Replacing only by zero produces the same operator, since removing one point from the integral changes nothing. Its naively restricted diagonal is zero, but the physical density remains and
The density depends on the chosen basis. Position probabilities use the position-basis diagonal; momentum probabilities use . Off-diagonal elements encode coherence and affect probabilities in other measurement bases even though they do not appear directly in a position measurement.
Mixed discrete and continuous spectra
Section titled “Mixed discrete and continuous spectra”An observable need not be wholly discrete or wholly continuous. For a state whose spectral measure has discrete weights and an absolutely continuous density , probabilities take the form
with
A Hamiltonian with bound states and scattering states is the standard example. The probability of an exact bound-state energy may be nonzero, while the probability of any preselected scattering energy is zero for an absolutely continuous scattering component.
The page Discrete and Continuous Spectra classifies the operator-level spectral possibilities. The formula above is the corresponding state-level probability decomposition.
Cumulative distributions
Section titled “Cumulative distributions”The cumulative distribution function is defined directly from the spectral measure:
It is nondecreasing and right-continuous, with limits
Where an ordinary density exists and is differentiable,
An atom of weight appears as a jump of size in . This single object therefore represents discrete, continuous, and mixed probability laws without changing notation.
Expectation values from a density
Section titled “Expectation values from a density”If the absolute first moment is finite, the mean is
and, when the second moment is finite,
For a mixed spectrum, add the atomic contributions:
Normalization alone does not guarantee that the mean or variance is finite. Heavy-tailed spectral distributions can make these moments diverge even though the Born probabilities themselves are well defined. The discussion of moments is at Expectation Values.
Finite detector bins
Section titled “Finite detector bins”An ideal binning measurement partitions the outcome axis into disjoint sets . Its probabilities are
for an absolutely continuous law. If the bins cover the axis up to a null set,
This is a genuine discrete distribution produced by coarse-graining a continuous outcome. Refining the bins changes the numbers but not the underlying measure.
A histogram based on repetitions estimates by . To estimate a density over a bin of width , one plots approximately
Without the division by width, the histogram estimates bin probability rather than probability density.
Finite resolution and response functions
Section titled “Finite resolution and response functions”Real instruments can blur as well as bin. Let be a conditional response density for recording when the ideal value is , with
If the ideal law has density , the recorded density is
This classical postprocessing preserves normalization:
More general detectors are described by POVMs and need not be postprocessings of a sharp observable. For examples, see POVMs: First Encounter. A singleton is a meaningful measurable event and has probability zero for an absolutely continuous law. Finite resolution implements a different event—or, more generally, a smeared POVM effect—rather than turning a density value into an exact-outcome probability.
Common pitfalls
Section titled “Common pitfalls”Keep the measure with the density. A change of variable changes the density. In particular, a radial probability includes the spherical volume factor and the integration over unobserved angles.
Separate exact values from bins. A point has zero probability in an atomless distribution; a finite detector bin can have positive probability. A bound-state energy can also have positive point probability, because it is an atom of the spectral law.
Include every unobserved branch. A free-particle energy in one dimension receives contributions from positive and negative momentum. Dropping a branch discards genuine probability.
Exercises
Section titled “Exercises”1. Uniform wavefunction on an interval
Section titled “1. Uniform wavefunction on an interval”Let
Find the probability that . State the units of .
Solution
The density is on . Therefore
Because is dimensionless, has units of inverse length. The wavefunction has units of inverse square-root length.
2. Gaussian central probability
Section titled “2. Gaussian central probability”A position measurement has density
Find and explain why even though the density is maximal at .
Solution
With ,
The singleton has zero Lebesgue measure, so its integral is zero. A large density at the origin means that sufficiently narrow bins near the origin carry more probability per unit width than comparable bins elsewhere; it is not a point probability.
3. A nonlinear change of variable
Section titled “3. A nonlinear change of variable”Let have density
and define . Find and verify its normalization.
Solution
For , the only inverse branch in the support is , with
Hence
The integrable singularity at does not spoil normalization. Setting gives
4. Radial density of a hydrogenic state
Section titled “4. Radial density of a hydrogenic state”Consider the normalized spherically symmetric wavefunction
Find the radial density and the most probable radius. Compare this with the point at which the spatial density is largest.
Solution
Integrating over solid angle gives
It is normalized because
For ,
so the radial density is maximal at . By contrast, the spatial density is maximal at . The distinction arises from the number of spatial points available in a shell, represented by .
5. Momentum to free-particle energy
Section titled “5. Momentum to free-particle energy”Let a normalized one-dimensional momentum density be even: . Derive the free-particle energy density for and show directly that it is normalized.
Solution
For , the inverse branches are and each has
Adding both branches and using evenness,
With , one has , and therefore
6. A mixed spectral law
Section titled “6. A mixed spectral law”An energy measurement has an atom of weight at and an absolutely continuous component on :
where and . Find the probabilities of the events , , and .
Solution
The atom gives
The continuum interval has probability, using ,
The interval contains both components, so
This example shows why an integral over an ordinary density cannot represent the atomic probability by itself.
7. Density-operator kernel
Section titled “7. Density-operator kernel”Let
where both wavefunctions are normalized. Derive the position density and explain whether a relative phase between and appears.
Solution
The position-space kernel is
Taking its diagonal gives
There is no cross term and hence no relative phase in this incoherent mixture. A coherent combination instead has the form
where
Its position density can contain interference. Individually normalized components do not generally give a normalized superposition: their overlap and relative phase determine . Orthogonal components give .
8. Detector blurring
Section titled “8. Detector blurring”Suppose an ideal outcome has normalized density and a detector has translation-invariant Gaussian response
Show that the recorded density is normalized. If the ideal distribution has finite mean and variance , find the recorded mean and variance.
Solution
The recorded density is
Because the integrand is nonnegative, the order of integration may be exchanged:
The response can be viewed as , where is independent, Gaussian, has mean zero, and has variance . Therefore
Detector blurring preserves the mean for this unbiased response but adds its own variance to the intrinsic outcome variance.
References
Section titled “References”- C. Brislawn, “Traceable Integral Kernels on Countably Generated Measure Spaces,” Pacific Journal of Mathematics 150, 229–240 (1991), Theorem 3.1 and Corollary 3.2.
- P. Busch, P. J. Lahti, J.-P. Pellonpää, and K. Ylinen, Quantum Measurement, Springer, 2016, Chapters 3–5.
- P. A. M. Dirac, The Principles of Quantum Mechanics, 4th ed., Oxford University Press, 1958, Chapters II–III.
- B. C. Hall, Quantum Theory for Mathematicians, Springer, 2013, Chapters 7–10.
- A. Messiah, Quantum Mechanics, Vol. I, North-Holland, 1961, Chapters IV–V.
- M. Reed and B. Simon, Methods of Modern Mathematical Physics, Vol. I: Functional Analysis, revised and enlarged ed., Academic Press, 1980, Sections VII.1–VII.3.
- R. Shankar, Principles of Quantum Mechanics, 2nd ed., Springer, 1994, Chapters 1 and 4.
- J. von Neumann, Mathematical Foundations of Quantum Mechanics, Princeton University Press, 1955, Chapters II–III.