

Operator Representations
An operator representation is a concrete coordinate form of an abstract operator. Depending on the chosen basis or representation map, the same operator can appear as a matrix, a multiplication rule, a differential expression, an integral kernel, or a diagonal spectral form.
The abstract operator is the basis-independent object. Its representative is the form used for a particular calculation. A valid change of representation must transform states, operators, inner products, and operator domains consistently.
This distinction is not cosmetic. It explains why momentum is a derivative in position space but a multiplier in momentum space, why a local potential becomes a momentum-mixing kernel, and why diagonal, sparse, or real-looking matrices are generally properties of a representation rather than of the operator itself.
Helpful background. Bases and representations explain state coordinates; change of basis gives the overlap-matrix convention used below.
The Representation Map
Section titled “The Representation Map”Let be an operator on a Hilbert space , with domain when is unbounded. A representation is implemented by a unitary map
where is a coordinate Hilbert space such as , , or . Define
The represented action satisfies
This is the master translation rule. A matrix and a differential operator can represent the same because they act in different coordinate Hilbert spaces related by a unitary map.
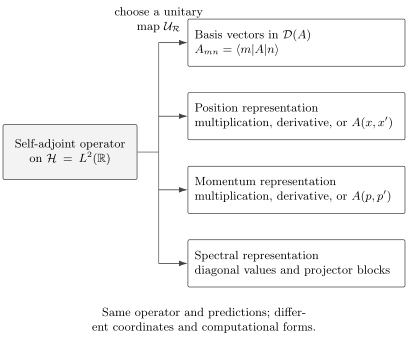
For a self-adjoint particle operator on , these are alternative representations when their bases and domains are specified. A finite-level system instead uses coordinate spaces of its own dimension. Spectra, algebraic identities, and correctly paired predictions agree, while matrix entries and computational form can change.
From One Representation to Another
Section titled “From One Representation to Another”If and are two representations, the unitary map between their coordinate spaces is
Therefore
The detailed passive-basis convention and its alternatives are developed in Change of Basis. The practical rule is simple:
Never transform a state representative without transforming the operator representative and the inner product convention that go with it.
Predictions Are Representation Independent
Section titled “Predictions Are Representation Independent”Unitarity gives
Thus expectation values, transition amplitudes, and probabilities do not depend on the representation when every ingredient is translated consistently. This invariance is a useful error detector: two representations that give different predictions have not been matched correctly.
Discrete Orthonormal Bases
Section titled “Discrete Orthonormal Bases”Let be a finite or countably infinite orthonormal basis. To define the matrix elements of an unbounded , require each . The state coordinates and operator matrix elements are
In finite dimensions, or for bounded in a countable basis, the represented action is matrix multiplication:
In finite dimension the operator can be reconstructed as
For bounded in an infinite basis, use finite compressions , which converge strongly to as . For unbounded , even does not guarantee that arbitrary basis truncations converge in the graph norm ; the domain and convergence must be established separately. This formula makes the distinction precise: is the map, while is its coordinate array in the named basis. The underlying linear algebra is reviewed in Matrices as Linear Maps.
Matrix Algebra Mirrors Operator Algebra
Section titled “Matrix Algebra Mirrors Operator Algebra”For finite matrices in one orthonormal basis,
For a finite matrix, self-adjointness becomes , and unitarity becomes . These matrix conditions express invariant operator properties in a particular orthonormal basis.
In an infinite basis, formal matrix multiplication can hide convergence and domain issues. A coefficient sequence can represent a vector outside even when each basis vector lies in and every matrix element is finite.
A Passive Basis Change
Section titled “A Passive Basis Change”Let be the overlap matrix that sends old state components to new ones:
With this convention, the operator matrix transforms as
The expectation value remains unchanged:
Other books may define the overlap matrix in the opposite direction and write the inverse-looking conjugation. The physics agrees once the state and operator conventions are paired.
Generalized Continuous Representations
Section titled “Generalized Continuous Representations”A continuous representation uses generalized kets satisfying a distributional completeness relation
The state representative is the wavefunction
The generalized kets need not be normalizable vectors in . They are distributional tools whose precise setting is explained in Generalized Eigenvectors. The physical state remains the normalizable vector reconstructed from its wavefunction.
Operator Kernels Are Continuous Matrices
Section titled “Operator Kernels Are Continuous Matrices”The continuous analogue of a matrix element is the kernel
It acts by
For ordinary kernels and sufficient integrability to interchange integrals, matrix algebra becomes
The identity kernel is the delta distribution appropriate to the measure:
These formulas are not permission to multiply arbitrary distributions. Kernels need not be ordinary functions. Differential operators are represented by derivatives of delta distributions, and singular interactions may require additional distributional care.
Position Representation
Section titled “Position Representation”For a spinless particle on the line with canonical momentum and no vector potential,
The position and momentum operators act as
For the common Hamiltonian
the position representative is
These differential expressions are incomplete without domains and boundary conditions. For example, the same formal derivative can describe different self-adjoint momentum operators on different configuration spaces.
Distributional Position Kernels
Section titled “Distributional Position Kernels”The preceding actions can be written as kernels:
For the Hamiltonian,
The derivative acts on the variable. After integration against , the delta distribution reproduces the familiar differential operator.
Momentum Representation
Section titled “Momentum Representation”Choose the convention
The momentum-space wavefunction is . In this representation,
The free Hamiltonian is a multiplication operator:
The Fourier transform, normalization, and domain details are developed in Momentum-Space Representation.
A Local Potential Becomes Nonlocal in Momentum
Section titled “A Local Potential Becomes Nonlocal in Momentum”For an integrable potential , position-space multiplication has momentum-space kernel
Therefore
For polynomial or other suitable tempered potentials, interpret this Fourier integral distributionally on test functions; for more singular cases define the transformed operator and its domain first. A local potential generally mixes momenta. Conversely, a function of momentum is multiplicative in momentum space but generally nonlocal in position space. This is a concrete demonstration that computational locality depends on the chosen representation.
Spin Matrices
Section titled “Spin Matrices”For spin , choose the eigenbasis. Then
while
In the eigenbasis, is diagonal and is off-diagonal. Their eigenvalues and commutation relation do not change. The matrix pattern changes because the state-space basis has changed. The physical laboratory spin axes are held fixed in this passive calculation.
The canonical matrix identities are collected in Pauli Matrices.
Energy and Spectral Representations
Section titled “Energy and Spectral Representations”If a time-independent self-adjoint has a complete orthonormal discrete energy eigenbasis,
then
The Schrödinger equation reduces to independent component equations:
with solution
This simplicity is why the energy representation is adapted to a time-independent Hamiltonian. A different observable need not be diagonal in the same basis; its off-diagonal matrix elements connect energy sectors.
Degeneracy leaves freedom to rotate the basis inside an energy eigenspace. A complete set of commuting observables can supply additional labels. Continuous energy spectra require delta normalization and possible multiplicity labels rather than a simple list of normalizable vectors.
Worked Example: The Oscillator in Two Representations
Section titled “Worked Example: The Oscillator in Two Representations”For the one-dimensional harmonic oscillator, position representation gives
In the number basis , the Hamiltonian is diagonal:
Writing , position is instead tridiagonal:
The multiplication operator and the infinite tridiagonal matrix are two exact representatives of the same abstract . Truncating the matrix to finitely many number states is a separate approximation.
Composite-System Representations
Section titled “Composite-System Representations”For a product basis
a local operator has matrix elements
Changing local bases conjugates the matrix by . The abstract tensor-product operator and its locality to subsystem remain unchanged. The physical interpretation is developed in Subsystems and Local Observables.
Domains Transform with the Operator
Section titled “Domains Transform with the Operator”For an unbounded operator, the pair is the operator. Under a unitary representation map,
This condition preserves self-adjointness:
where each adjoint is taken with its correct Hilbert-space inner product and domain.
A formal differential expression without a domain is not a complete representation of an unbounded operator. The canonical domain theory is in Domains of Operators and Hermitian vs Self-Adjoint Operators.
Active Transformations Are a Different Question
Section titled “Active Transformations Are a Different Question”The conjugation can appear in two conceptually distinct uses:
- A passive representation change rewrites the same state and operator in new coordinates. Predictions are unchanged because all representatives are transformed together.
- An active physical transformation changes the state, apparatus, or observable relative to a fixed coordinate description. It can represent a rotation, translation, symmetry operation, or time evolution.
The same matrix algebra can occur in both descriptions. One must state what is held fixed before assigning physical meaning.
Exact Representation Change versus Truncation
Section titled “Exact Representation Change versus Truncation”A unitary change of representation is exact and preserves the full operator. A finite truncation instead replaces by a compression such as
For an unbounded , this finite matrix is defined when the retained basis vectors lie in . It is generally not unitarily equivalent to . It can change spectra, domains, commutators, and long-time dynamics. For example, finite matrices cannot satisfy the canonical commutator exactly because
whereas
Numerical basis calculations must therefore be checked for convergence as the truncation grows. The approximation strategy belongs to Discretization.
What Is Representation Invariant
Section titled “What Is Representation Invariant”Unitary equivalence preserves:
- the spectrum, including multiplicities and spectral type;
- self-adjointness, positivity, unitarity, and normality;
- operator norms and trace-class quantities when they are defined;
- products, adjoints, commutators, and functional identities;
- expectation values, transition amplitudes, and measurement probabilities;
- the dimension of kernels and spectral subspaces;
- the transformed domain structure of unbounded operators.
The following are generally representation dependent:
- state components and pointwise wavefunction values;
- individual matrix elements;
- whether a representative is diagonal, sparse, banded, real, or dense;
- whether an operator looks multiplicative, differential, or integral;
- which couplings appear as off-diagonal entries;
- the computational cost of applying the representative.
An invariant claim should survive unitary translation. A coordinate-dependent claim can still be useful, but its representation must be named.
Choosing a Useful Representation
Section titled “Choosing a Useful Representation”- Position representation exposes local spatial potentials, geometry, boundary conditions, and configuration-space probability density.
- Momentum representation diagonalizes translations and free motion and turns derivatives into multipliers.
- Energy representation simplifies time evolution under a time-independent Hamiltonian.
- Spin or angular-momentum bases adapt calculations to a measurement axis or rotational symmetry.
- Symmetry-adapted bases block-diagonalize operators by conserved quantum numbers.
- Product bases expose subsystem structure and local operators.
- Numerical bases are chosen for sparsity, convergence, conditioning, and efficient matrix-vector products.
There is no universally best representation. The best one makes the dominant operator, symmetry, or boundary condition simple without obscuring the quantity being computed.
Common Pitfalls
Section titled “Common Pitfalls”Translate state and operator together. With , use . Comparing with the old operator usually changes the expectation value because the coordinate conventions no longer match.
Keep the transformed domain. A derivative and a multiplier can represent the same self-adjoint momentum operator only when the Fourier transform also maps their domains. Formal differential expressions alone do not establish unitary equivalence.
Separate basis change from approximation. A finite compression discards components. It may approximate low-energy predictions well while failing exact identities, as the oscillator commutator exercise below illustrates.
For a compact formula comparison, use the Representation Translation Table.
Exercises
Section titled “Exercises”Exercise 1: Matrix action and reconstruction
Section titled “Exercise 1: Matrix action and reconstruction”Let in a finite orthonormal basis. Derive both
and the reconstruction formula for .
Solution
Insert completeness between the bra and the state:
Insert completeness on both sides of :
Exercise 2: Spin basis change
Section titled “Exercise 2: Spin basis change”In the basis, let
Compute and interpret the result.
Solution
The matrix is real, symmetric, and unitary. Direct multiplication gives
The old -component operator is represented by in the basis of eigenvectors. Its eigenvalues remain ; only its coordinate matrix has changed.
Exercise 3: Kernel product and adjoint
Section titled “Exercise 3: Kernel product and adjoint”Starting from
derive the kernels of and , assuming ordinary kernels and sufficient integrability for each interchange of integrals.
Solution
Apply first and substitute:
Therefore
Comparing with gives
Exercise 4: Canonical commutator in position space
Section titled “Exercise 4: Canonical commutator in position space”On the Schwartz space of smooth rapidly decreasing functions on the line, verify that and satisfy .
Solution
Compute the two orders:
Subtracting gives
The calculation is valid on a domain where both compositions are defined. It does not by itself settle self-adjoint boundary conditions.
Exercise 5: Position in momentum space
Section titled “Exercise 5: Position in momentum space”Using
for a Schwartz wavefunction, show that multiplication by becomes .
Solution
Let . Differentiating the transform gives
Therefore
The final expression is the Fourier transform of . Hence
on the transformed domain.
Exercise 6: Oscillator position matrix
Section titled “Exercise 6: Oscillator position matrix”Use
to show that the number-basis matrix of is tridiagonal.
Solution
The ladder actions are
Therefore
Only the first off-diagonals are nonzero, so the matrix is tridiagonal.
Exercise 7: Domain under Fourier transformation
Section titled “Exercise 7: Domain under Fourier transformation”Let be the unitary position-to-momentum Fourier transform and let be self-adjoint on its standard real-line domain. State the operator and domain of .
Solution
Fourier transformation turns differentiation into multiplication, so
The transformed domain is
Equivalently, . Carrying the domain through the unitary map is what preserves self-adjointness.
Exercise 8: The commutator at a truncation boundary
Section titled “Exercise 8: The commutator at a truncation boundary”Retain oscillator number states . Let and be the compressed ladder matrices. Show that
Use this to find , where and with .
Solution
For , both ladder paths are retained, so . At the top state, , while . Thus the top diagonal entry is , giving the stated result.
Consequently,
Its trace is zero, as every finite matrix commutator requires. The correction acts entirely at the truncation boundary: states supported below the top level have the expected commutator expectation, but the full finite matrices do not satisfy the canonical relation.