

Tensor Networks Preview
A tensor network represents a high-rank many-body object by contracting a graph of lower-rank tensors. For a pure state in a local product basis,
the coefficient array contains complex entries when every site has local dimension . A tensor network replaces that generic array by a structured factorization. If is a graph with one physical index at each vertex and one virtual index on each internal edge, then a broad class of tensor-network states has amplitudes
Each virtual index ranges over
where is the bond dimension of edge . The network topology and bond dimensions determine which correlation and entanglement patterns are inexpensive to represent.
This is the central promise and the central limitation:
Tensor networks replace unrestricted many-body complexity by a chosen geometry of information flow.
They do not abolish exponential complexity. A network may require exponentially large bond dimensions, may be hard to contract even at modest bond dimension, or may be difficult to optimize. The useful question is therefore not merely whether a state has a tensor-network representation. Every finite state does, if sufficiently large tensors are allowed. The useful question is whether the state admits a controlled, contractible, and verifiably converged representation in the chosen network family.
Helpful background. Tensor products explains the local factors; singular-value decomposition and the Schmidt decomposition supply the rank and truncation arguments.
Physical indices and virtual bonds
Section titled “Physical indices and virtual bonds”State and basis
Section titled “State and basis”Unless stated otherwise:
- is a normalized pure state;
- is the number of physical sites or local factors;
- is the local physical dimension;
- denotes a uniform local dimension;
- is a physical basis label;
- is a contracted virtual label;
- is the virtual dimension on edge ;
- denotes a typical MPS bond dimension;
- logarithms are natural, so entropies are in nats.
The product basis is part of the representation. Reordering sites or changing orbitals can radically change the bond dimension needed for a given accuracy even though the physical state is unchanged.
Exact and approximate statements
Section titled “Exact and approximate statements”An exact tensor network reproduces every coefficient . An approximate network represents a state whose error is controlled under a declared metric, such as:
the infidelity
or errors in selected observables. A small variational energy alone does not certify every one of these quantities.
State networks and operator networks
Section titled “State networks and operator networks”A state network has physical ket legs. An operator network has paired input and output legs. A density operator may be represented directly, through a purification, or through another positive parameterization. These choices have different positivity, normalization, and contraction properties.
Diagrams are contraction instructions
Section titled “Diagrams are contraction instructions”In a tensor diagram:
- a node denotes a multilinear array;
- a dangling leg denotes a free index;
- a joined pair of legs denotes a sum over their common index;
- cutting an internal leg exposes a virtual vector space;
- bending or crossing lines may carry convention-dependent meaning, especially for fermions.
A diagram is not automatically a quantum circuit. Generic tensors need not be unitary or isometric, and the drawing need not represent time evolution.
From One Tensor to a Network
Section titled “From One Tensor to a Network”A tensor as a multilinear map
Section titled “A tensor as a multilinear map”A local tensor with one physical leg and virtual legs can be viewed as components
or as a linear map
This map viewpoint is especially useful for projected entangled-pair states: virtual entangled pairs live on graph edges, and local maps turn the incident virtual degrees of freedom into physical sites.
Contraction
Section titled “Contraction”Joining two tensor legs of equal dimension means summing over that index. For tensors and ,
This is ordinary matrix multiplication when both tensors have rank two. Higher-rank networks generalize the same operation.
The final object depends on which legs remain open:
| Open legs | Result |
|---|---|
| none | scalar, such as a norm or partition function |
| physical ket legs | state amplitudes |
| input and output legs | operator or channel |
| selected boundary legs | effective environment or boundary state |
Parameter count is only a first diagnostic
Section titled “Parameter count is only a first diagnostic”For a regular network with site tensors, physical dimension , coordination number , and uniform bond dimension , a site-dependent raw parameter count scales as
This can be vastly smaller than . But raw parameter count does not answer three decisive questions:
- How large must become for the target state and error tolerance?
- How difficult is it to contract the resulting network?
- Can an optimization procedure find an accurate tensor set?
Gauge redundancy also means that different tensor entries can represent the same physical state, so the raw count overestimates the true number of state-space directions.
Virtual Gauge Freedom
Section titled “Virtual Gauge Freedom”Consider two neighboring tensors joined along an internal bond. In matrix notation, their contraction contains
For any invertible matrix on the shared virtual space,
Thus the transformations
leave the physical amplitudes unchanged.
Consequences
Section titled “Consequences”Virtual gauge freedom means:
- individual tensor entries are not observables;
- norms of neighboring tensors can be redistributed without changing the state;
- optimization can contain flat or poorly conditioned directions;
- canonical or isometric gauges can expose Schmidt data and improve stability;
- comparing tensors from two calculations requires gauge alignment or gauge-invariant quantities.
For an open MPS, sequential canonical gauges are particularly powerful because the graph is a chain. Networks with loops, such as PEPS, do not generally admit one global canonical form with all the same properties.
Gauge freedom is not physical gauge symmetry
Section titled “Gauge freedom is not physical gauge symmetry”Virtual basis redundancy and a physical gauge constraint are different ideas. The first is a nonuniqueness of tensor coordinates. The second restricts physical states and observables. Symmetric or gauge-invariant tensor networks can connect them structurally, but they should not be identified merely because both use the word “gauge.”
The General Cut Bound
Section titled “The General Cut Bound”The most direct link between tensor networks and entanglement comes from cutting virtual bonds.
Partition the physical vertices into and . Suppose removing an edge set
disconnects all tensors carrying physical legs in from those carrying physical legs in . After exposing those cut indices, the state can be written as
where the compound cut label has dimension
The vectors on either side need not be orthogonal, so this is not necessarily a Schmidt decomposition. It is nevertheless a decomposition with at most that many product terms. Therefore
Equivalently,
Because entropy cannot exceed the logarithm of the support dimension,
For uniform bond dimension and cut edges,
The same rank ceiling bounds every Rényi entropy with positive index:
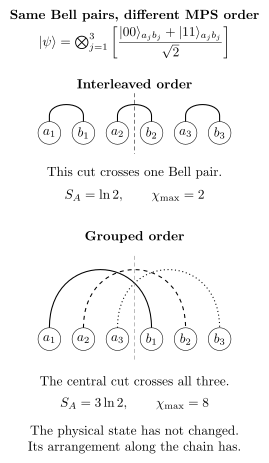
Physical ordering changes which entangled pairs cross an MPS cut. The state is the same product of three Bell pairs in both panels. With interleaved labels, every cut crosses at most one pair, so the maximum exact MPS bond dimension is two. Grouping all sites before all sites makes the central cut cross three independent pairs, requiring dimension eight. Curved lines indicate Bell pairings; their intersections are not interaction vertices.
Min-cut language
Section titled “Min-cut language”Several different virtual cuts may separate the same physical partition. Taking the smallest cut capacity gives the strongest immediate graph bound:
This resembles a discrete minimal-surface rule, but it is generally an upper bound, not an equality. Special networks and limits can make geometric cut formulas much sharper. A generic tensor network does not establish a holographic entropy formula.
What the bound does not say
Section titled “What the bound does not say”The cut bound does not imply that:
- every virtual channel is used;
- the reduced state has a flat spectrum;
- the entropy saturates the bound;
- a state with smaller entropy is accurately approximated at that bond dimension;
- the network can be contracted efficiently;
- the graph matches the locality of the Hamiltonian;
- the tensors found by an optimizer are close to the best tensors at that .
A normalized product state embedded in a large- network may use only one virtual channel. The bond dimension gives a possible rank, not the rank actually used.
Schmidt Tails and Approximation Quality
Section titled “Schmidt Tails and Approximation Quality”For one bipartition, write the Schmidt decomposition
with
Keeping the first terms leaves discarded weight
The unnormalized truncated state
satisfies
After normalization,
the squared fidelity is
This is why the entanglement spectrum, not entropy alone, controls local Schmidt truncation.
Two states can have the same entropy while having very different . An entropy area law therefore motivates low-rank approximation but does not, by itself, certify a bond dimension at a requested global error.
A Family Map
Section titled “A Family Map”| Network | Graph geometry | Natural setting | Cut capacity | Characteristic caution |
|---|---|---|---|---|
| MPS | one-dimensional chain | 1D ground states and dynamics | one bond per chain cut | volume-law growth forces large |
| tree tensor network | hierarchy without loops | clusters and hierarchical correlations | path-dependent, often logarithmic | lattice translations are not built in automatically |
| PEPS | lattice-matched graph | 2D and higher-dimensional states | boundary-edge count | compact representation need not be easy to contract |
| MERA | layered isometries and disentanglers | scale-resolved and critical states | bounded cuts per scale | architecture and optimization are more involved |
These are families, not individual algorithms. A network geometry specifies an ansatz class and contraction problem. DMRG, variational updates, imaginary-time evolution, and environment methods are procedures for selecting or evaluating tensors within such classes.
Matrix Product States
Section titled “Matrix Product States”An open-boundary matrix product state on a chain of sites has coefficients
Equivalently, one may absorb the boundary vectors into the first and last tensors and write
The tensor at site has dimensions
The raw parameter count is therefore
For uniform and , this is
before gauge redundancy and symmetry reduction are taken into account.
Exact construction by sequential singular-value decomposition
Section titled “Exact construction by sequential singular-value decomposition”Every finite-chain state admits an exact MPS. Reshape the coefficient tensor across the first cut:
Its singular-value decomposition gives
Treat
as a new tensor with indices , reshape across the next cut, and repeat. The exact bond dimension at cut can be chosen as the Schmidt rank
For uniform local dimension,
A generic state has full Schmidt rank at every cut and saturates this ceiling, although its Schmidt probabilities need not be equal. Thus exact MPS existence is not an efficiency result.
Entanglement capacity
Section titled “Entanglement capacity”A chain cut severs one MPS bond, so
A finite interval strictly inside an open chain severs two bonds. If its left and right bond dimensions are and , then
Uniform finite- MPS therefore obey a one-dimensional area law by construction. The converse requires additional conditions; an arbitrary state with bounded von Neumann entropy need not have a rapidly decaying Schmidt tail at every cut.
Product states
Section titled “Product states”At bond dimension one, every tensor is a local vector:
The amplitude factorizes,
so
This is the exact benchmark. A code or derivation that cannot reproduce this limit has a contraction, indexing, or normalization error.
A bond-dimension-two GHZ state
Section titled “A bond-dimension-two GHZ state”The -qubit state
has an exact translation-invariant bulk MPS with
and boundary vectors
If the physical string contains both and , the product of diagonal projectors vanishes. The two uniform strings each have amplitude .
Every nontrivial bipartition has
yet the connected correlator satisfies
for arbitrarily separated sites in the symmetric finite-volume state. Low bond dimension and bounded entropy do not imply short-range correlations.
Transfer operators and correlation length
Section titled “Transfer operators and correlation length”For a translation-invariant MPS, define the transfer operator
With an inserted local operator ,
After normalizing the largest transfer eigenvalue to one, a nondegenerate leading eigenvalue and subleading magnitude produce the characteristic length in transfer-step units
A multi-site transfer cell changes the length unit. Subleading Jordan blocks can add polynomial prefactors to exponential decay, and an observable with zero overlap with the slowest transfer mode can decay faster. Finite- injective MPS can therefore impose an artificial finite correlation length near criticality. Degenerate leading eigenvalues or non-injective structure, as in the GHZ example, require separate treatment and can support nondecaying correlations.
The dedicated MPS page develops canonical forms, injectivity, transfer spectra, and matrix-product operators in greater depth.
Tree Tensor Networks
Section titled “Tree Tensor Networks”A tree tensor network organizes physical sites through a loop-free hierarchy. In a binary tree, pairs of local spaces map into coarser effective spaces, then pairs of effective spaces are combined again.
Choose to embed a coarse space into two finer spaces:
The isometry condition is
Thus embeds the coarse state and performs the coarse-graining. The reverse product is a projector onto the retained fine-space subspace, not generally the identity. Its input dimension cannot exceed its output dimension.
Entanglement from tree cuts
Section titled “Entanglement from tree cuts”For a contiguous block of length in a balanced binary tree whose leaf order follows the one-dimensional lattice, a separating cut can cross only a bounded number of bonds at each of
layers. With uniform bond dimension ,
The coefficient depends on the tree architecture and the alignment of the interval with the hierarchy. A different physical region can cut many more branches.
Strengths and limitations
Section titled “Strengths and limitations”Tree networks offer:
- exact contraction without loop environments;
- a natural hierarchy of length scales;
- efficient access to selected reduced states;
- flexible adaptation to clusters, orbitals, or irregular graphs.
They also impose a preferred hierarchy. Ordinary lattice translations and equivalent treatment of every cut are not automatic. A poor tree can place strongly entangled degrees of freedom far apart in the network and force large bond dimensions.
Projected Entangled-Pair States
Section titled “Projected Entangled-Pair States”Projected entangled-pair states generalize the virtual-bond construction to lattices and general graphs. Place a maximally entangled virtual pair on every edge:
At each vertex , apply a local map from all incident virtual spaces to the physical site:
The unnormalized PEPS vector is
The local maps need not preserve norm. Provided this vector is nonzero, divide it by its norm to obtain the physical state. Expanding the normalized virtual pairs gives the opening contraction formula with an overall factor , which can be absorbed into the local tensors. The often-used unnormalized pairs omit that factor.
Boundary-law capacity
Section titled “Boundary-law capacity”If a spatial region cuts virtual edges of uniform dimension , then
and
For a regular region on a local -dimensional lattice,
Finite- PEPS therefore satisfy an area-law upper bound by construction.
Square-lattice parameter count
Section titled “Square-lattice parameter count”A bulk square-lattice tensor has one physical and four virtual legs:
For site-dependent tensors with uniform dimensions, the raw count scales as
Translation invariance can reduce the number of distinct tensors, but it does not make their contraction trivial.
Compact representation is not easy contraction
Section titled “Compact representation is not easy contraction”The norm
is a double-layer network. Each ket virtual leg pairs with a bra virtual leg, giving effective dimension
Contracting one row of a two-dimensional network into the next generally grows an intermediate boundary object. Exact contraction cost can therefore increase exponentially with the lattice width even when is fixed.
Worst-case exact PEPS contraction is #P-complete under the standard complexity-theoretic formulation. This theorem does not say that every physically structured PEPS instance is equally hard. It does say that finite bond dimension and an area law do not furnish a universal efficient classical contraction algorithm.
Practical PEPS methods use approximate environments, boundary MPS, corner constructions, tensor renormalization, Monte Carlo, or problem-specific structure. Their implementation and error control belong to computational-method pages.
Correlations and phases
Section titled “Correlations and phases”Finite- PEPS can describe much more than short-range trivial states. The family includes examples with:
- symmetry breaking;
- algebraic correlations;
- topological order;
- symmetry-protected structure;
- exact parent Hamiltonians;
- nontrivial boundary theories and entanglement spectra.
In particular, finite PEPS bond dimension does not force a finite physical correlation length. This contrasts with the generic injective finite- MPS transfer-matrix picture and is one reason one-dimensional intuition should not be imported uncritically into two dimensions.
Multiscale Entanglement Renormalization Ansatz
Section titled “Multiscale Entanglement Renormalization Ansatz”MERA augments a hierarchy of isometries with disentanglers that act across block boundaries before coarse-graining. In a common convention, a disentangler is unitary,
while the embedding tensor uses the same coarse-to-fine convention as the tree network,
These identities allow tensors outside the causal cone of a local observable to cancel against their adjoints.
Bounded causal cones
Section titled “Bounded causal cones”To compute a local expectation value, follow the operator upward through the network. In a properly designed MERA, its support remains bounded in width as the number of layers grows. A system of linear size has
layers, so local observables can be evaluated without contracting the entire network at once.
The precise cost depends on the branching structure, dimension, bond dimension, and update scheme. “Bounded causal cone” is a structural statement, not a universal cost formula independent of architecture.
Entanglement by scale counting
Section titled “Entanglement by scale counting”For a one-dimensional interval of length , a MERA cut can cross only a bounded number of bonds per layer over
relevant layers. Hence
This architecture is naturally compatible with the logarithmic interval entropy of many one-dimensional critical ground states. A scale-invariant MERA repeats tensors across layers and can encode algebraic correlations governed by scaling operators of an ascending map.
What MERA does not establish
Section titled “What MERA does not establish”A MERA fit does not by itself prove:
- exact conformal invariance;
- a unique continuum field theory;
- a holographic dual;
- that all critical exponents have converged;
- that finite-size and finite-bond effects are negligible.
The architecture organizes information by scale. Physical claims still require symmetry, correlation, spectrum, and convergence checks.
Area Laws and Compression
Section titled “Area Laws and Compression”The safest implication is from a network to an entanglement-capacity bound:
The reverse implication is more delicate:
Why one-dimensional gapped systems are favorable
Section titled “Why one-dimensional gapped systems are favorable”For one-dimensional bounded finite-range spin Hamiltonians with fixed local dimension, a unique ground state, and a spectral gap uniform in system size, the ground state obeys an entanglement area law. Stronger locality and spectral information then support controlled MPS approximation results.
The assumptions matter:
- one spatial dimension;
- finite local Hilbert-space dimension;
- bounded finite-range interactions; extensions to decaying interactions have separate hypotheses;
- a gap that does not close with system size;
- a unique ground state in the basic theorem; degeneracy extensions require additional conditions;
- an explicit norm, observable, or energy accuracy target.
An isolated entropy bound is not the whole theorem package.
Critical chains
Section titled “Critical chains”At a one-dimensional conformal critical point, an interval often has leading entropy
An interior interval crosses two MPS bonds. With both dimensions bounded by , its exact capacity condition is
For a region bounded by one separating bond, the condition is instead ; the critical entropy coefficient must then match that one-cut geometry. Neither inequality by itself guarantees a good approximation. Finite- injective MPS impose a finite transfer correlation length, so critical fits should vary both system size and bond dimension.
MERA distributes entanglement over scales and can encode logarithmic growth at fixed local bond dimension, though its tensors and optimization remain nontrivial.
Volume-law states
Section titled “Volume-law states”If a one-cut chain bipartition has
then an exact MPS requires
This exponential demand appears in generic highly excited states and during sufficiently long real-time evolution after a global quench. It is an entanglement barrier for chain-ordered MPS, not a claim that every observable becomes immediately inaccessible by every method.
Network topology matters
Section titled “Network topology matters”Bond dimension cannot be compared without the graph. A bond of dimension in an MPS, a PEPS, and a MERA contributes to different cuts and contraction costs. A network with nonlocal edges can represent some volume-law partitions at modest local by allowing many edges to cross the physical cut, but the graph may then lose locality or become difficult to contract.
The meaningful comparison reports:
- network family and topology;
- physical-site ordering;
- every relevant bond dimension;
- parameter count after symmetry constraints when useful;
- contraction or environment approximation;
- measured error at matched computational resources.
Symmetry in Virtual Spaces
Section titled “Symmetry in Virtual Spaces”An exact global symmetry can be built into local tensors rather than recovered approximately after optimization. For an Abelian charge, tensor entries vanish unless the oriented charges satisfy a local selection rule of the form
where records the chosen orientation and is the tensor’s net charge.
Block structure
Section titled “Block structure”Charge conservation decomposes virtual spaces into sectors:
Here carries charge and is its degeneracy. Contractions become block sparse, forbidden sectors are absent, and the state remains in the intended global symmetry sector up to numerical precision.
Virtual symmetry carries physical information
Section titled “Virtual symmetry carries physical information”Virtual symmetry is not only a speed device. In one-dimensional MPS, projective actions on virtual bonds help distinguish symmetry-protected phases. In PEPS, virtual symmetries can encode topological sectors and anyonic structure.
These statements require the relevant injectivity, symmetry, and phase assumptions. A visually symmetric tensor diagram is not by itself a phase classification.
Fermionic and Constrained Networks
Section titled “Fermionic and Constrained Networks”Tensor diagrams for ordinary complex vector spaces allow line crossings to be rearranged without a sign. Fermionic Fock spaces require parity-aware conventions. Valid approaches include:
- Jordan–Wigner mappings with explicit strings;
- graded tensor products;
- fermionic swap gates;
- parity-symmetric local tensors;
- ordering conventions retained throughout every contraction.
Ignoring these choices can change signs and therefore the physical state.
Gauge theories and constrained Hilbert spaces similarly require invariant local tensors, projectors, or symmetry-adapted virtual spaces. The virtual coordinate gauge freedom discussed earlier does not enforce Gauss’s law automatically.
Operators and Mixed States
Section titled “Operators and Mixed States”Tensor-network structure is useful beyond pure state vectors.
Matrix product operators
Section titled “Matrix product operators”An operator on a chain can be represented as
with coefficients factorized as
This is a matrix product operator, or MPO. Local and finite-range Hamiltonians often admit MPO representations with bond dimensions that remain modest as grows, though the exact value depends on interaction range, symmetries, and compression choices.
Applying an MPO of bond dimension to an MPS of bond dimension can produce an intermediate state with bond dimension as large as
on each corresponding bond before compression. Repeated application without truncation can therefore increase cost rapidly.
Density operators
Section titled “Density operators”A mixed state may be represented directly as an MPO,
Hermiticity and unit trace can be imposed or repaired, but positivity is more delicate. Truncating a generic operator-network expansion can create small negative eigenvalues even when the target density operator is positive.
A purification avoids this problem structurally. Introduce ancillas and represent
as a tensor-network state, then define
Positivity is automatic, although the ancilla increases local dimensions and purification entanglement is not unique.
Thermal states
Section titled “Thermal states”Starting from a purification of the infinite-temperature identity, imaginary-time evolution formally gives
Tracing out the ancilla yields
In practice, imaginary-time discretization, operator approximation, truncation, and normalization all require convergence checks. Thermal tensor-network algorithms belong to computational-method pages; the representational point is that mixed-state complexity can be shifted into a purified state or operator bond dimension.
Operator entanglement
Section titled “Operator entanglement”An operator can be treated as a vector in Hilbert–Schmidt space by grouping its input and output indices. Its Schmidt spectrum across a spatial cut controls MPO compression in much the same way that state Schmidt data control MPS compression.
Operator entanglement is not ordinary state entanglement unless the operator has been mapped to a normalized state under a declared convention. It becomes especially important in time evolution, quantum channels, and scrambling, where an initially local operator can spread and require rapidly growing MPO bond dimension. Operator entanglement and scrambling explains that doubled-space construction and its diagnostic limits.
Contraction Geometry
Section titled “Contraction Geometry”The value of a tensor network is obtained only after a contraction order is chosen. Different orders can create intermediate tensors with very different ranks and sizes.
Chains
Section titled “Chains”An open MPS norm can be contracted from left to right. If the MPS bond dimension is , the boundary object remains a matrix rather than acquiring one index for every physical site. Local expectation values and correlation functions are therefore polynomial in and under standard assumptions.
The exact exponent of depends on canonical gauge, observable structure, boundary conditions, and implementation. A quoted cost such as is meaningful only with those conventions stated.
Loops and width
Section titled “Loops and width”In a PEPS, contracting part of the lattice leaves an effective tensor along the uncontracted boundary. Its dimension grows with the number of exposed virtual bonds. On a strip of width , exact intermediate size is generically exponential in .
This is a graph-width phenomenon. A sparse-looking network can still have large contraction width, while a network with many tensors can be easy if its graph admits a favorable elimination order.
Isometric cancellation
Section titled “Isometric cancellation”Tree networks and MERA exploit isometric identities. Tensors outside a causal cone cancel with their adjoints in a norm or expectation-value network. This reduces the number of tensors that must be evaluated, but only when the tensors satisfy the required isometric constraints and the observable is placed in the declared geometry.
Approximate environments
Section titled “Approximate environments”Looped networks are often contracted approximately by replacing an exact boundary object with a compressed one. This introduces an environment dimension or related cutoff in addition to the state bond dimension.
Convergence in alone is then insufficient. One must also vary the environment cutoff, contraction tolerance, and contraction scheme.
Representation, Contraction, and Optimization
Section titled “Representation, Contraction, and Optimization”Three logically distinct questions are often compressed into the phrase “tensor-network method.”
Representation
Section titled “Representation”Does the chosen family contain a state close to the target at accessible bond dimension?
Define the best approximation error in a family by
This is a property of the state, basis, ordering, graph, and error metric.
Contraction
Section titled “Contraction”Can norms, energies, gradients, and observables be evaluated at controlled cost and error for a given tensor set?
An approximate contraction can bias the objective and its gradient. An exactly evaluated energy expectation of a nonzero trial state gives the variational upper bound after division by its norm. An approximate contraction can violate that numerical bound; a rigorous error estimate is needed to recover a guaranteed upper bound.
Optimization
Section titled “Optimization”Can an algorithm locate a good tensor set inside ?
Let
and let be the exactly evaluated energy of the normalized state returned by a calculation. The optimization gap is
Usually is unknown, so restarts, different update schedules, symmetry sectors, and comparison with benchmarks are needed to detect poor minima.
An expressive and contractible family can still be hard to optimize. Conversely, an optimizer can converge perfectly inside an ansatz that excludes the target physics.
Distinguishing numerical errors
Section titled “Distinguishing numerical errors”Different errors respond to different controls:
| Error source | Typical control | Failure if omitted |
|---|---|---|
| finite size and boundaries | increase , compare geometries | edge or crossover effect misread as bulk physics |
| local basis or onsite cutoff | enlarge | discarded onsite states bias observables |
| finite bond dimension | increase or | artificial entropy and correlation-length saturation |
| environment contraction | increase boundary or environment dimension | biased PEPS norm, energy, or gradient |
| optimization | restarts and residual checks | metastable tensor set |
| time or imaginary-time step | decrease step size or change integrator | discretization error mistaken for physics |
| symmetry sector | enforce and verify charges | wrong state or broken exact constraint |
| observable extraction | compare independent contractions | normalization or insertion error |
Observable error from state error
Section titled “Observable error from state error”For normalized states and and a bounded observable ,
This converts a global norm certificate into a worst-case observable bound. The reverse does not hold: agreement for a short list of observables need not imply small global state error.
Energy variance
Section titled “Energy variance”For a normalized trial state,
An exact eigenstate has . A small variance is useful evidence of eigenstate quality, but translating it into fidelity requires spectral information. Near-degenerate levels can support a low-variance superposition that is not close to one selected eigenvector.
Symmetry residuals
Section titled “Symmetry residuals”If the target state should have charge under , inspect
For a symmetry-adapted tensor network this should vanish up to numerical precision. If symmetry is not imposed, the residual distinguishes physical symmetry breaking in a controlled limit from numerical drift only when system size, boundary fields, and convergence are also analyzed.
Worked examples of bond dimension
Section titled “Worked examples of bond dimension”Bell-pair dimer chain
Section titled “Bell-pair dimer chain”Consider an even chain in the state
A cut after site crosses one Bell pair when is odd and lies between dimers when is even. Therefore
and
This example shows why nonuniform bond dimensions can be physically meaningful and why the location of a cut must be stated.
Square PEPS region
Section titled “Square PEPS region”Take an square region in the bulk of an infinite square-lattice PEPS with uniform bond dimension . Exactly nearest-neighbor virtual edges leave each of four sides, so
The cut bound gives
This is a perimeter law. It is not an entropy prediction: local maps can reduce the rank, corners and boundary conventions affect subleading structure, and the actual spectrum can be far from flat.
Ordering a nonlocal pairing pattern
Section titled “Ordering a nonlocal pairing pattern”Suppose a state is a product of Bell pairs between orbitals
Ordering the chain as
keeps at most one pair crossing an internal cut. Ordering it as
makes the central cut cross all pairs. The exact Schmidt rank changes from at most at each local dimer cut to
at the central cut.
The physical state is identical. The chain ordering determines whether the MPS graph aligns with its correlation structure.
A volume-law lower bound
Section titled “A volume-law lower bound”If an MPS target has entropy
at the middle cut, then
and hence
No optimization trick can evade this exact representational capacity bound for that chain ordering.
Choosing a representation
Section titled “Choosing a representation”Match physical and virtual geometry
Section titled “Match physical and virtual geometry”Ask which degrees of freedom interact locally and which are strongly entangled. A one-dimensional local Hamiltonian suggests an MPS chain. A two-dimensional lattice suggests PEPS. Hierarchical or scale-invariant structure can motivate a tree network or MERA. Long-range orbital problems may require an optimized ordering or a non-chain graph.
The Hamiltonian graph alone is not decisive. Frustration, fermionic signs, topological structure, dynamics, and the target observable can favor a different representation.
Name the target state class
Section titled “Name the target state class”Ground states, low excitations, thermal states, real-time states, steady states, and operators have different complexity. A network successful for a gapped ground state may fail rapidly after a quench because entanglement grows even though the Hamiltonian is unchanged.
Estimate the relevant cut structure
Section titled “Estimate the relevant cut structure”Use exact limits, small-system diagonalization, known entropy laws, or preliminary calculations to estimate:
- which cuts dominate;
- whether the Schmidt tail decays rapidly;
- whether critical logarithms are expected;
- whether a volume law is unavoidable;
- whether constraints split the spectrum into sectors.
Decide what must be contractible
Section titled “Decide what must be contractible”A compact amplitude representation is insufficient if the required observable cannot be evaluated. Before choosing the ansatz, list the operations needed:
- norm and energy;
- local and long-range correlators;
- reduced density matrices or entropies;
- gradients;
- time evolution;
- sampling;
- overlap with reference states;
- response or spectral functions.
Preserve exact structure
Section titled “Preserve exact structure”Build in known particle number, spin, lattice, parity, or gauge constraints when practical. Use fermionic conventions from the start. Check exactly solvable limits at the smallest bond dimension that should represent them.
Vary independent numerical controls
Section titled “Vary independent numerical controls”Test the relevant controls independently:
One large calculation at one parameter set is not a convergence study.
Exercises
Section titled “Exercises”1. Prove the network cut bound
Section titled “1. Prove the network cut bound”A tensor network is split into physical regions and by cutting virtual edges with dimensions . Prove that
and derive the corresponding von Neumann entropy bound.
Solution
Expose every cut index. The tensor contraction on side produces a vector
and the contraction on side produces
Thus
This is a sum of at most
product vectors. Orthogonalizing the spans on the two sides cannot increase the number of terms, so the Schmidt rank is at most .
The reduced state therefore has rank at most . Entropy is maximized by the uniform distribution on a support of that size, giving
The vectors generated by the two subnetworks need not be orthogonal, so the bound need not be saturated.
2. Compare MPS and generic parameter counts
Section titled “2. Compare MPS and generic parameter counts”An open chain has qubits and an MPS with uniform internal bond dimension . Use first and last tensor sizes and interior sizes to compare the raw MPS parameter count with the number of coefficients in a generic state vector. What does this comparison fail to prove?
Solution
Here . The two boundary tensors contribute
The interior tensors contribute
The raw total is
A generic state vector has
complex coefficients before normalization and phase redundancy.
The MPS parameter count is much smaller, but this does not prove that an arbitrary 20-qubit state is accurately represented at . It also ignores MPS gauge redundancy, contraction cost, and optimization error. Near the chain ends, several of these virtual dimensions exceed the largest possible Schmidt rank, so the uniform- count deliberately includes redundant parameters. The target state’s Schmidt spectrum and approximation error determine whether the ansatz is useful.
3. Verify the GHZ MPS
Section titled “3. Verify the GHZ MPS”Using
with the boundary vectors given in the main text, show that only the all-zero and all-one strings have nonzero amplitude. Explain why is minimal across every nontrivial cut.
Solution
The matrices are orthogonal projectors:
Any bit string containing both symbols therefore gives a zero matrix product. For the all-zero string,
so
The same calculation gives for the all-one string. Hence the represented state is .
Across every nontrivial cut,
There are two nonzero Schmidt coefficients. The Schmidt rank is two, so an exact MPS needs
at that cut. The displayed representation reaches the minimum.
4. Count a rectangular PEPS boundary
Section titled “4. Count a rectangular PEPS boundary”For an rectangular region in the bulk of a square-lattice PEPS, count the nearest-neighbor virtual edges crossing its boundary and derive the uniform- entropy bound. How does the answer change if the region touches an open physical boundary?
Solution
The top and bottom sides each cut edges, while the left and right sides each cut edges. Thus
The cut-capacity bound is
If the region touches an open physical boundary, no virtual edge crosses the side lying on that boundary. The corresponding side contribution is removed. This is why open, periodic, and infinite geometries must not be compared with the same unqualified boundary count.
5. Test virtual gauge invariance
Section titled “5. Test virtual gauge invariance”Two neighboring tensors contribute a factor on their shared virtual space. Show that inserting and leaves the state unchanged. Why must be invertible for this statement? Does the transformation preserve the norms of and separately?
Solution
Associativity gives
The physical contraction is unchanged. If is singular, an inverse on the full virtual space does not exist, and the cancellation cannot be asserted. One can sometimes reduce a bond by restricting to the actually occupied support, but that is a separate factorization or compression step.
The individual tensor norms need not be preserved. Taking
rescales by and by . Their contraction is unchanged while their separate norms vary. Raw tensor norms are therefore gauge dependent.
6. Control a geometric Schmidt tail
Section titled “6. Control a geometric Schmidt tail”Suppose the Schmidt probabilities are
Find the discarded weight after keeping values, the normalized truncated-state fidelity, and the smallest guaranteeing discarded weight at most , where .
Solution
The discarded tail is a geometric series:
The normalized truncated state has squared fidelity
The condition gives
Because , division reverses the inequality:
The smallest integer choice is
7. Show how ordering changes MPS cost
Section titled “7. Show how ordering changes MPS cost”For independent Bell pairs , compare the maximum Schmidt rank in the interleaved ordering
with the separated ordering
Solution
In the interleaved ordering, a cut can cross at most one pair. Between complete pairs the Schmidt rank is one; inside a pair it is two. Therefore
In the separated ordering, the central cut places every on one side and every on the other. The state is a tensor product of rank-two Schmidt decompositions, so ranks multiply:
The ordering changes the exact MPS cost exponentially without changing the physical state. It changes which physical correlations cross each virtual bond.
8. Assess three tensor-network claims
Section titled “8. Assess three tensor-network claims”Assess the following statements and replace each overclaim with a defensible version.
- Every area-law state is efficiently represented and contracted by a small tensor network.
- A finite- PEPS has finite correlation length.
- A finite- entropy plateau proves that the underlying system is gapped.
Solution
Claim 1 is too strong. A finite-bond MPS or PEPS obeys an area-law capacity bound, and broad one-dimensional gapped ground-state classes admit controlled MPS approximations under additional assumptions. A scalar area law alone does not certify a rapidly decaying Schmidt tail, a compact network in every geometry, easy contraction, or successful optimization.
Claim 2 is false in general. Finite- PEPS can exhibit algebraic correlations. A defensible statement is that generic injective finite- MPS have correlations governed by a finite-dimensional transfer operator and often exhibit exponential decay when the leading eigenvalue is nondegenerate and separated in magnitude.
Claim 3 confuses numerical and physical scales. A finite- MPS imposes limited entanglement and can create an artificial correlation length. A physical gap claim requires convergence as and increase, together with direct spectral or correlation evidence and controlled boundary conditions.
References
Section titled “References”- M. C. Bañuls, “Tensor Network Algorithms: A Route Map”, Annual Review of Condensed Matter Physics 14, 173–191 (2023).
- J. C. Bridgeman and C. T. Chubb, “Hand-Waving and Interpretive Dance: An Introductory Course on Tensor Networks”, Journal of Physics A 50, 223001 (2017).
- J. I. Cirac, D. Pérez-García, N. Schuch, and F. Verstraete, “Matrix Product States and Projected Entangled Pair States: Concepts, Symmetries, Theorems”, Reviews of Modern Physics 93, 045003 (2021).
- G. Evenbly and G. Vidal, “Algorithms for Entanglement Renormalization”, Physical Review B 79, 144108 (2009).
- M. Fannes, B. Nachtergaele, and R. F. Werner, “Finitely Correlated States on Quantum Spin Chains”, Communications in Mathematical Physics 144, 443–490 (1992).
- J. Haegeman, C. Lubich, I. Oseledets, B. Vandereycken, and F. Verstraete, “Unifying Time Evolution and Optimization with Matrix Product States”, Physical Review B 94, 165116 (2016).
- M. B. Hastings, “An Area Law for One-Dimensional Quantum Systems”, Journal of Statistical Mechanics P08024 (2007).
- R. Orús, “A Practical Introduction to Tensor Networks: Matrix Product States and Projected Entangled Pair States”, Annals of Physics 349, 117–158 (2014).
- R. Orús, “Tensor Networks for Complex Quantum Systems”, Nature Reviews Physics 1, 538–550 (2019).
- S. Östlund and S. Rommer, “Thermodynamic Limit of Density Matrix Renormalization”, Physical Review Letters 75, 3537–3540 (1995).
- F. Pollmann, S. Mukerjee, A. M. Turner, and J. E. Moore, “Theory of Finite-Entanglement Scaling at One-Dimensional Quantum Critical Points”, Physical Review Letters 102, 255701 (2009).
- U. Schollwöck, “The Density-Matrix Renormalization Group in the Age of Matrix Product States”, Annals of Physics 326, 96–192 (2011).
- N. Schuch, M. M. Wolf, F. Verstraete, and J. I. Cirac, “Computational Complexity of Projected Entangled Pair States”, Physical Review Letters 98, 140506 (2007).
- L. Tagliacozzo, T. R. de Oliveira, S. Iblisdir, and J. I. Latorre, “Scaling of Entanglement Support for Matrix Product States”, Physical Review B 78, 024410 (2008).
- F. Verstraete and J. I. Cirac, “Matrix Product States Represent Ground States Faithfully”, Physical Review B 73, 094423 (2006).
- F. Verstraete, M. M. Wolf, D. Pérez-García, and J. I. Cirac, “Criticality, the Area Law, and the Computational Power of Projected Entangled Pair States”, Physical Review Letters 96, 220601 (2006).
- F. Verstraete, V. Murg, and J. I. Cirac, “Matrix Product States, Projected Entangled Pair States, and Variational Renormalization Group Methods for Quantum Spin Systems”, Advances in Physics 57, 143–224 (2008).
- G. Vidal, “Efficient Classical Simulation of Slightly Entangled Quantum Computations”, Physical Review Letters 91, 147902 (2003).
- G. Vidal, “Entanglement Renormalization”, Physical Review Letters 99, 220405 (2007).
- G. Vidal, “Class of Quantum Many-Body States That Can Be Efficiently Simulated”, Physical Review Letters 101, 110501 (2008).
- S. R. White, “Density Matrix Formulation for Quantum Renormalization Groups”, Physical Review Letters 69, 2863–2866 (1992).
Cross-Links
Section titled “Cross-Links”- Many-Body Entanglement Overview — subsystem choices, measures, scaling families, and interpretation workflow.
- Entanglement Entropy in Many-Body Systems — spatial entropy and the bond-dimension consequence of Schmidt rank.
- Area Laws — boundary-law theorems, tensor cut counting, and converse caveats.
- Volume Laws — state classes that force extensive subsystem entropy.
- Entanglement Spectrum — Schmidt tails, truncation diagnostics, symmetry sectors, and boundary structure.
- Mutual Information in Many-Body Systems — total regional correlation in pure, mixed, and thermal states.
- Variational Many-Body States — comparison with determinant, Jastrow, paired, projected, and neural state families.
- Scaling of Hilbert Space — the exponential coefficient count that structured representations address.
- Computational Many-Body Overview — method selection, cross-method validation, error classes, and thermodynamic claim control.
- Tensor Networks: Computational Guide — network selection, convergence grids, stopping criteria, and reporting standards.
- DMRG Preview — effective Hamiltonians, one-site and two-site sweeps, local truncation, and ground-state checks.
- Tensor Networks — numerical algorithms and convergence beyond the physical representation.
- Boundary Conditions on Lattices — open, periodic, and twisted geometries for finite calculations.
- Connected Correlation Functions — transfer-matrix decay, long-range order, and finite-bond cautions.
- Renormalization Group Preview — physical coarse-graining and fixed-point language.
- Topological Order Preview — long-range entanglement and virtual symmetry cautions.
- Symmetry-Protected Structure Preview — projective virtual actions and protected phases.
- Tensor Products of Hilbert Spaces — the underlying subsystem factorization.
- Schmidt Decomposition — bipartite ranks and optimal local truncation.
- Entanglement Sharing — cut resources and multipartite distribution.
- Time-Dependent Variational Principle — projected evolution on nonlinear tensor manifolds.
- Computational Quantum Mechanics Roadmap — numerical linear algebra, validation, and reproducible workflows.
- Package Index — documented tensor-network software entry points.