

Verification of Quantum Simulation
Verification tests whether a quantum simulator answers a specified question about a target model with the required accuracy. A full classical prediction may be unavailable precisely where the simulation is most useful. The task is then to combine checks with different blind spots, and to distinguish a quantitative certificate from agreement over the cases actually tested.
Required background. Quantum simulation defines the target model and output. Helpful background. Device characterization explains inference of physical parameters; variance and covariance supports the uncertainty comparisons below.
Observable accuracy and what a test establishes
Section titled “Observable accuracy and what a test establishes”For an observable estimate with target value , one useful goal is
Specify the experiment repeated in this probability statement: independently prepared shots, entire calibration runs, disorder realizations, or another sampling unit. A Bayesian credible interval instead refers to a posterior under a stated model. Neither automatically accounts for an omitted physical interaction or an incorrectly calibrated measurement.
Three questions should be separated. Verification compares the realized process with its declared target. Model validation asks whether that target describes a material or physical system of interest. Certification adds a quantitative guarantee under explicit assumptions; benchmarking compares quality or cost over a chosen family. These terms have varying usage, but the physical distinctions matter: solving the wrong material model accurately is not a successful prediction of that material.
A test applies to particular sizes, times, initial states, parameters, and observables. Agreement at short times does not certify late dynamics, nor does a local observable determine a global state. Extending the tested range needs a physical argument, especially across a resonance, phase boundary, heating threshold, or change in approximation quality. Hauke and colleagues, Eisert and colleagues, and Kliesch–Roth discuss complementary verification methods and their assumptions.
Typical assumptions concern the generator’s locality, the measurement model, independent preparations, a retained Hilbert space, and stationarity or memory. A fit restricted to nearest-neighbor interactions cannot exclude longer-range terms merely because its residual is small. Compare alternatives or choose a measurement that distinguishes them.
Method Selector
Section titled “Method Selector”| Method | Best use | What it can establish | Main blind spot |
|---|---|---|---|
| exact small-instance comparison | finite states or dynamics | end-to-end agreement in overlap regime | size- or time-dependent errors |
| solvable limits | parameter endpoints and special sectors | correct conventions and limiting behavior | off-limit interactions |
| short-time expansion | local dynamics and generator moments | early-time derivatives | accumulated long-time error |
| conserved quantities and constraints | symmetries, gauge laws, continuity | necessary structural consistency | symmetry-preserving errors |
| convergence and sensitivity | digital step, cutoff, ramp, size, analysis | stability under a chosen refinement | common bias across refinements |
| Hamiltonian or channel learning | structured implemented dynamics | parameters and held-out predictions | ansatz misspecification |
| targeted fidelity or witness | a state property | property-specific certificate | other state features |
| tomography or shadows | state or selected observables | reconstruction or many estimates | scaling and measurement trust |
| benchmark-model family | complete workflow | coverage of chosen failure modes | unrepresented target regimes |
| cross-platform comparison | independent implementations | consistency and discrepancy localization | shared target or analysis error |
| blind held-out prediction | transfer beyond fitting data | predictive model adequacy | limited holdout coverage |
Combine methods with different blind spots. Ten tests of the same conserved quantity are not ten independent lines of evidence.
Exact Classical Comparison
Section titled “Exact Classical Comparison”Direct comparison remains the cleanest check where it is feasible. For a reference prediction and experimental estimate , define a discrepancy
The uncertainty of includes both sides,
The covariance formula concerns random uncertainties under the adopted model. A deterministic truncation bound or an unknown systematic bias is not automatically a variance term. Classical reference uncertainty may include finite precision, truncation, solver convergence, Monte Carlo sampling, finite bond dimension, or model parameter uncertainty. Calling a numerical answer exact does not make the implementation or input data exact.
Use the strongest applicable method
Section titled “Use the strongest applicable method”Exact diagonalization is only one reference. Depending on the instance, useful methods include:
- free-particle and stabilizer reductions;
- tensor networks at limited entanglement or time;
- sign-problem-free Monte Carlo;
- Krylov and sparse-matrix propagation;
- perturbative, semiclassical, or mean-field limits with controlled errors;
- symmetry decomposition and reduced sectors;
- interval, variational, or rigorous upper and lower bounds.
The relevant comparison is with the best method for the same input, observable, and tolerance. A classical method that cannot reconstruct the full state may still compute the local observable being claimed.
Compare distributions, not only means
Section titled “Compare distributions, not only means”Agreement of one expectation value can hide state error. For example, have identical computational-basis probabilities but are orthogonal. Both give , whereas .
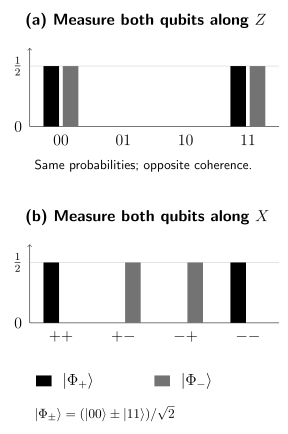
Each bar is an outcome probability. The upper panel cannot distinguish from ; rotating both measurement bases to reveals the sign of their coherence. Matching a distribution in one basis is insufficient to certify the state.
When feasible, compare a vector of observables, marginal distributions, time correlations, or raw bitstring statistics. A quadratic discrepancy with covariance is
Its interpretation requires a justified covariance model and degrees of freedom. If parameters were fitted to the same data, the naive reference distribution for is generally wrong.
Small size does not automatically transfer
Section titled “Small size does not automatically transfer”Suppose sizes agree. Larger systems may activate crosstalk, inhomogeneity, long-range tails, heating, calibration congestion, or error growth with volume. Transfer to requires tests that are sensitive to those mechanisms, not merely more precise agreement below .
Limiting Cases and Tractable Deformations
Section titled “Limiting Cases and Tractable Deformations”A target family often contains points with known solutions. Good limits isolate different terms:
- zero interaction;
- zero hopping or decoupled sites;
- one-particle and two-particle sectors;
- high-field, weak-coupling, or atomic limits;
- integrable lines;
- infinite-temperature or short-time limits;
- vanishing drive or dissipation;
- small graph motifs with exact spectra.
The limit should be reached through the same control and measurement pipeline as the hard experiment. Replacing the apparatus with a separate easy implementation may test analysis code without testing the relevant controls.
Metamorphic relations
Section titled “Metamorphic relations”Some tests need no full reference answer. A transformation of the input may imply a transformation of the output. Examples include:
- permuting equivalent sites;
- reversing a field and applying a known basis transformation;
- changing units or rotating frames;
- reversing time for a reversible ideal model;
- duplicating disconnected components;
- applying a gauge transformation while preserving gauge-invariant outputs.
These metamorphic tests can expose sign, indexing, frame, and compilation errors. They verify the relation, not either output absolutely.
Short-Time Expansions
Section titled “Short-Time Expansions”For a closed target and observable ,
For a local observable and a finite-range local Hamiltonian, the first few nested commutators involve only a growing neighborhood of its support. They can be calculated even when long-time dynamics is hard. Measuring several initial states and observables turns these derivatives into tests of generator terms and sign conventions.
Short-time agreement has a strict scope. Coherent errors may accumulate, dissipation may dominate later, and two generators with matching first few moments can diverge at longer times. The expansion is a generator diagnostic, not a long-time certificate.
Conserved Quantities, Constraints, and Sum Rules
Section titled “Conserved Quantities, Constraints, and Sum Rules”If , then ideal closed evolution preserves
Violations can reveal leakage, symmetry-breaking controls, loss, drift, or incorrect reconstruction. The same logic applies to:
- particle number, parity, energy, and total spin;
- Gauss-law constraints in gauge simulations;
- local continuity equations;
- normalization and positivity;
- spectral and response-function sum rules;
- causal or locality bounds;
- thermodynamic identities.
For local density and current , a continuity residual is
In a closed number-conserving system this residual vanishes. With a local source , the continuity equation instead gives ; subtract that source before testing for a vanishing residual. Testing local residuals is often more diagnostic than testing only total number, because spatially correlated errors can conserve the total.
Necessary is not sufficient
Section titled “Necessary is not sufficient”A simulator evolving under the wrong Hamiltonian can preserve the same symmetry. Depolarization within a fixed sector can pass a charge check. A readout correction can enforce normalization while biasing correlations. Structural identities can rule out faults, but passing them rarely identifies the full state or generator. For a constraint , testing only is especially weak: positive and negative violations can cancel. Measure a positive penalty such as or the physical-sector projector to bound leakage.
Convergence and Sensitivity Tests
Section titled “Convergence and Sensitivity Tests”Verification should vary controls that change a known approximation while holding the target fixed.
Digital refinements
Section titled “Digital refinements”Vary product-formula step size, compilation, synthesis precision, logical cutoff, ancilla precision, or mitigation strength. A target estimator may have an expansion
Hardware error can grow as decreases because the circuit becomes deeper. Monotonic convergence is therefore not guaranteed; the model must include both trends.
Analog refinements
Section titled “Analog refinements”Vary ramp speed, drive frequency, interaction cutoff, temperature, disorder realization, lattice spacing, boundary, and evolution window. Since analog hardware does not have a universal step size, refinement must be tied to the specific effective-model approximation. Changing temperature, boundaries, or size changes the target itself unless a limiting family has been specified; such scans are sensitivity or scaling tests, not repeated calculations of an unchanged finite-instance observable.
Numerical and analysis refinements
Section titled “Numerical and analysis refinements”Vary Fock cutoff, bond dimension, time step, fit window, regularization, response model, and bootstrap unit. Stability under analysis choices is evidence against one class of bias, but several methods can share the same incorrect input model.
Negative controls
Section titled “Negative controls”A verifier should fail when a known fault is injected. Deliberately perturb a coupling, violate a symmetry, add leakage, scramble a phase, or distort a readout model. If the chosen metrics do not respond at the scientifically relevant fault scale, they cannot support the main claim.
Learning the Implemented Generator
Section titled “Learning the Implemented Generator”For a structured Hamiltonian ansatz
short-time slopes obey
For several states and observables this becomes a linear inverse problem
The singular values of determine which parameter combinations are identifiable. A small singular value amplifies statistical and calibration error. More data do not fix an unidentifiable design if the new rows of carry the same information. An identity term always gives a zero column in this commutator design: ordinary closed-system state evolution cannot identify an additive energy constant. Nonidentity terms can also be invisible to a poorly chosen set of preparations and observables.
Model testing, not only parameter fitting
Section titled “Model testing, not only parameter fitting”Generator learning is conditional on the basis . A mature workflow compares nested or alternative ansatzes, inspects structured residuals, and tests predictions on states, times, and observables not used in fitting. It also propagates the posterior or confidence region for to the target observable.
Open-system inference replaces by a channel or Liouvillian ansatz. The physicality, memory, and time dependence of that ansatz then become additional tests. A fitted Markovian generator cannot rule out non-Markovian dynamics outside the fitted time resolution.
Targeted State and Property Verification
Section titled “Targeted State and Property Verification”Full tomography of generic qubits requires exponentially many parameters. Simulation verification should therefore target the property needed for the claim whenever possible.
Direct fidelity estimation
Section titled “Direct fidelity estimation”If an efficiently described pure target is available, its fidelity with an experimental state is
Importance-sampled Pauli measurements can estimate this quantity without full tomography for suitable targets, as in Flammia–Liu. Efficiently writing down a state does not alone ensure efficient sampling of its Pauli distribution or bounded estimator variance; stabilizer targets are a particularly favorable case. The protocol certifies closeness to the specified state, not correctness of an unknown state in a classically hard regime where the target description itself is unavailable.
Witnesses and local marginals
Section titled “Witnesses and local marginals”Entanglement witnesses, stabilizers, parent-Hamiltonian energies, and local reduced states can certify selected structure. Their power depends on a gap, uniqueness, locality, or another model property. A witness that detects entanglement does not identify the phase or validate the dynamics that prepared it.
Structure-assisted tomography
Section titled “Structure-assisted tomography”Matrix-product-state reconstruction can be efficient when the relevant bond dimension remains manageable. Low rank reduces the number of parameters of a -dimensional state from order toward order , but even a generic rank-one state has exponentially many parameters in the qubit count. Low rank alone is therefore not a polynomial-in-qubits guarantee. The structural assumption must itself be checked with a certificate or residual. If the hard regime produces volume-law entanglement, a low-bond-dimension reconstruction may fit local data while missing global structure.
Classical shadows
Section titled “Classical shadows”For a family of observables chosen independently of the measurement outcomes, classical shadows give simultaneous estimates from a shared data set. The measurements can precede the choice of that independent family. With independent preparations and the prescribed estimator, a schematic sample bound is
where the shadow norm depends on the measurement ensemble and observables. The logarithmic dependence on the number of observables does not remove the potentially large shadow norm, control noise, leakage, or classical post-processing cost. The standard guarantee does not authorize searching the observed data for an unrestricted new observable and retaining the same error bar. Selection from a family already covered by a simultaneous bound is valid; otherwise use fresh confirmation data or a theorem controlling adaptive queries. Huang–Kueng–Preskill give the nonadaptive shadow guarantee; J. Huang and colleagues analyze adaptive observable choice.
Energy and Variance Certificates
Section titled “Energy and Variance Certificates”Ground-state simulation sometimes permits a certificate without knowing the full state. Let have ground-space projector , ground energy , and a gap to every state outside that space. Then
For any state with energy ,
If local terms of are measurable and and are trusted, the energy gives a ground-space fidelity bound. The guarantee weakens when the gap is small or uncertain. It certifies the ground space, not a unique state when the ground space is degenerate. If the measured energy has an upper confidence bound , and trusted lower bounds are and , a conservative version is
on the event that all these bounds hold. Use their joint coverage if several inputs are uncertain. Hangleiter and colleagues turn energy measurements into certification protocols for suitable ground-state simulations.
The energy variance
vanishes precisely when the state is supported in a single energy eigenspace; it need not be a pure eigenvector. Small variance can bound spectral spread, but it does not identify which eigenstate was prepared. A high-energy eigenstate also has zero variance. Energy location, spectral isolation, and generator calibration are indispensable.
Cross-Platform Verification
Section titled “Cross-Platform Verification”Two devices can implement the same target with different microscopic errors. Randomized local measurements can estimate
and hence the Hilbert–Schmidt distance
This can compare states without reconstructing either one fully. In large Hilbert spaces, small Hilbert–Schmidt distance does not automatically imply a strong trace-distance guarantee. In dimension , ; the factor can erase a small Hilbert–Schmidt bound. Exercise 8 gives states with disjoint support that saturate this scaling. Randomized overlap estimators also require a sample analysis; avoiding full reconstruction does not itself guarantee efficient global comparison.
Independence is a scientific design choice
Section titled “Independence is a scientific design choice”Cross-platform agreement is strongest when the devices differ in encoding, control, measurement, and dominant noise. It is weaker if both use the same calibration code, target-map convention, classical fit, or post-processing library. Shared errors create covariance and can make apparent agreement more likely.
Disagreement is useful. By comparing easy limits, local sectors, and response to controlled perturbations, one can often identify whether the discrepancy comes from target conventions, state preparation, dynamics, measurement, or analysis.
Choosing complementary reference problems
Section titled “Choosing complementary reference problems”One-particle sectors test hopping and disorder; small interacting instances test additional couplings; constrained sectors test leakage; and open-system examples test reset, loss, and steady-state handling. Include a case in which each proposed diagnostic is known to fail when the relevant fault is present. Agreement across several easy cases is useful only if they probe different mechanisms. Many-body benchmark problems provides concrete finite models.
Held-Out and Blind Prediction
Section titled “Held-Out and Blind Prediction”Calibration and validation data serve different statistical roles. If a model is fitted on all measured times and observables, agreement with those records is in-sample description, not independent prediction.
A held-out design may reserve:
- later times;
- unseen initial states;
- different observables;
- hidden coupling patterns;
- new system sizes;
- disorder realizations sampled after model freezing;
- a second laboratory or analysis team.
The model, preprocessing, exclusion rules, and acceptance thresholds should be frozen before the held-out outcomes are revealed. Repeatedly inspecting a holdout and updating the model turns it into training data.
Interpolation is easier than extrapolation
Section titled “Interpolation is easier than extrapolation”A randomly withheld point inside a densely sampled calibration region mainly tests interpolation. To test transfer toward the hard regime, choose holdouts that stress the intended direction: larger size, longer time, stronger interaction, different geometry, or a more nonlocal observable. The step must remain small enough that failure is diagnostically useful.
Propagating Error to the Claimed Observable
Section titled “Propagating Error to the Claimed Observable”Verification evidence becomes useful only after it bounds the output of interest.
State distance
Section titled “State distance”For trace distance
any bounded observable satisfies
A global state-distance bound is strong but often expensive. A direct bound for one local observable can be much cheaper and more relevant.
Hamiltonian discrepancy
Section titled “Hamiltonian discrepancy”Let be finite-dimensional Hermitian Hamiltonians, with the same initial state and . Duhamel’s formula gives
Therefore
A conservative observable bound is
This global operator-norm bound often scales poorly with system size. Locality, Lieb–Robinson bounds, perturbation theory, or observable-specific response can give sharper estimates. A loose rigorous bound and a small empirical residual answer different questions and should not be merged without explanation.
Open-system discrepancy
Section titled “Open-system discrepancy”For two contractive Markovian semigroups with generators and , a corresponding induced trace-norm estimate is
under the stated contraction assumptions. Non-Markovian memory, initial system–environment correlations, and time-dependent generators need a different analysis.
Combine errors with their dependence structure
Section titled “Combine errors with their dependence structure”A compatible output-error estimate
is safe when each term is a compatible worst-case bound. Standard uncertainties should not simply be added as if they were worst-case errors, and worst-case bounds should not be combined in quadrature as if independent Gaussian fluctuations. Correlation and shared calibration parameters matter.
Statistical Design
Section titled “Statistical Design”Define the independent unit
Section titled “Define the independent unit”Thousands of shots acquired during one calibration interval may not be thousands of independent device realizations. Drift, common-mode noise, and batch effects make the run, day, chip, or disorder realization the relevant unit for some claims.
Separate exploration and confirmation
Section titled “Separate exploration and confirmation”Choose primary observables, thresholds, exclusion rules, fit models, and holdouts before confirmatory analysis. Exploratory plots remain valuable, but their error bars do not account for all choices made after seeing the data.
Account for many checks
Section titled “Account for many checks”Testing many times, sites, observables, and analysis variants increases the chance of finding an apparent success or failure. Simultaneous confidence regions, hierarchical models, false-discovery controls, or predeclared families may be appropriate. Selecting the best-matching observable after the experiment is not the same as predicting it.
Passing tests do not multiply into a probability of correctness
Section titled “Passing tests do not multiply into a probability of correctness”If three tests pass with nominal coverage, one cannot conclude that the simulation is correct with probability or any other simple product. The tests are conditional on models, can be correlated, and may not cover all failure modes. There is nevertheless a useful general statement: if three specified confidence events each fail with probability at most , their intersection has probability at least by the union bound, without independence. That is coverage of those three events, not a probability that every untested aspect of the simulator is correct.
Worked Example: Transverse-Field Ising Dynamics
Section titled “Worked Example: Transverse-Field Ising Dynamics”Consider an open chain
prepared in . Suppose the target outputs are
and off-site connected correlations ()
The aim is to test increasing size and time. Exact diagonalization is not the final classical benchmark for this particular one-dimensional model: its free-fermion structure permits stronger checks, discussed below.
Layer 1: conventions and limits
Section titled “Layer 1: conventions and limits”At , the initial state is an eigenstate and
At , independent spins give
and off-site connected correlations () remain zero. These limits test the field magnitude, factor of two, time conversion, and readout, but alone cannot distinguish from . At , measuring also probes the sign in the stated Pauli convention. The on-site connected variance is and need not vanish.
Layer 2: short-time moments
Section titled “Layer 2: short-time moments”For the chosen initial state,
and
The interaction does not enter this particular second derivative because the initial expectation values of the relevant terms vanish. Interaction calibration therefore needs other states, higher moments, or correlation growth; fitting only near zero is not sufficient to identify .
Layer 3: structural checks
Section titled “Layer 3: structural checks”The global spin-flip operator
commutes with . Prepare parity eigenstates to test sector preservation. Energy is conserved under the ideal time-independent closed evolution. Local correlation fronts can also be compared with locality bounds. Passing these checks does not exclude a wrong parity-preserving nearest-neighbor coupling.
Layer 4: exact overlap
Section titled “Layer 4: exact overlap”For small , compare complete bitstring distributions, , , and selected basis-rotated observables with exact propagation. Freeze readout correction and Hamiltonian parameters before evaluating held- out times and initial states.
Layer 5: tractable deformation
Section titled “Layer 5: tractable deformation”The one-dimensional model is integrable after a Jordan–Wigner transformation, which permits larger classical checks for this Hamiltonian. To verify a nonintegrable extension, introduce a longitudinal field or other perturbation gradually and compare with tensor-network calculations over their converged time window. Report where bond-dimension or truncation convergence fails.
Layer 6: hard-regime transfer
Section titled “Layer 6: hard-regime transfer”At larger size and later time, retain local generator checks, symmetry tests, injected-fault sensitivity, cross-platform observables where available, and multiple classical approximations with overlapping windows. The final claim should concern the measured observables and finite instances. It should not say that the full many-body wavefunction has been verified.
Verification and classical computational difficulty
Section titled “Verification and classical computational difficulty”A successful check need not compute the target output from scratch. Energy certificates can verify some states whose observables are classically hard to predict, using trusted quantum measurements and known Hamiltonian structure. Interactive protocols may provide additional guarantees under their own assumptions. Efficient verification therefore does not by itself imply efficient classical simulation or undermine quantum advantage.
Conversely, failure of a classical calculation is not a verification test. The resource question concerns the same input family, output, and tolerance as the quantum result. A global state may be expensive to represent while a particular local observable remains easy. The conclusion should match the object actually constrained: a state overlap, a set of observables, an implemented generator, or performance on tested instances.
Exercises
Section titled “Exercises”1. Necessary versus sufficient tests
Section titled “1. Necessary versus sufficient tests”A simulator reports only for a constraint whose eigenvalues include . Does this establish the physical sector ? What changes if a calibrated measurement instead bounds ? Give two substantial errors that still pass the latter test.
Solution
A half-and-half mixture of the and eigenstates has zero mean but no weight in the physical sector. A first moment is insufficient. If every nonzero eigenvalue has magnitude at least one, then , so . This bounds sector leakage, under the measurement assumptions.
An incorrect gauge-invariant coupling and dephasing entirely within the physical sector can both pass even an exact constraint test. Neither the Hamiltonian nor the state has been identified by that test alone.
2. Convert state distance to observable error
Section titled “2. Convert state distance to observable error”Two states satisfy . Bound the discrepancy in the expectation of a Pauli string . What bound follows for ?
Solution
Every Pauli string has , so
The averaged magnetization also has operator norm at most one because the commute and its eigenvalues lie in . Therefore the same global trace-distance information gives
One should not add separate bounds; doing so would discard the norm of the averaged observable.
3. Propagate a Hamiltonian discrepancy
Section titled “3. Propagate a Hamiltonian discrepancy”The calibrated Hamiltonian obeys . Use the global bound on this page to bound the difference of a norm-one observable at . Why may this result be pessimistic?
Solution
The unitary difference is bounded by
Thus
The bound uses the global operator norm and allows the worst possible initial state and observable alignment. A local observable may be insensitive to distant terms over this time, errors may cancel, and a response calculation or locality bound may be much sharper. Those improvements require additional structure rather than simply replacing the rigorous number by an empirical one.
4. Ground-space energy certificate
Section titled “4. Ground-space energy certificate”A target Hamiltonian has trusted ground energy and gap . The energy point estimate is , and a separately constructed one-sided confidence bound gives . Find the nominal and confidence lower bounds on ground-space weight. State two physical assumptions.
Solution
Nominally,
Using gives
The latter is a lower confidence bound conditional on the trusted Hamiltonian information. A quoted one-standard-error interval would not by itself have supplied that confidence level. The argument assumes that the implemented and measured Hamiltonian is the target within accounted uncertainty and that and the spectral gap are valid for the finite sector and boundary conditions. If the ground space is degenerate, the certificate applies to the space, not a selected ground state.
5. Derive the Ising short-time curvature
Section titled “5. Derive the Ising short-time curvature”For the worked Ising Hamiltonian and initial state , derive
Why does this test not identify ?
Solution
The Heisenberg equation gives
Also,
Therefore
In the initial state, and , giving the stated curvature. Since the -dependent expectation vanishes, this one state-observable pair has no second-order sensitivity to . Other preparations, correlation functions, or higher derivatives are needed.
6. Shared bias in a cross-platform comparison
Section titled “6. Shared bias in a cross-platform comparison”Two platforms report the same correlator within . Both use the same target-to-observable conversion code and the same fitted finite-temperature model. Give a verification conclusion and an improved design.
Solution
The result establishes consistency of the two complete pipelines for that correlator, conditional on the shared conversion and temperature model. It does not independently test those shared layers. An improved design would exchange more nearly raw observables, have separate teams implement the target-map and estimator, compare additional quantities with different model dependence, and use hidden instances or held-out parameters. A third reference method or an analytically controlled limit can test the shared convention.
7. Design a holdout toward the hard regime
Section titled “7. Design a holdout toward the hard regime”A model is calibrated for sizes and times . The scientific result concerns at . Propose a staged holdout design more informative than randomly hiding of the calibration points.
Solution
Freeze the generator and analysis after the original calibration. First hold out new initial states and observables at to test model completeness. Then test unseen sizes such as over the classically converged time window. Separately extend time at fixed moderate size until the best classical method loses convergence, using overlapping methods and refinement tests near that boundary. Finally reserve selected combinations of larger size and later time, together with structural checks and injected faults, before evaluating the data. This staircase tests the two extrapolation directions and can localize failure; a random in-domain split mainly tests interpolation.
8. Small Hilbert–Schmidt distance, perfect distinguishability
Section titled “8. Small Hilbert–Schmidt distance, perfect distinguishability”In an even dimension , let and project onto orthogonal -dimensional subspaces with . Set and . Find their purities, Hilbert–Schmidt distance, and trace distance. Can a small unnormalized overlap metric certify operational indistinguishability as grows?
Solution
Both states have purity and . Consequently,
The difference has eigenvalues and eigenvalues , so its trace norm is two. Measuring distinguishes the states perfectly, even as their Hilbert–Schmidt distance tends to zero. The dimension factor in converting this norm to trace distance is essential.
References
Section titled “References”-
E. Bairey, I. Arad, and N. H. Lindner, “Learning a local Hamiltonian from local measurements,” Physical Review Letters 122, 020504 (2019), doi:10.1103/PhysRevLett.122.020504.
-
M. Cramer et al., “Efficient quantum state tomography,” Nature Communications 1, 149 (2010), doi:10.1038/ncomms1147.
-
J. Eisert et al., “Quantum certification and benchmarking,” Nature Reviews Physics 2, 382–390 (2020), doi:10.1038/s42254-020-0186-4.
-
A. Elben et al., “Cross-platform verification of intermediate scale quantum devices,” Physical Review Letters 124, 010504 (2020), doi:10.1103/PhysRevLett.124.010504.
-
A. Elben et al., “The randomized measurement toolbox,” Nature Reviews Physics 5, 9–24 (2023), doi:10.1038/s42254-022-00535-2.
-
S. T. Flammia and Y.-K. Liu, “Direct fidelity estimation from few Pauli measurements,” Physical Review Letters 106, 230501 (2011), doi:10.1103/PhysRevLett.106.230501.
-
D. Hangleiter, M. Kliesch, M. Schwarz, and J. Eisert, “Direct certification of a class of quantum simulations,” Quantum Science and Technology 2, 015004 (2017), doi:10.1088/2058-9565/2/1/015004.
-
P. Hauke, F. M. Cucchietti, L. Tagliacozzo, I. Deutsch, and M. Lewenstein, “Can one trust quantum simulators?” Reports on Progress in Physics 75, 082401 (2012), doi:10.1088/0034-4885/75/8/082401.
-
H.-Y. Huang, R. Kueng, and J. Preskill, “Predicting many properties of a quantum system from very few measurements,” Nature Physics 16, 1050–1057 (2020), doi:10.1038/s41567-020-0932-7.
-
J. Huang, L. Lewis, H.-Y. Huang, and J. Preskill, “Predicting adaptively chosen observables in quantum systems,” PRX Quantum 7, 010347 (2026), doi:10.1103/xhn1-vnp9.
-
M. Kliesch and I. Roth, “Theory of quantum system certification,” PRX Quantum 2, 010201 (2021), doi:10.1103/PRXQuantum.2.010201.