

Analytic Continuation
Analytic continuation connects an equilibrium Green function known on imaginary time or Matsubara frequency to the boundary value of a causal real-frequency function.
For a spectral convention in which
the exact bridge is
This arrow hides two different problems.
- Exact continuation: identify the unique analytic function in the correct physical class when exact information is sufficient.
- Numerical continuation: infer real-frequency information from finitely many uncertain imaginary-axis data.
The first is a statement about complex analysis and the spectral class. The second is an inverse problem. A continuation method can produce a stable curve only by combining the data with constraints, regularization, a prior, a restricted model, or some mixture of them. The resulting resolution is part of the answer.
Helpful background. Spectral Representation supplies the forward kernels and separate bosonic static term; Retarded and Advanced Response explains the causal analytic half-plane. Here we ask what a finite, uncertain data set can determine about that analytic function.
Imaginary-axis data and real-frequency questions
Section titled “Imaginary-axis data and real-frequency questions”Imaginary-time methods are exceptionally effective for equilibrium quantities. Quantum Monte Carlo, finite-temperature tensor networks, perturbative Matsubara calculations, and impurity solvers can all produce precise Euclidean correlators. Experiments and dynamical interpretation, however, often concern:
- excitation energies and continua;
- retarded susceptibilities;
- optical conductivity;
- spectral gaps and threshold exponents;
- damping rates and linewidths;
- quasiparticle residues;
- transport peaks.
These are real-frequency quantities. The Euclidean calculation is therefore sometimes an intermediate representation rather than the endpoint.
The danger is subtle. A reconstructed spectrum may:
- reproduce every plotted input point;
- obey positivity and normalization;
- look smooth and physically plausible;
- agree across two implementations of the same regularizer;
yet contain peak splitting, linewidths, or fine structure that the data do not identify. Trustworthy continuation asks not only “what curve was returned?” but also “which statements survive the ambiguity allowed by the data and assumptions?”
Spectral variables and retarded boundaries
Section titled “Spectral variables and retarded boundaries”Energy rather than angular frequency
Section titled “Energy rather than angular frequency”The spectral variable on this page is an energy . Matsubara energies are
Thus the analytic argument , the spectral variable , and the retarded boundary argument all have units of energy. If angular frequency is used instead, specify whether the density is per unit energy or per unit angular frequency. Merely evaluating introduces no Jacobian; changing an integration measure does.
Thermal generator
Section titled “Thermal generator”Equilibrium evolution is generated by
when a chemical potential is included. Assume positive temperature and a normalizable grand-canonical Gibbs state; for number-changing fields the trace runs over the full Fock space. Spectral energies are then differences of eigenvalues of . Translating to laboratory energies requires the charge of the operator and the chemical-potential convention.
Retarded boundary
Section titled “Retarded boundary”For the Cauchy-transform convention
the upper boundary is retarded:
The Sokhotski–Plemelj relation gives
Therefore
for a real scalar spectral measure, in the distributional sense where needed. For a Hermitian matrix spectral measure, use the anti-Hermitian part, , with on the real axis. Taking the imaginary part of each matrix entry independently is generally incorrect. Susceptibilities, conductivities, and ordered observable spectra can carry other signs or thermal factors.
Input domains
Section titled “Input domains”Two common inputs are:
and
They encode the same analytic object only when their transforms, endpoint conventions, contact terms, and frequency parity are mutually consistent.
The Exact Analytic Problem
Section titled “The Exact Analytic Problem”Suppose the physical Green function belongs to a declared class of functions analytic away from the real axis and has a spectral representation
If is known, evaluating anywhere off the support is a forward problem. If the analytic function itself is known on an open set, the identity theorem fixes its continuation throughout each connected analytic domain.
Matsubara values require an additional observation: the points are discrete, and their only accumulation point is at infinity. The elementary identity theorem therefore does not by itself say that an arbitrary analytic function is fixed by those samples.
A standard result due to Baym and Mermin establishes uniqueness within the physical thermal Green-function class after the required analyticity, asymptotic, and growth conditions are imposed. Its message is bounded:
- all exact Matsubara values are used;
- the candidate belongs to the correct analytic class;
- the large- behavior is controlled;
- the continuation seeks the corresponding thermal Green function.
It does not say that a finite uncertain data vector determines a stable real-frequency curve.
Three Different Questions
Section titled “Three Different Questions”Uniqueness
Section titled “Uniqueness”Do the exact assumptions select at most one admissible spectrum or analytic function?
For infinitely many exact thermal data together with the proper analytic class, the answer can be yes. For finitely many interpolation conditions in a broad function class, infinitely many continuations generally remain.
Stability
Section titled “Stability”Does a small perturbation in the input produce a small perturbation in the output under a stated norm?
Analytic continuation is unstable in the unrestricted inverse sense. Tiny imaginary-axis perturbations can correspond to large changes in rapidly varying real-axis structure.
Feature identifiability
Section titled “Feature identifiability”Is a particular quantity, such as a gap, integrated weight, peak position, doublet splitting, or linewidth, fixed within useful uncertainty?
A full spectrum may be poorly identified while a low-order moment or broad integrated weight is precise. Conversely, a visually stable central curve does not prove that every feature drawn on it is identifiable.
These questions should never be collapsed into the statement that continuation “works” or “fails.”
Forward Maps
Section titled “Forward Maps”Generic linear form
Section titled “Generic linear form”Both imaginary-time and Matsubara formulations can be written as
Here:
- is the known kernel;
- is a separately represented contact or static term when needed;
- is statistical or numerical error.
The forward map is smoothing. Oscillatory or sharply localized changes in can have a very small image under .
Fermionic imaginary-time kernel
Section titled “Fermionic imaginary-time kernel”For a common single-particle convention,
where
for one normalized canonical orbital.
The kernel combines exponential damping with a thermal denominator. At low temperature, positive-energy weight mainly affects small , negative-energy weight mainly affects , and fine structure is smoothed in both directions.
Fermionic Matsubara kernel
Section titled “Fermionic Matsubara kernel”The same spectrum gives
Large Matsubara energies mostly constrain moments:
Adding many high-frequency points can improve moment information without creating fine low-energy resolution.
Bosonic observable kernels
Section titled “Bosonic observable kernels”For an ordered positive spectrum , a Euclidean observable correlator often has a thermal kernel of the form
The exact kernel depends on whether denotes an ordered, symmetrized, or commutator spectrum. A bosonic commutator density is generally signed:
for the retarded commutator convention in a Hermitian autocorrelation channel at positive temperature, rather than on the whole axis.
The static term can contribute only to the zero Matsubara component:
Forcing this contribution into a regular dynamical spectrum can create a spurious narrow peak near zero energy.
Discretization
Section titled “Discretization”Choose quadrature nodes and weights , and define spectral weights
Then
with
This finite matrix is not the physics by itself. Its singular values depend on:
- the input grid;
- the spectral window;
- the output parameterization;
- quadrature weights;
- row and column scaling;
- the covariance metric;
- any exact constraints already eliminated.
A grid-refinement study is therefore mandatory. If doubling the output grid creates twice as many apparent narrow features while leaving the data fit unchanged, those features are discretization degrees of freedom rather than additional information.
Covariance Is Part of the Data
Section titled “Covariance Is Part of the Data”Complex Matsubara data contain correlated real and imaginary parts. Stack those parts into one real data vector and stack the corresponding kernel rows in the same order. In the following likelihood and regularization formulas, , , and denote this real representation; then reduces to transpose. This keeps information that would be lost by using only a complex covariance when the complex noise is not circularly symmetric.
Let
be the estimated covariance. The appropriate Gaussian misfit is
Treating correlated input points as independent changes both the effective information content and the preferred reconstruction. This is common for:
- imaginary-time Monte Carlo bins;
- Matsubara values obtained by transforming the same time samples;
- symmetry-averaged correlators;
- data constrained by endpoint identities;
- solver outputs sharing truncation errors.
The covariance estimate itself may be noisy or rank deficient. Blindly inverting small covariance eigenvalues can assign enormous weight to directions that are poorly estimated. Defensible choices include:
- increasing independent samples;
- blocking data until residual autocorrelation is controlled;
- using a shrinkage covariance with documented strength;
- removing redundant data directions while enforcing any exact zero-variance relations as constraints;
- formulating the likelihood from underlying independent samples.
Any covariance regularization belongs in the method report.
Whitening
Section titled “Whitening”For a positive-definite covariance, define
and
Then
Whitening measures distinguishability in units of the stated uncertainty. Two spectra and are difficult to distinguish when
subject to the confidence convention and number of tested directions.
This criterion concerns the difference of forward predictions, not the visual distance between the spectra.
Singular Values and Lost Resolution
Section titled “Singular Values and Lost Resolution”Take the singular-value decomposition
where
Expand a spectral perturbation in right singular vectors:
Its whitened data image is
Directions with small barely change the data. Formal inversion would divide by :
Noise is therefore amplified most strongly in the modes that encode rapid or delicate spectral structure.
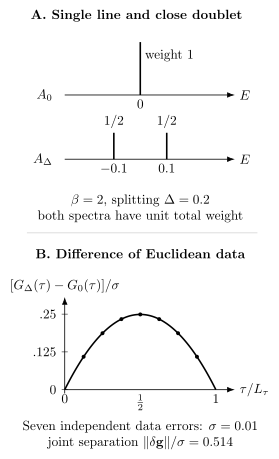
An exact fermion-kernel example: compare with at . The single line gives ; the doublet gives . For seven equally spaced interior samples with independent standard errors , the covariance-weighted separation is only 0.514. The doublet therefore changes the predictions much less than the stated uncertainty, despite being visibly different on the energy axis.
Truncated singular-value inversion
Section titled “Truncated singular-value inversion”A truncated estimator keeps only modes above a chosen cutoff:
This is stable after truncation, but it returns a projection of the spectrum onto the retained right-singular subspace. Changing changes the estimator’s resolution.
Tikhonov filtering
Section titled “Tikhonov filtering”For quadratic regularization,
When and ,
For fixed , the filter factor
suppresses poorly constrained modes continuously. Stability is purchased by bias.
Resolution matrix
Section titled “Resolution matrix”For the same quadratic case, the noise-free expectation satisfies
where
A row of is a discrete resolution kernel. It shows how a nominal output energy mixes weight from neighboring energies. Reporting this kernel is more informative than quoting the spacing of the output grid.
Ill-Posed Does Not Mean Meaningless
Section titled “Ill-Posed Does Not Mean Meaningless”In Hadamard’s terminology, a well-posed inverse problem has:
- a solution;
- a unique solution;
- continuous dependence on the data.
Finite-data analytic continuation can violate uniqueness and continuous dependence in a broad spectral class. Regularization defines a nearby, stable estimation problem. It does not convert the original unrestricted inverse into a well-posed measurement of every spectral detail.
Useful information can still be robust:
- total spectral weight;
- low-order moments;
- a broad gap interval;
- the presence of weight in a large energy window;
- the position of an isolated dominant feature;
- a static susceptibility;
- a coarse transport scale.
The right question is often narrower than “reconstruct the entire spectrum.”
Regularization as Additional Information
Section titled “Regularization as Additional Information”A broad class of estimators minimizes
subject to physical constraints. The regularizer may encode:
- smoothness;
- proximity to a default model;
- sparsity in a chosen basis;
- few poles or bands;
- bounded variation;
- positivity;
- known support.
In Bayesian language,
where the likelihood contains the covariance and the prior contains assumptions about admissible spectra. Penalized optimization and Bayesian inference need not be identical, but both make the same conceptual point: finite data alone do not select a detailed spectrum.
Regularization is not an embarrassment to conceal. It is information to declare and test.
Physical Constraints
Section titled “Physical Constraints”Constraints can remove unphysical candidates and improve precision. They cannot generate data resolution that is absent.
Positivity
Section titled “Positivity”For a normalized diagonal fermionic spectral function,
For a dynamic structure factor in a conjugate channel,
But ordinary positivity is not universal:
- a bosonic commutator spectrum changes sign across ;
- off-diagonal spectral components can be signed or complex;
- anomalous Green functions are not positive scalar measures;
- self-energy spectra require their own convention and analytic conditions.
Applying a positive-spectrum algorithm to a signed channel silently changes the inference problem.
Normalization and moments
Section titled “Normalization and moments”Exact equal-time algebra can determine
Moments can be imposed as exact constraints only when they are exact in the same convention and numerical representation. If a moment comes from another uncertain calculation, it belongs in the likelihood with its covariance.
High-order moments emphasize spectral tails and can be numerically fragile. An inaccurate “exact” moment can force compensating artifacts elsewhere.
Support
Section titled “Support”Known lower or upper spectral bounds can be powerful. A guessed plotting window is not a physical support theorem. If appreciable weight lies outside the chosen window, normalization and moments can push that missing weight into false edge peaks.
Symmetry and detailed balance
Section titled “Symmetry and detailed balance”Hermiticity, particle–hole symmetry, and KMS detailed balance can relate positive and negative energies. They should be enforced only when the operator, state, and convention possess the claimed symmetry.
For an ordered equilibrium spectrum,
This reduces redundant degrees of freedom, but it does not fix the line shape on the independent half-axis.
Causality and analytic structure
Section titled “Causality and analytic structure”A physical retarded Green function is analytic in the upper half-plane. Its real and imaginary parts obey dispersion relations after any required subtractions. For positive scalar spectral measures, the corresponding Cauchy transform also has a definite half-plane sign.
Causality constraints reject some spurious rational functions and matrix continuations. They still leave a family of functions consistent with finite data.
Matrix positivity
Section titled “Matrix positivity”For a matrix-valued fermionic spectrum,
and
for every vector in a positive spectral channel.
Continuing each matrix element independently can violate Hermiticity or positive semidefiniteness even when every diagonal entry looks reasonable. Matrix-aware parameterizations preserve the joint constraint.
Static and contact terms
Section titled “Static and contact terms”Separate any known:
- equal-time discontinuity;
- delta function in time;
- frequency-independent offset;
- conserved bosonic zero mode;
- diamagnetic or contact contribution.
The dynamic spectral kernel should not be asked to mimic algebraic pieces it does not represent.
Choosing the Target
Section titled “Choosing the Target”Before selecting an algorithm, write down:
- the operator pair and ordering;
- the thermal generator;
- the imaginary-time or Matsubara transform;
- the spectral density being inferred;
- the relation between that density and the retarded observable;
- all static and contact terms;
- valid positivity, symmetry, support, and moment constraints.
For conductivity, for example, continuing a paramagnetic current correlator is not yet the full optical response. Diamagnetic terms, zero-frequency distributions, volume normalization, and limiting prescriptions must be handled through the Kubo Formula and the relevant transport convention.
Method Families
Section titled “Method Families”No continuation family is uniformly best. Each selects or averages over the admissible set differently.
- Rational or Padé: adds a low-order rational form and can excel for high-precision meromorphic data, but is vulnerable to noise-sensitive pole–zero artifacts.
- Maximum entropy: favors a positive spectrum near a default model and stably recovers broad structure, but smooths and biases according to the prior.
- Stochastic continuation: samples or optimizes constrained spectra and can expose nonparametric ambiguity, but its ensemble depends on the parameterization and sampling rule.
- Sparse or parametric: assumes few components in a chosen representation and can be highly interpretable when the model is valid, but can become overconfident under model mismatch.
- Nevanlinna or related interpolation: enforces half-plane analytic structure and preserves causality or positivity in the applicable class, but finite uncertain data still leave nonuniqueness.
- Direct real-axis or real-time methods: avoid Euclidean inversion for a target observable, while introducing separate finite-time, broadening, truncation, or solver errors.
Rational and Padé continuation
Section titled “Rational and Padé continuation”A rational approximant writes
where and are polynomials chosen to interpolate or fit the imaginary-axis data. Continued fractions are a common numerical representation.
This approach can be effective when:
- the input has very high precision;
- the analytic function is well represented by a modest number of poles;
- the frequency range is controlled;
- large- asymptotics are built in;
- the result is stable under precision, order, and point-selection changes.
It is fragile because nearby poles and zeros can cancel on the imaginary axis while producing large real-axis excursions. Noise may split one physical feature into several pole–zero pairs or place poles in the wrong half-plane.
A rational continuation should report:
- numerator and denominator orders;
- arithmetic precision;
- input points and weighting;
- pole locations and residues;
- near-canceling pole–zero pairs;
- stability across admissible orders;
- causality and sum-rule checks.
Smoothing the returned curve after a noisy Padé fit can hide unstable poles without repairing the inference.
Maximum-entropy spectral continuation
Section titled “Maximum-entropy spectral continuation”For a positive scalar spectrum and positive default model , a common entropy is
It satisfies
with equality at . A maximum-entropy estimator balances fit and relative entropy:
The default model can encode known support, normalization scale, and coarse prior shape. The hyperparameter controls how strongly departures from it are penalized.
There are several nonequivalent prescriptions for handling :
- maximize or average over a marginal-likelihood approximation;
- use a discrepancy criterion for ;
- cross-validate held-out input modes;
- average over a declared hyperprior.
The output is conditional on this choice. A responsible analysis varies:
- the default-model shape;
- its normalization when not fixed;
- the frequency window;
- the output grid;
- the prescription;
- the covariance treatment.
Maximum entropy is naturally formulated for positive measures. Signed spectra can sometimes be decomposed or reparameterized, but the result is a different prior problem and should not be presented as ordinary positive MaxEnt.
This spectral entropy is a regularizer over candidate functions. It is not the von Neumann entropy of a quantum state and does not follow directly from thermodynamic entropy maximization.
Stochastic analytic continuation
Section titled “Stochastic analytic continuation”Stochastic methods represent the spectrum by movable peaks, bins, rectangles, basis coefficients, or other positive components and then sample or optimize configurations according to a data-fit and regularization rule.
A schematic sampling weight is
where is an algorithmic sampling temperature or regularization control and represents the measure over parameterized spectra.
Advantages include:
- nonparametric movement of spectral weight;
- straightforward positivity and normalization constraints;
- access to distributions of coarse features;
- less commitment to one smooth central solution.
Important limitations remain:
- a “uniform” measure depends on the parameterization;
- the sampling temperature is not automatically a physical temperature;
- the spread of sampled curves is not automatically a calibrated posterior interval;
- averaging can broaden peaks even when each sampled spectrum is sharp;
- optimization can lock onto spurious structure as the fit is tightened.
Report distributions of feature functionals, such as peak weight or gap edge, rather than using only the pointwise mean spectrum.
Sparse and parametric continuation
Section titled “Sparse and parametric continuation”Suppose
where are chosen basis functions. Sparsity penalties, low-rank models, a few Lorentzians, pole expansions, known thresholds, and self-energy ansätze all restrict the candidate class.
Such models can give excellent resolution when the restriction is physically correct. They also make the conclusion conditional:
- a two-peak fit can resolve a doublet because it assumes a two-component family;
- a sparse pole basis favors isolated lines over continua;
- a smooth spline basis disfavors sharp thresholds;
- a Lorentzian model encodes a specific line shape and tail.
Model checks should include:
- comparison with less restrictive alternatives;
- residual structure in the whitened basis;
- parameter identifiability and correlations;
- synthetic tests with model mismatch;
- marginal likelihood or predictive performance where meaningful.
Machine-learned continuation belongs in the same category unless the training distribution is broad enough to define a defensible prior for the physical problem. A network cannot infer features absent from both the input information and its training assumptions.
Nevanlinna and causality-preserving interpolation
Section titled “Nevanlinna and causality-preserving interpolation”For a positive scalar spectral measure, the Cauchy transform belongs, up to convention-dependent signs, to a Herglotz–Nevanlinna class: it maps one half-plane into a definite half-plane and obeys strong analytic constraints.
Nevanlinna continuation uses this structure to parameterize all analytic interpolants consistent with exact input values and positivity. Continued-fraction or Schur-type constructions can preserve:
- analyticity;
- the correct half-plane sign;
- nonnegative spectral weight in the applicable channel, with normalization imposed through the appropriate asymptotic or sum-rule constraint.
This is a major advantage over unconstrained rational interpolation. Its scope is still bounded:
- noisy data may need projection onto a feasible interpolation set;
- finite data leave a family of admissible analytic functions;
- a selection or averaging rule within that family adds assumptions;
- signed, anomalous, or matrix channels require appropriate generalizations;
- positivity and causality do not guarantee fine-feature identifiability.
Use the exact analytic class as a constraint, not as a promise of unlimited resolution.
Matrix-valued continuation
Section titled “Matrix-valued continuation”For orbital, spin, Nambu, or cluster Green functions, the target is a matrix function. Continuing matrix elements separately neglects their shared spectral geometry.
Safer approaches parameterize:
in positive matrix channels, or continue quadratic forms
with consistency across a spanning set of vectors. Matrix maximum-entropy, Carathéodory, and related constructions are designed to preserve joint positivity and analyticity.
Basis covariance also matters. A method should transform consistently under a unitary change of orbital basis. Elementwise priors often do not.
Direct alternatives
Section titled “Direct alternatives”When the scientific target is real frequency, it may be better to avoid Euclidean inversion:
- real-time tensor-network evolution;
- correction-vector or resolvent solvers;
- real-axis diagrammatic equations;
- Chebyshev or kernel-polynomial expansions;
- exact diagonalization with controlled finite-size broadening;
- nonequilibrium contour methods;
- experimentally forward-modeled response.
These methods have their own limits. A finite time gives a characteristic energy resolution
and a resolvent evaluated at returns an -broadened spectrum. Avoiding analytic continuation exchanges one error structure for another; it does not remove the need for resolution analysis.
Ask Well-Posed Questions
Section titled “Ask Well-Posed Questions”Often the desired quantity is a linear spectral functional
rather than every value of . Seek coefficients such that
Then
estimates the functional directly. Its variance is
and its bias is controlled by the kernel mismatch
This route can estimate a broad integrated weight or moment much more reliably than reconstructing a fine spectrum first and integrating the reconstruction afterward.
Examples of comparatively well-posed questions include:
- total weight in a wide energy interval;
- a low-order moment;
- a broad centroid;
- whether weight below a coarse threshold exceeds a bound;
- a smooth transport integral.
A narrow linewidth or sub-resolution doublet is usually a harder functional.
Worked Example: One Exact Pole
Section titled “Worked Example: One Exact Pole”Consider
Its Matsubara Green function is
If this one-pole form is known exactly and are real, even one exact datum at a nonzero Matsubara energy determines the two parameters. Indeed,
Thus and . For example, , , and give , whose reciprocal is . Additional points test the one-pole assumption: their reciprocals must lie on the same affine function of .
This is not unrestricted analytic continuation. It is parameter estimation inside a two-parameter model. The apparent high resolution comes from the correct pole assumption.
If the true spectrum contains a continuum,
the same fit can absorb continuum effects into biased and . Residuals, model expansion, and synthetic mismatch tests are therefore essential.
Worked Example: An Unresolved Doublet
Section titled “Worked Example: An Unresolved Doublet”Take two equal lines centered at :
For a smooth kernel,
Expanding around gives
The linear term cancels. Sensitivity to a small symmetric splitting begins at order . If
the doublet is not distinguished from a single line at the covariance scale. A method may still draw two peaks because its model or prior prefers them, but the input has not independently resolved the splitting.
Worked Example: Static Bosonic Weight
Section titled “Worked Example: Static Bosonic Weight”Let be conserved:
For ,
is constant, and
The commutator spectrum vanishes because . A continuation of only the regular commutator kernel cannot recover this constant term. If the zero-frequency datum is included without a separate static component, the optimizer may invent arbitrarily narrow low-energy weight.
This is a representation error, not merely poor regularization.
From Spectrum to Retarded Response
Section titled “From Spectrum to Retarded Response”The continuation endpoint should be a causal quantity with a declared prescription:
In numerical plots, one often uses
Its imaginary part is a Lorentzian convolution:
The display broadening must not be confused with:
- intrinsic decay width;
- continuation resolution;
- finite-size level spacing;
- experimental energy resolution.
All four can broaden a plotted feature, but they have different meanings.
Data Preparation
Section titled “Data Preparation”Continuation cannot repair an inconsistent input correlator.
Equilibrate and estimate autocorrelation
Section titled “Equilibrate and estimate autocorrelation”For Monte Carlo data, verify equilibration, block beyond the integrated autocorrelation scale, and propagate the same blocked samples into means and covariance. An underestimated covariance invites overfitting.
Enforce identities before fitting
Section titled “Enforce identities before fitting”Check:
- endpoint and parity relations;
- equal-time discontinuities;
- complex-conjugation symmetry;
- Matsubara positive-negative frequency pairing;
- known asymptotic tails;
- exact normalization;
- static zero-mode contributions.
If an identity is imposed by symmetrization, recompute the covariance after that linear transformation.
Avoid double counting
Section titled “Avoid double counting”Imaginary-time data and Matsubara data obtained from the same samples are not independent. Fitting both with separate diagonal error bars double counts information unless their joint covariance is included.
Subtract known tails analytically
Section titled “Subtract known tails analytically”If
the expansion is useful for fitting tails and evaluating transforms. It is not generally safe to treat the finite series as a globally valid propagator: its higher powers introduce singular spectral distributions at zero energy. A safer subtraction uses a known causal reference function with the required moments, then restores that function after continuation. The residual spectrum need not remain positive, so a positive-spectrum algorithm cannot be applied to it unchanged. Reduced dynamic range can help numerical conditioning, but no subtraction restores information absent from the data.
Choose dimensionless variables
Section titled “Choose dimensionless variables”Rescale energy and amplitudes so the numerical problem has moderate magnitudes. Record the transformation so normalization, moments, and covariance are restored correctly.
Testing whether a feature is resolved
Section titled “Testing whether a feature is resolved”Generate synthetic data with the same input grid, kernel, and covariance as the calculation. Test plausible alternatives, including a single peak versus a doublet, a sharp versus rounded threshold, and missing weight outside the fitted window. Success only on the shapes favored by the chosen prior is a weak test.
Next vary the output grid, support, default model, regularization strength, and selected input points. Compare the physical quantity of interest—such as weight in an energy interval—rather than requiring pointwise agreement between reconstructed curves. Holding out data can test prediction in the imaginary-time domain, but several spectra may still share those predictions.
For a sharper statement, collect all spectra in a set that obey the exact constraints and satisfy an explicitly chosen misfit threshold. Bound the desired functional by
For a claimed gap, specify the smallest detectable in-gap weight. For a linewidth or doublet, show a nearby alternative that the data can exclude. Keep any plotting broadening separate from this inferential resolution.
Interpreting Uncertainty
Section titled “Interpreting Uncertainty”Several uncertainties coexist:
- sampling uncertainty: finite stochastic or experimental samples;
- solver uncertainty: truncation, convergence, discretization, and finite size;
- kernel uncertainty: temperature, calibration, or forward-model parameters;
- regularization uncertainty: hyperparameter and prior choice;
- model uncertainty: whether the admissible spectral family is appropriate;
- non-identifiability: multiple admissible spectra predict indistinguishable data.
A narrow bootstrap band from one fixed regularizer captures only part of this list. In strongly ill-posed settings, model and non-identifiability uncertainty can dominate pointwise sampling uncertainty.
Common Mistakes
Section titled “Common Mistakes”Treating substitution as an algorithm
Section titled “Treating substitution as an algorithm”Writing
is valid after the analytic function has been identified. It does not specify how to reconstruct that function from a finite table.
Invoking the identity theorem on Matsubara points
Section titled “Invoking the identity theorem on Matsubara points”The Matsubara grid has no finite accumulation point. Uniqueness requires the physical analytic and asymptotic class, not merely the statement that the function is analytic.
Ignoring covariance
Section titled “Ignoring covariance”Diagonal error bars can overcount heavily correlated time points and drive the reconstruction toward noise.
Forcing positivity in the wrong channel
Section titled “Forcing positivity in the wrong channel”Bosonic commutator spectra, off-diagonal matrix elements, anomalous functions, and many self-energy conventions are not ordinary nonnegative scalar measures.
Confusing fit quality with resolution
Section titled “Confusing fit quality with resolution”A very small may indicate overfitting. It does not prove that narrow structures are physical.
Reading grid spacing as energy resolution
Section titled “Reading grid spacing as energy resolution”An output grid spacing of does not imply that features separated by are identifiable. Resolution follows from the kernel, covariance, and assumptions.
Reporting only one default model
Section titled “Reporting only one default model”One smooth reconstruction conceals prior dependence. Vary the default over physically plausible alternatives while preserving exact constraints.
Treating stochastic spread as automatic error bars
Section titled “Treating stochastic spread as automatic error bars”The sampled ensemble depends on its measure, parameterization, and algorithmic temperature. Calibration requires synthetic and coverage tests.
Continuing matrix elements independently
Section titled “Continuing matrix elements independently”Elementwise fits can violate Hermiticity, positive semidefiniteness, basis covariance, and common pole structure.
Hiding static weight in a narrow peak
Section titled “Hiding static weight in a narrow peak”A conserved bosonic contribution belongs to a separate zero Matsubara term. Represent it explicitly.
Overinterpreting cross-method agreement
Section titled “Overinterpreting cross-method agreement”Methods with similar positivity and smoothness assumptions can return similar curves from the same underdetermined data.
Broadening twice
Section titled “Broadening twice”Continuation regularization, finite-time windows, resolvent , and plotting convolution can all broaden structure. Track each operation separately.
Calling a prior a theorem
Section titled “Calling a prior a theorem”Smoothness, sparsity, few-pole structure, and default models can be physically motivated. They remain assumptions unless derived for the system and observable.
Further connections
Section titled “Further connections”Spectral Functions explains which physical conclusions can follow from a line shape. DMFT for Quantum Materials applies these methods to impurity and material calculations. For optical response, include the contact terms and limiting prescriptions in Transport Coefficients; a continued paramagnetic correlator alone is not the conductivity. Sum Rules derives the moment constraints.
Exercises
Section titled “Exercises”1. Finite interpolation is not uniqueness
Section titled “1. Finite interpolation is not uniqueness”Let be distinct points in the upper half-plane, and suppose is analytic there. Construct a nonzero analytic perturbation that vanishes at every and decays as for large within the upper half-plane. What does this prove, and what does it not prove, about thermal Green functions?
Solution
Choose and define
The only pole is at , which lies in the lower half-plane. Thus is analytic in the upper half-plane. At every input point,
For large in the upper half-plane,
Therefore and agree at all sampled points but differ elsewhere.
This proves that finitely many interpolation conditions do not determine an arbitrary upper-half-plane analytic function. It does not prove that both candidates are physical Green functions. The perturbation may violate positivity, reflection properties, moments, or the joint upper- and lower-half-plane spectral representation. Baym–Mermin uniqueness concerns infinitely many exact thermal samples inside the proper physical class.
2. Quantify singular-mode noise amplification
Section titled “2. Quantify singular-mode noise amplification”A whitened kernel has two singular values
Suppose the whitened data error has magnitude along each left singular vector.
- Find the formal inverse error along each right singular vector.
- For Tikhonov regularization with and , find the resolution filter factors .
Solution
Formal inversion divides a data-mode error by the corresponding singular value:
Thus
while
The second spectral component is effectively unconstrained by a unit-scale prior.
The Tikhonov resolution factors are
Therefore
and
The first mode is nearly retained, whereas the unstable second mode is almost completely suppressed. The stable output is correspondingly biased toward the retained subspace.
3. Correlated data do not count twice
Section titled “3. Correlated data do not count twice”Two estimates and have equal variance and correlation coefficient :
For the average
find its variance. Compare it with the variance inferred by incorrectly treating the points as independent. Evaluate the ratio for .
Solution
Write
Then
If the points were independent, one would report
The true variance is larger by the factor
For , the factor is . Two strongly correlated points contain much less than twice the information of one point.
4. Derive the doublet sensitivity
Section titled “4. Derive the doublet sensitivity”For
show that the difference from a single line begins at order for any smooth forward kernel .
Solution
The doublet prediction is
Taylor expansion gives
Adding the two expansions cancels all odd terms:
The single-line prediction is . Hence
This quadratic suppression explains why close symmetric doublets are difficult to resolve.
5. Check the positivity class
Section titled “5. Check the positivity class”A Hermitian bosonic operator in a two-level system has commutator spectral density
Is a nonnegative measure? Verify the correct sign condition and explain why ordinary positive MaxEnt is inappropriate without reparameterization.
Solution
At positive energy the line has weight , whereas at negative energy it has weight . Thus is not a nonnegative measure.
Multiplication by gives positive weight at both lines:
Therefore
as a distribution. A positive-spectrum entropy applied directly to would forbid the required negative-energy line and change the physical channel. One may instead infer a positive ordered spectrum on an independent half-axis and impose detailed balance, or use a signed-spectrum formulation derived for the chosen convention.
6. Derive a MaxEnt stationarity equation
Section titled “6. Derive a MaxEnt stationarity equation”Discretize a positive spectrum as components with default components . Let
and
Find the stationarity equation for an interior maximum.
Solution
The entropy derivative is
The misfit derivative is
Setting the total derivative to zero gives
Equivalently,
The equation is nonlinear because appears in the residual. It also makes the default-model role explicit: when the data gradient is weak relative to , remains near .
7. Estimate a spectral functional directly
Section titled “7. Estimate a spectral functional directly”In a discretized problem,
The target is
Among linear estimators that are unbiased for every , derive the minimum-variance weights. Assume the required inverses exist.
Solution
Unbiasedness for every requires
The variance is
Introduce a multiplier vector and minimize
Stationarity with respect to gives
Thus
Imposing unbiasedness yields
Therefore
The minimum variance is
If is singular, some functionals may still be estimable: the condition is , and the corresponding generalized inverse gives the minimum-variance solution. Outside that subspace, no linear estimator is unbiased for every spectrum. Even an estimable functional may have impractically large variance; allowing a controlled kernel mismatch can reduce it.
8. Separate a conserved zero mode
Section titled “8. Separate a conserved zero mode”Suppose the measured bosonic correlator is
with and the commutator spectral measure. Here is the Euclidean correlator without the overall Green-function minus sign, hence the minus sign before its Cauchy transform. Explain how you would prepare these data for continuation and give two failures caused by omitting the first term.
Solution
Represent as a separate static parameter. If it is known independently, subtract
before fitting the dynamical kernel. If it is uncertain, fit it jointly with using its prior information or covariance, while keeping it algebraically distinct.
Omitting the static term can cause:
- a spurious very narrow peak near as the dynamical spectrum attempts to reproduce the excess zero-frequency datum;
- distortion of broad low-energy weight or the inferred gap because normalization and regularization redistribute the unmatched static contribution.
Dropping the datum without explanation avoids one mismatch but discards information about and may conceal a physically important conserved fluctuation.
References
Section titled “References”- G. Baym and N. D. Mermin, “Determination of Thermodynamic Green’s Functions,” Journal of Mathematical Physics 2, 232–234 (1961); uniqueness of the thermal continuation under the required analytic and asymptotic conditions.
- D. Bergeron and A.-M. S. Tremblay, “Algorithms for Optimized Maximum Entropy and Diagnostic Tools for Analytic Continuation,” Physical Review E 94, 023303 (2016); implementation, hyperparameter, and diagnostic analysis.
- J. Fei, C.-N. Yeh, and E. Gull, “Nevanlinna Analytical Continuation,” Physical Review Letters 126, 056402 (2021); causality- and positivity-preserving interpolation in the applicable Green-function class.
- J. Fei, C.-N. Yeh, D. Zgid, and E. Gull, “Analytical Continuation of Matrix-Valued Functions: Carathéodory Formalism,” Physical Review B 104, 165111 (2021); analytic continuation that preserves matrix-valued positivity structure.
- O. Goulko, A. S. Mishchenko, L. Pollet, N. Prokof’ev, and B. Svistunov, “Numerical Analytic Continuation: Answers to Well-Posed Questions,” Physical Review B 95, 014102 (2017); ambiguity-aware inference for feature-level questions.
- O. Gunnarsson, M. W. Haverkort, and G. Sangiovanni, “Analytical Continuation of Imaginary Axis Data Using Maximum Entropy,” Physical Review B 81, 155107 (2010); statistical and default-model contributions to continuation error.
- M. Jarrell and J. E. Gubernatis, “Bayesian Inference and the Analytic Continuation of Imaginary-Time Quantum Monte Carlo Data,” Physics Reports 269, 133–195 (1996); detailed maximum-entropy review and covariance-aware formulation.
- G. J. Kraberger, R. Triebl, M. Zingl, and M. Aichhorn, “Maximum Entropy Formalism for the Analytic Continuation of Matrix-Valued Green’s Functions,” Physical Review B 96, 155128 (2017); signed off-diagonal components and joint matrix constraints.
- A. W. Sandvik, “Stochastic Method for Analytic Continuation of Quantum Monte Carlo Data,” Physical Review B 57, 10287–10290 (1998); stochastic spectral sampling and diagnostics for spurious structure.
- A. N. Tikhonov and V. Y. Arsenin, Solutions of Ill-Posed Problems, Winston, 1977; foundational regularization framework.
- H. J. Vidberg and J. W. Serene, “Solving the Eliashberg Equations by Means of N-Point Padé Approximants,” Journal of Low Temperature Physics 29, 179–192 (1977); the classic rational-continuation construction.