

Variational Parameters
A variational parameter is a coordinate on a chosen family of trial states. Widths, orbital exponents, mixing angles, correlation lengths, tensor entries, and circuit rotations all play this role. Optimizing them means finding the lowest Rayleigh quotient accessible to that family, not solving the unrestricted Hilbert-space problem.
Required background. The Variational Principle supplies the upper bound; Trial Wavefunctions explains ansatz design, and Calculus of Variations supplies stationarity conditions.
Parameterized Rayleigh Quotient
Section titled “Parameterized Rayleigh Quotient”Let
be real parameters and let be a differentiable family of nonzero admissible states. The strong-residual formulas below assume and enough regularity to differentiate its energy. More generally a family differentiable in the form norm has the same quotient derivative with replaced by ; a Hilbert-space residual need not exist. For a fixed Hamiltonian , define
The parameter optimum is
The distinction between minimum and infimum matters. A parameter can run toward a boundary or infinity while the energy approaches a limiting value that is never attained inside . Compact parameter ranges do not arise automatically.
Three spaces should remain conceptually separate:
- Parameter space , where the optimizer moves.
- Trial manifold , the set of physical rays represented by the ansatz.
- Hilbert space, which contains both and states the ansatz cannot represent.
Different parameter values can represent the same physical ray. Overall phase, normalization, periodic angles, tensor-network gauge transformations, and redundant basis functions all create such nonuniqueness.
Derivative of the Energy
Section titled “Derivative of the Energy”Write
For fixed , quotient differentiation gives
Introduce the residual
Then the gradient component has the compact form
This formula is valid whether or not the ansatz is explicitly normalized. It also reveals the central geometry: at a stationary point, the residual is real-orthogonal to every parameter tangent,
The residual need not vanish. Optimization only removes its components visible inside the tangent space of the trial family.
Normalized states
Section titled “Normalized states”If for every parameter value, differentiation of the normalization condition gives
The tangent can still contain a purely imaginary component parallel to , corresponding to a parameter-dependent phase. Because
that phase direction does not affect the energy gradient.
Complex parameters
Section titled “Complex parameters”For complex parameters, either split each one into real and imaginary parts or use Wirtinger derivatives with and treated as independent coordinates. For a real-valued differentiable objective, the two Wirtinger derivatives are conjugate: setting either entire complex derivative to zero imposes both real stationarity conditions. Treating the real energy as a holomorphic function, or varying only the real part of a complex parameter, is generally incorrect.
Tangent Vectors and the State-Space Metric
Section titled “Tangent Vectors and the State-Space Metric”Normalized vectors that differ only by overall phase represent the same physical state. Remove the phase-and-normalization component of a parameter derivative by defining
For normalized states,
The real part of the pulled-back quantum geometric tensor defines a metric on nonredundant parameter directions:
Equivalently,
This metric measures how much the physical state changes, rather than how far the raw coordinates move. It is positive semidefinite. A zero eigenvalue means no first-order change of the physical ray along that coordinate direction. It can reflect a true redundancy or a singular parameterization: has zero metric at even though finite changes matter. Nearly zero eigenvalues indicate weak first-order sensitivity.
The full geometric interpretation is developed in Fubini–Study Geometry. For optimization, the practical lesson is immediate: equal Euclidean steps in two parameters need not produce equal changes in the state.
Geometry-aware updates
Section titled “Geometry-aware updates”Let
An ordinary gradient step is
A metric-scaled or natural-gradient step solves
where is a damping parameter. At , a pseudoinverse removes null directions. Positive damping instead bounds the amplification of small metric eigenvalues; adding also introduces a coordinate-dependent Euclidean scale. Neither operation makes the state metric equal to the energy Hessian.
Natural-gradient language does not create a universal optimizer. The metric can be noisy, singular, expensive to form, or only locally informative. Damping, trust regions, and independent convergence checks remain necessary.
Multiple Parameters and Stationarity
Section titled “Multiple Parameters and Stationarity”For an unconstrained interior optimum ,
This condition is necessary, not sufficient. It can describe a local minimum, maximum, saddle, or flat manifold of equivalent parameterizations.
Coordinate dependence of gradients
Section titled “Coordinate dependence of gradients”Suppose is another smooth coordinate system with
The gradient components transform by the chain rule:
The statement that the gradient vanishes is coordinate independent at a nonsingular change of variables. The numerical size of the gradient is not. A stopping rule such as is meaningless until the parameter scaling and norm have been specified.
Linear coefficients as variational parameters
Section titled “Linear coefficients as variational parameters”For
stationarity with respect to all real and imaginary coefficient directions gives
Thus the generalized eigenvalue equation is the exact coefficient-stationarity condition inside a linear trial space. Nonlinear parameters in the basis functions require an additional outer optimization. See the Rayleigh–Ritz Method.
Constraints and Reparameterization
Section titled “Constraints and Reparameterization”Constraints are often best enforced by construction. An optimizer should not be allowed to step outside the domain where the trial state is meaningful.
Positive parameters
Section titled “Positive parameters”If a width must satisfy , write
Then
At a stationary point,
because the term vanishes there. Logarithmic coordinates enforce positivity and make multiplicative scale changes additive.
Normalization
Section titled “Normalization”Explicit normalization can be built into the ansatz, or the Rayleigh quotient can remove a free overall scale. Treating normalization as an independent unconstrained parameter creates a flat direction. If one instead minimizes subject to , a Lagrange multiplier produces the eigenvalue equation.
Equality constraints
Section titled “Equality constraints”For constraints
under a regularity condition such as independent constraint gradients, the first-order condition is
where
Equivalently, the gradient must vanish along every tangent direction that preserves the constraints to first order.
Symmetry constraints
Section titled “Symmetry constraints”Particle exchange, parity, angular momentum, gauge constraints, and boundary conditions should usually be built into the state family rather than imposed through a large energy penalty. A finite penalty changes the objective and can leave symmetry contamination. Projection methods can restore a symmetry, but their normalization and parameter derivatives must then be included consistently.
Hessians and Local Curvature
Section titled “Hessians and Local Curvature”The parameter Hessian is
At an unconstrained local minimum, is positive semidefinite. Positive definiteness requires an isolated nondegenerate quadratic minimum after redundant directions are removed; even an isolated minimum such as has zero Hessian. A negative eigenvalue identifies a descent direction, while a zero eigenvalue can signal symmetry, gauge redundancy, an underdetermined ansatz, or a higher-order flat direction.
Curvature at an exact eigenstate
Section titled “Curvature at an exact eigenstate”Suppose a normalized ansatz passes through an exact eigenstate at . Since the residual vanishes there, the Hessian simplifies to
For the ground state, this quadratic form is nonnegative. For an excited eigenstate, a tangent confined to lower-energy states has negative curvature unless constraints exclude it. A general tangent with both lower- and higher-energy components has curvature set by their energy-weighted sum; lower-state overlap alone does not determine its sign. An excited eigenstate is therefore typically a saddle of the unrestricted energy functional. Rigorous excited-state bounds use the ordered subspace construction developed in Upper Bounds and the Min–Max Principle.
Stiff and soft directions
Section titled “Stiff and soft directions”Let the nonzero Hessian eigenvalues near a minimum be
The ratio
measures local anisotropy in the chosen coordinates. A large ratio creates a narrow valley: steps stable in the stiff direction make painfully slow progress along the soft direction. This is an optimization-conditioning problem, not automatically evidence of a poor ansatz.
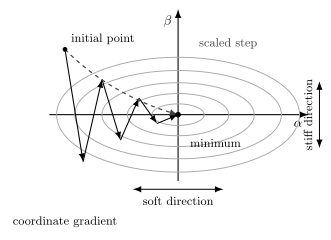
Elongated contours indicate very different curvatures along two parameter combinations. Unscaled coordinate-gradient steps can zigzag across a stiff direction; curvature or state-metric information can propose a better-scaled local step. Neither path changes the trial family’s ansatz error.
The numerical interpretation of condition numbers and stability is developed in Conditioning and Stability.
Scale Analysis Before Optimization
Section titled “Scale Analysis Before Optimization”Physical dimensions should be removed before handing a problem to a numerical optimizer. If one parameter is measured in inverse ångströms and another in joules, an ordinary Euclidean gradient combines incomparable coordinate components.
A useful workflow is:
- identify natural length, energy, and time scales from the Hamiltonian;
- express the ansatz in dimensionless variables;
- center parameters near physically plausible values;
- use logarithmic variables for positive scales spanning orders of magnitude;
- inspect Hessian or metric eigenvalues after the transformation.
Good scaling does not alter the physical trial family. It changes the chart used to search it.
Scale Translation: Quartic Gaussian Width
Section titled “Scale Translation: Quartic Gaussian Width”The quartic oscillator provides a compact example of why scaling should precede optimization. For with and a Gaussian proportional to , define
the Gaussian Rayleigh quotient becomes
The positive parameter is dimensionless and order unity at weak coupling. Frequency notation uses , so the same stationary condition can be written in either chart:
The complete normalization, minimization, weak- and strong-coupling limits, upper-bound interpretation, residual analysis, and numerical comparison are developed in Anharmonic Oscillator by Variational Methods. The coordinate lesson needed here is that the physical optimum is unchanged by the smooth reparameterization , while gradients and curvatures acquire different numerical scales.
Parameter-Dependent Bases
Section titled “Parameter-Dependent Bases”Suppose a nonorthogonal basis depends on a nonlinear parameter and the optimized coefficients solve
with normalization
Along a differentiable normalized eigenbranch of this Hermitian generalized problem,
At a degeneracy one must first select branches by diagonalizing within the degenerate eigenspace, using its metric. The term is essential. It records the changing basis geometry and is a finite-dimensional relative of a Pulay term. Ignoring it treats a moving nonorthogonal basis as fixed and generally gives the wrong gradient.
If the coefficient eigenproblem is not converged, additional response terms survive. The clean derivative formula relies on stationarity with respect to .
Optimized Energies and the Envelope Principle
Section titled “Optimized Energies and the Envelope Principle”Let the Hamiltonian depend on a physical control parameter , and define
The total derivative is
At an unconstrained stationary optimum, the second term vanishes:
This is why optimized variational energies often have simple first derivatives even though the optimal parameters move. Incomplete optimization, changing constraints, and parameter-dependent bases can restore response terms. The operator-derivative statement and its caveats are treated in the Hellmann–Feynman Theorem.
Choosing a Numerical Optimizer
Section titled “Choosing a Numerical Optimizer”No optimizer repairs a trial family that cannot represent the needed physics. Within a reasonable family, the method should match the parameter count, smoothness, conditioning, constraints, and noise level.
| Method | Useful when | Main caution |
|---|---|---|
| Analytic stationarity | One or a few parameters and tractable integrals | Roots can be maxima or saddles |
| Gradient descent with line search | Gradients are reliable and scaling is moderate | Slow in narrow valleys |
| Conjugate-gradient or quasi-Newton | Smooth medium-to-large problems | Curvature models can be corrupted by noise |
| Newton or trust-region method | Accurate Hessian information is affordable | Hessians can be indefinite or singular |
| Derivative-free search | Very few parameters or nonsmooth evaluations | Scales poorly with dimension |
| Natural gradient or stochastic reconfiguration | State geometry is important or Monte Carlo samples provide the metric | Metric estimation, damping, and rank control are delicate |
Line searches and trust regions
Section titled “Line searches and trust regions”A descent direction is not enough. A line search chooses a step length that actually lowers the objective, while a trust region limits the update to a neighborhood where the local model is credible. In noisy calculations, requiring a decrease much smaller than the estimator uncertainty has no statistical meaning.
Stochastic objectives
Section titled “Stochastic objectives”In variational Monte Carlo, the energy, gradient, and metric are sample estimates. Reusing correlated samples can reduce the noise in energy differences, but it also complicates uncertainty estimates. Optimization bias and final statistical uncertainty should be assessed with fresh samples. See Variational Monte Carlo Preview.
Automatic differentiation
Section titled “Automatic differentiation”Automatic differentiation can evaluate exact derivatives of the implemented computational graph. It does not certify that the graph represents the intended Hamiltonian, normalization, boundary conditions, or sampling distribution. Analytic limits and finite-difference spot checks remain valuable.
Exercises
Section titled “Exercises”Logarithmic width coordinate
Section titled “Logarithmic width coordinate”Let . Derive the first and second derivatives of with respect to , and simplify the second derivative at a stationary point in .
Solution
Because ,
Differentiating again,
At ,
Thus the sign of the curvature at an interior stationary point is unchanged, while its numerical scale changes.
Why an excited eigenstate is a saddle
Section titled “Why an excited eigenstate is a saddle”Consider a normalized path through whose projected tangent is , with and . Use the exact-eigenstate Hessian to determine the curvature along this purely lower-state direction. If a higher eigenstate is also available, explain why is a saddle in the unrestricted state space.
Solution
Take a projected tangent . The second variation is proportional to
Since , the curvature is negative. The energy decreases by mixing in the lower state, so the excited eigenstate is not a local minimum in the unrestricted state space. A purely higher-state tangent gives positive curvature, establishing the saddle when both directions exist. A symmetry or orthogonality constraint can remove either direction. A tangent mixing lower and higher states instead has a weighted sum of both signs, so its lower-state component alone does not determine the curvature.
Derivative in a moving nonorthogonal basis
Section titled “Derivative in a moving nonorthogonal basis”Differentiate with respect to , left-multiply by , and use and to derive the parameter-dependent-basis formula.
Solution
Differentiation gives
Left-multiplying by yields
Using cancels the terms containing , and gives
The overlap derivative cannot be discarded when the basis moves.
References
Section titled “References”- S.-i. Amari, “Natural Gradient Works Efficiently in Learning”, Neural Computation 10, 251–276 (1998). Foundational account of metric-aware parameter optimization.
- J. Nocedal and S. J. Wright, Numerical Optimization, 2nd ed. (Springer, 2006). Standard reference for line searches, trust regions, quasi-Newton methods, constraints, and conditioning.
- M. Reed and B. Simon, Methods of Modern Mathematical Physics, Vol. IV: Analysis of Operators (Academic Press, 1978). Mathematical background for variational eigenvalue principles and quadratic forms.
- S. Sorella, “Green Function Monte Carlo with Stochastic Reconfiguration”, Physical Review Letters 80, 4558–4561 (1998). Introduces stochastic reconfiguration in a many-body Monte Carlo setting.
- J. Stokes, J. Izaac, N. Killoran, and G. Carleo, “Quantum Natural Gradient”, Quantum 4, 269 (2020). Connects natural-gradient updates to the geometry of parameterized quantum states.
- J. Toulouse and C. J. Umrigar, “Optimization of quantum Monte Carlo wave functions by energy minimization”, Journal of Chemical Physics 126, 084102 (2007). Detailed analysis of stable energy-minimization methods for nonlinear wavefunctions.
- C. J. Umrigar, K. G. Wilson, and J. W. Wilkins, “Optimized Trial Wave Functions for Quantum Monte Carlo Calculations”, Physical Review Letters 60, 1719–1722 (1988). Classic treatment of trial-state optimization in variational Monte Carlo.