

Gaussian Variational Methods
Gaussian trial states turn many infinite-dimensional variational calculations into finite-dimensional matrix problems. Their normalization, Fourier transforms, derivatives, overlaps, and polynomial moments are analytic. A positive-definite width matrix can represent anisotropy and coordinate correlations, while linear combinations of Gaussians can be enlarged systematically.
The convenience has a cost. A single Gaussian is nodeless, has a Gaussian tail, and has no Coulomb cusp. It can be exact for quadratic Hamiltonians and useful near smooth minima, but it can be structurally wrong for weak binding, tunneling between distant wells, singular interactions, or excited states. The variational theorem preserves an upper bound; it does not erase those ansatz limitations.
Required background. The Variational Principle gives the energy bound, Variational Parameters explains optimization, and Gaussian Distributions and Spectral Decomposition supply the matrix integrals. Gaussian States treats Wigner functions and symplectic spectra; Time-Dependent Variational Principle develops packet evolution.
The complete one-dimensional quartic calculation, including optimization, upper-bound diagnostics, and numerical comparison, is Anharmonic Oscillator by Variational Methods.
When the Gaussian width is used as an adjustable reference frequency inside an order-by-order re-expansion, the method becomes Variational Perturbation Theory. Its first order reproduces a Gaussian Rayleigh quotient; higher orders are reorganized perturbative approximants and need not remain upper bounds.
General Real Gaussian Ansatz
Section titled “General Real Gaussian Ansatz”Let
collect Cartesian coordinates, or linear internal coordinates such as Jacobi coordinates with flat measure , and let be a real symmetric positive-definite matrix. With
define
The center is . The matrix is a precision matrix for the wavefunction amplitude; its eigenvalues have dimensions of inverse length squared. Positive definiteness ensures decay in every coordinate direction and makes the state normalizable. Curvilinear coordinates with nonconstant measure or kinetic metric require modified integrals.
Then the probability density is
The multidimensional Gaussian integral
confirms normalization.
Width Matrix and Covariance
Section titled “Width Matrix and Covariance”The position mean is
and the position covariance is
Diagonalize the width matrix as
where is orthogonal and every . The columns of are the principal directions of the probability ellipsoid. Along principal direction , the position standard deviation is
Off-diagonal entries of therefore have physical content: they rotate the principal axes and encode coordinate correlations. They are not merely inconvenient matrix elements to be discarded.
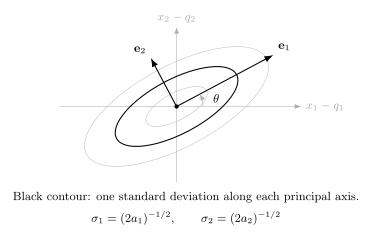
For , the probability contours are ellipses whose principal standard deviations are . An off-diagonal entry in laboratory coordinates rotates the ellipse and permits correlations that a diagonal product ansatz cannot represent.
Width conventions
Section titled “Width conventions”Three related matrices are easy to confuse:
| Object | Matrix in the exponent | Position covariance |
|---|---|---|
| wavefunction amplitude | ||
| probability density | ||
| conventional normal density |
Since , the probability density can also be written
Stating the convention is more reliable than calling every parameter simply a width.
Momentum Covariance and Kinetic Energy
Section titled “Momentum Covariance and Kinetic Energy”For the real Gaussian,
The momentum mean vanishes,
and direct differentiation gives
Thus the momentum covariance matrix is
In the principal basis,
so every principal pair saturates
Consider a kinetic energy with a symmetric positive-definite mass matrix ,
Its expectation is
Large eigenvalues of describe narrow coordinate directions and increase the kinetic energy. This is the matrix version of the localization cost in the harmonic-oscillator variational estimate.
Potential Expectations
Section titled “Potential Expectations”For a coordinate-space potential,
If is sufficiently regular and its Gaussian expectation exists, this is a Gaussian smoothing of the potential. For analytic , it can be organized formally as
The first terms are
Odd centered moments vanish. Fourth moments obey the Gaussian pairing identity
This is the finite-dimensional Gaussian form of Wick or Isserlis pairing. It makes polynomial anharmonicities straightforward to evaluate, although their width optimization can still be nonlinear.
The center obeys a useful stationarity condition. Translating the normalized Gaussian gives
At an optimized center,
This is an averaged force-balance equation, not generally the same as placing at a pointwise minimum of .
Exact Solution for Coupled Quadratic Hamiltonians
Section titled “Exact Solution for Coupled Quadratic Hamiltonians”The matrix Gaussian becomes exact for a stable quadratic Hamiltonian. Let
where both and are real symmetric positive-definite matrices.
The center is minimized at . The Gaussian energy is
For a symmetric variation ,
Therefore
Stationarity for every symmetric requires
or equivalently
Define the mass-weighted force matrix
Its positive square root gives the unique positive-definite stationary width,
The eigenvalues of are the normal-mode frequencies . At the optimum,
and
This is the exact coupled-oscillator ground energy. The full width matrix automatically performs the normal-mode rotation and assigns the correct width to every mode.
If has a zero or negative direction, the assumptions fail. A zero mode has no normalizable oscillator ground state in that coordinate, while a negative direction signals an unstable quadratic potential. The positive-definite solution should not be continued blindly through either case.
Worked Example: Two Coupled Coordinates
Section titled “Worked Example: Two Coupled Coordinates”Consider equal masses with
where
ensures stability. The normal coordinates are
with frequencies
The exact Gaussian width matrix in the coordinates is
For , the off-diagonal entry is nonzero. The exact ground state is correlated in the original coordinates even though it factorizes in the normal coordinates.
The exact energy is
Now restrict the trial family to an axis-aligned isotropic product,
Because , its energy is
Optimization gives
For nonzero coupling,
The restricted product misses correlation energy. Adding one off-diagonal width parameter is enough to recover the exact quadratic result.
Positive-Definite Parameterizations
Section titled “Positive-Definite Parameterizations”Directly optimizing independent entries of can step outside the positive-definite cone, making the trial state nonnormalizable. A parameterization should enforce admissibility by construction.
Cholesky factor
Section titled “Cholesky factor”Write
where is lower triangular and its diagonal entries are positive. Parameterize those diagonals as
This is efficient and guarantees . The coordinates depend on the ordering and scaling of the original variables, so preprocessing still matters.
Matrix exponential
Section titled “Matrix exponential”For any real symmetric matrix ,
is positive definite. This provides global unconstrained coordinates, although differentiating the matrix exponential is more expensive than differentiating a Cholesky factor.
Eigenvalues and rotations
Section titled “Eigenvalues and rotations”The decomposition
is physically interpretable: the set principal widths and sets orientation. It becomes coordinate-singular when eigenvalues coincide because rotations inside a degenerate eigenspace do not change .
| Parameterization | Main advantage | Main caution |
|---|---|---|
| efficient and stable | coordinate-order dependence | |
| unconstrained symmetric parameters | costly matrix derivatives | |
| eigenvalues plus rotations | direct geometric meaning | redundant rotations at degeneracy |
The normalization depends on . The identity
is essential when differentiating normalized Gaussian states. When differentiating a normalized expectation, freezing the determinant prefactor produces the wrong gradient. Alternatively, an unnormalized Gaussian and the full Rayleigh quotient give the same answer because its denominator supplies that normalization derivative.
Complex Widths and Phase-Space Correlations
Section titled “Complex Widths and Phase-Space Correlations”A more general pure Gaussian wave packet uses a real positive-definite amplitude matrix , a real symmetric chirp matrix , a center , and a mean momentum :
The position covariance remains
while the momentum covariance becomes
The symmetrized position–momentum covariance block is
Thus tilts the Gaussian in phase space and represents a quadratic phase or chirp. It is required for generic exact Gaussian dynamics even though it does not alter the position density at one instant.
For the static scalar Hamiltonian used above,
The and contributions are nonnegative and do not change a coordinate-only potential expectation. In a time-reversal-invariant ground-state problem with no vector potential, their static optimum is therefore
Magnetic fields, imposed currents, angular momentum, and real-time propagation change that conclusion. The equations of motion for complex widths are derived in the Time-Dependent Variational Principle, while covariance-matrix state classification is developed in Gaussian States Preview.
Squeezed-State Connection
Section titled “Squeezed-State Connection”A centered real Gaussian with a width different from a reference oscillator vacuum is a squeezed pure Gaussian state. In one dimension, if the reference precision is and
then
One quadrature narrows while its conjugate broadens. A multidimensional combines rotations and mode-dependent squeezing. This connection explains why Gaussian variational widths have a direct quantum-state interpretation, but it does not mean that every Gaussian variational problem should be reformulated in quantum-optics language. The canonical operator and noise discussion is in Squeezed States: First Encounter.
Linear Combinations of Gaussians
Section titled “Linear Combinations of Gaussians”A single Gaussian is one nonlinear trial manifold. A Gaussian basis enlarges the state to
where each may have its own center, width matrix, polynomial prefactor, and symmetry projection.
For fixed nonlinear Gaussian parameters, optimizing the coefficients gives the generalized eigenproblem
An outer optimization then changes centers and width matrices. Separating the exact inner coefficient solve from the nonlinear outer search is usually more stable than treating all variables identically.
For two centered normalized real Gaussians, the overlap is
As and become nearly equal, their overlap approaches one. Large Gaussian bases can therefore develop near-linear dependence and an ill-conditioned overlap matrix.
Gaussian product theorem
Section titled “Gaussian product theorem”For unnormalized one-dimensional functions,
Similarly,
Their product is
where
The separation-dependent factor is
Products centered on different points reduce to one Gaussian centered at a weighted average. This identity is a major reason multicenter molecular integrals remain tractable.
Symmetry and Coordinate Choices
Section titled “Symmetry and Coordinate Choices”The basic centered Gaussian is even and nodeless. It is naturally suited to bosonic or spatial ground states, but not by itself to odd parity, nonzero angular momentum, or fermionic antisymmetry.
Common extensions include:
- multiplying by polynomials to create nodes and angular structure;
- projecting onto parity or rotational quantum numbers;
- antisymmetrizing products or using Slater determinants;
- combining displaced Gaussians to describe multiple centers;
- using explicitly correlated coordinates such as interparticle separations;
- separating center-of-mass and internal coordinates before optimizing widths.
For a translation-invariant many-particle Hamiltonian, a positive-definite Gaussian in all laboratory coordinates artificially localizes the free center of mass. Use Jacobi or other internal coordinates, or factor the center-of-mass motion explicitly. A singular width matrix in the full coordinate space does not define an ordinary normalized wavefunction there.
Coordinate scaling matters as well. If one coordinate is measured in ångströms and another represents a collective mode with a very different natural length, optimizing raw entries of can create severe conditioning problems. Mass weighting and nondimensionalization should precede nonlinear optimization.
Limitations and Failure Modes
Section titled “Limitations and Failure Modes”Wrong asymptotic tail
Section titled “Wrong asymptotic tail”A Gaussian decays as
faster than a typical short-range bound-state tail
This mismatch can strongly affect weak binding, tunneling amplitudes, polarizabilities, and large-distance observables even when the energy looks good.
Missing Coulomb cusp
Section titled “Missing Coulomb cusp”At an electron–nucleus or electron–electron coalescence, the exact wavefunction satisfies a cusp relation. A smooth Gaussian centered at the coalescence has zero radial derivative there and cannot satisfy a nonzero cusp. No finite sum of smooth Gaussians reproduces an exact nonzero spherical cusp at the origin. An increasing basis can approximate the wavefunction and energy in appropriate norms, but convergence of contact properties may be slow without explicit correlation or cusp-corrected factors.
Nodes and sign structure
Section titled “Nodes and sign structure”A single real Gaussian is positive everywhere. Excited states, fermionic states, and angular-momentum sectors require polynomial factors, symmetry projections, or signed combinations. Optimizing a nodeless Gaussian cannot discover a nodal surface absent from the ansatz.
Multimodal states
Section titled “Multimodal states”A state localized in two distant wells is poorly represented by one ellipse. A sum of displaced Gaussians can represent both lobes and their relative phase; a single covariance matrix cannot.
Nonlinear optimization and redundancy
Section titled “Nonlinear optimization and redundancy”Centers and widths create a nonconvex optimization problem. Permuting identical Gaussians leaves the state unchanged, coincident functions create nearly flat directions, and extreme widths can make matrix elements ill-conditioned. Report overlap spectra, gradient norms, multiple-start checks, and refinement stability.
Upper bounds do not validate observables
Section titled “Upper bounds do not validate observables”For an admissible normalized state and exact matrix elements, the energy remains an upper bound to the ground energy. A good bound does not certify tails, contact densities, transition amplitudes, or entanglement. Check observables that probe the physics the Gaussian family may miss.
Exercises
Section titled “Exercises”Derive the kinetic trace
Section titled “Derive the kinetic trace”For
show that a centered real Gaussian satisfies
Solution
Differentiation gives
and
Using ,
Since ,
Contracting with gives the trace formula.
Quantify the missed correlation energy
Section titled “Quantify the missed correlation energy”For the two-coordinate example, expand the exact ground energy for small
Compare it with the optimized isotropic product energy through order .
Solution
The exact energy is
Using
the odd terms cancel:
The optimized isotropic product gives . Its leading excess is therefore
The first missed contribution is quadratic because the cross expectation vanishes in the uncorrelated state.
Show that a static chirp costs kinetic energy
Section titled “Show that a static chirp costs kinetic energy”For the complex-width Gaussian, prove that the -dependent kinetic contribution is nonnegative and determine when it vanishes.
Solution
The extra term is
Define
Then cyclicity of the trace gives
This is a Frobenius norm squared:
Since and are invertible, it vanishes exactly when .
References
Section titled “References”- S. F. Boys, “Electronic wave functions. I. A general method of calculation for the stationary states of any molecular system”, Proceedings of the Royal Society A 200, 542–554 (1950), a foundational Gaussian-orbital construction.
- T. Helgaker, P. Jørgensen, and J. Olsen, Molecular Electronic-Structure Theory (Wiley, 2000), for Gaussian basis functions, integral technology, and conditioning in electronic-structure calculations.
- E. J. Heller, “Time-dependent approach to semiclassical dynamics”, Journal of Chemical Physics 62, 1544–1555 (1975), for evolving multidimensional Gaussian packets and complex width parameters.
- C. Lubich, From Quantum to Classical Molecular Dynamics: Reduced Models and Numerical Analysis (European Mathematical Society, 2008), for variational Gaussian wave-packet dynamics and geometric numerical structure.
- R. Shankar, Principles of Quantum Mechanics, 2nd ed. (Springer, 1994), for the variational principle, oscillator, and Gaussian wave packets.
- Y. Suzuki and K. Varga, Stochastic Variational Approach to Quantum-Mechanical Few-Body Problems (Springer, 1998), for correlated Gaussian bases and nonlinear parameter selection.