

Entropy Overview
The von Neumann entropy of a density operator is
It is the Shannon entropy of the eigenvalue distribution of . It is zero exactly for pure states and increases under uniform mixing of the eigenvalues. It is not a distance between states and does not assign a preferred physical preparation to a density operator.
That mathematical statement supports several distinct uses. Entropy can quantify local mixedness, preparation uncertainty, thermodynamic entropy, source-compression rate, or pure-state bipartite entanglement, but only after the relevant physical structure has been specified. A positive value by itself does not identify why a state is mixed.
Helpful background. Density operators supplies the spectrum of a state, and Shannon entropy explains entropy of a probability distribution. Unless written as , logarithms below have base two and entropy is in bits. We assume finite dimensions until the final qualification.
Spectral Definition
Section titled “Spectral Definition”Let be a density operator on a -dimensional Hilbert space. Its spectral decomposition is
The operator logarithm is defined by functional calculus on the support of :
Although diverges on the kernel of , the product has a continuous extension there because
Thus the convention gives
The logarithm base fixes the unit:
- gives bits;
- gives nats;
- multiplying the natural-logarithm convention by Boltzmann’s constant gives thermodynamic entropy units.
Changing to another base rescales every entropy by a constant:
What the Entropy Depends On
Section titled “What the Entropy Depends On”Entropy depends only on the multiset of eigenvalues. If is unitary, then has the same spectrum as , so
The eigenvectors may rotate while the entropy remains unchanged. This makes a basis-independent state function, unlike the Shannon entropy of the outcomes of one chosen measurement.
The formula also explains what entropy does not retain. It does not identify:
- which eigenvector carries which physical label;
- which ensemble preparation produced ;
- whether the mixedness came from classical randomization, entanglement, noise, or coarse graining;
- which observable should be measured;
- how close two states are when they have the same spectrum but different eigenvectors.
Entropy compresses the spectrum to one number. In dimensions at least three, different spectra can even have the same entropy. For a qubit it determines the two eigenvalues but not their eigenvectors, so it is still not a complete description of the state.
Bounds and Equality Cases
Section titled “Bounds and Equality Cases”If , then
The lower bound is saturated exactly by pure states. A pure density operator has spectrum
and therefore
Conversely, every term is nonnegative, and it vanishes only when is or . Normalization then implies that zero entropy requires one eigenvalue equal to , hence a rank-one state. In finite dimensions,
The upper bound is saturated when the state is uniform on its support:
where projects onto an -dimensional subspace. In particular, the unique maximum-entropy state on the full -dimensional space is
These are statements at fixed Hilbert-space dimension. Appending unused zero-eigenvalue directions changes but not on its support and not .
Qubit Entropy and the Bloch Radius
Section titled “Qubit Entropy and the Bloch Radius”A qubit density operator has Bloch form
Its eigenvalues are
Using base- logarithms,
The direction of fixes the eigenvectors but does not affect the entropy. Only the radius matters. For ,
so entropy decreases monotonically as the Bloch vector approaches the pure-state sphere.
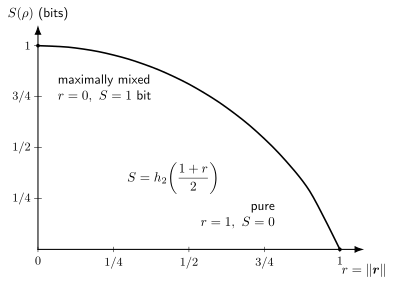
For a qubit, in bits. Entropy is maximal at the center of the Bloch ball and vanishes on its surface.
For a matrix
the Bloch radius is
This yields the entropy without separately solving a quadratic eigenvalue equation. Positivity is equivalent to .
State Entropy Is Not Measurement Entropy
Section titled “State Entropy Is Not Measurement Entropy”Consider the two qubit states
Both have diagonal entries in the computational basis. Measuring either state in that basis gives a fair random bit. Nevertheless,
The off-diagonal coherence makes rank one, while has two equal eigenvalues. Applying entry by entry would miss this distinction and is not how an operator function is evaluated.
More generally, a rank-one projective measurement in basis has outcome probabilities
Their Shannon entropy satisfies
This can be proved using only the concavity of , with . If , set . Completeness of both orthonormal bases gives , while . Hence
Strict concavity makes equality possible only when each measurement ket has support within a single eigenspace of . Thus equality holds exactly when is diagonal in the measurement basis, including rotations within degenerate eigenspaces. Measuring in an eigenbasis realizes the minimum: the state entropy is the least outcome entropy among complete rank-one projective measurements.
The restriction on measurements matters. A one-outcome POVM has zero outcome entropy for every state and need not obey the inequality. A measurement basis that does not diagonalize adds outcome randomness beyond its spectral mixedness.
Entropy and Ensemble Information
Section titled “Entropy and Ensemble Information”Suppose a preparation procedure uses pure states with probabilities :
The Shannon entropy describes uncertainty in the classical preparation label . The von Neumann entropy describes the spectrum of the state after that label is discarded. They are generally different because the vectors need not be distinguishable.
For a pure-state ensemble,
If the nonzero-probability states are mutually orthogonal, the preparation labels can be perfectly distinguished and equality holds. At the opposite extreme, if every is the same vector, then is pure and
even if is large. The density operator forgets redundant classical labels.
This distinction is essential because a density operator has many ensemble decompositions. Entropy is the same for all of them. See Ensembles and Preparation Procedures and Classical Mixtures vs Quantum Superpositions.
Elementary Structural Properties
Section titled “Elementary Structural Properties”Three properties recur throughout quantum mechanics.
Unitary invariance
Section titled “Unitary invariance”Unitary evolution preserves the spectrum:
Therefore a closed system evolving unitarily has constant von Neumann entropy. Apparent entropy change requires a changed description, such as discarding a subsystem, averaging over uncertain controls, performing a nonunitary update, or coupling to an environment and ignoring part of it.
Additivity for product states
Section titled “Additivity for product states”If has eigenvalues and has eigenvalues , then has eigenvalues . Hence
Additivity here assumes a product state. Correlations alter the joint entropy and are quantified by quantities such as Mutual Information.
Concavity under mixing
Section titled “Concavity under mixing”For density operators and classical probabilities ,
Forgetting which preparation occurred cannot lower the average entropy. This does not mean that entropy increases under every quantum channel. A nonunital process such as cooling or amplitude damping can reduce a system’s entropy by transferring entropy to an environment.
In finite dimension, entropy is also continuous: states close in trace distance have close entropies, with a dimension-dependent bound. The Fannes–Audenaert inequality makes this statement quantitative. Continuity becomes subtler in infinite-dimensional systems.
Relation to Purity and Rényi Entropies
Section titled “Relation to Purity and Rényi Entropies”The purity
and the von Neumann entropy are both spectral mixedness diagnostics, but they retain different information. The order- Rényi entropy is
whereas von Neumann entropy is the order- limit of the Rényi family. With the same logarithm base,
For a qubit, purity determines the Bloch radius through
so it also determines . In dimensions , equal purity does not generally imply equal von Neumann entropy. They should not be interchanged: purity equals one for a pure state, whereas its von Neumann entropy is zero.
Entanglement Entropy Preview
Section titled “Entanglement Entropy Preview”Let be a pure bipartite state with Schmidt decomposition
The reduced states have the same nonzero spectrum:
Therefore
For a pure joint state, this common value is the entanglement entropy across the versus split. It vanishes exactly for a product state. For the Bell state,
the joint state has zero entropy while each qubit has entropy one bit:
There is no contradiction: entropy is assigned to a specified state on a specified system. A pure whole can have mixed parts.
The qualifier pure joint state is indispensable. If is mixed, then can reflect local noise, classical preparation uncertainty, environmental entanglement, and several kinds of correlation. It is not by itself a mixed-state entanglement measure.
Thermal and Open-System Interpretations
Section titled “Thermal and Open-System Interpretations”For a Gibbs state with finite nonzero partition function and finite mean energy
the natural-logarithm entropy is
Here , and this displayed entropy uses natural logarithms, so it is in nats. Multiplication by gives the thermodynamic entropy. This interpretation uses the Hamiltonian, equilibrium ensemble, and temperature; an arbitrary mixed state is not automatically thermal. The detailed treatment is Entropy in Quantum Statistical Mechanics.
For a subsystem coupled to an environment, the reduced entropy may change even while the total state evolves unitarily and the total entropy remains constant. Correlations can move information out of the subsystem description. Yet local entropy can also decrease, as in cooling, measurement conditioned on an outcome, or transfer of a mixed state into the environment. Entropy increase is not a universal statement about every reduced quantum process.
Infinite-Dimensional and QFT Caveats
Section titled “Infinite-Dimensional and QFT Caveats”For a trace-class density operator on a separable Hilbert space, the spectral series
still defines the von Neumann entropy, but the sum may diverge to . Entropy is not uniformly continuous on an unrestricted infinite-dimensional state space; energy constraints or other compactness conditions are often needed for stable bounds.
In quantum field theory, spatial regions carry infinitely many short-distance degrees of freedom. Naive entanglement entropy is typically regulator dependent and ultraviolet divergent, and algebraic local states need not be represented by density matrices on a simple tensor factor. Finite-dimensional formulas remain useful guides, but their assumptions must be checked before extrapolation.
Calculation Workflow
Section titled “Calculation Workflow”To compute in finite dimension:
- Verify that is Hermitian, positive semidefinite, and trace one.
- Find its eigenvalues, including multiplicities.
- Discard no small eigenvalue merely because it is inconvenient; distinguish numerical noise from physical support.
- Choose and state the logarithm base.
- Evaluate with .
- Check the bound .
- Interpret the number only after identifying whether describes a whole system, a subsystem, a thermal state, or an ensemble average.
For numerical spectra near zero, evaluate with stable special functions or explicit zero handling. Forming a matrix logarithm and then multiplying can be less stable than working directly with eigenvalues.
Common Mistakes
Section titled “Common Mistakes”Taking the logarithm of each matrix entry. Entropy is a function of the eigenvalues. The coherent state and have identical computational diagonals but different spectra.
Calling every local entropy entanglement. Reduced entropy quantifies bipartite entanglement when the full state is pure. Mixed-state local entropy alone cannot distinguish classical noise from entanglement.
Confusing outcome entropy with state entropy. Measurement randomness depends on the chosen effects. The bound above concerns complete rank-one projective measurements, not arbitrary POVMs or coarse readouts.
Assuming every physical process increases entropy. A reset can reduce system entropy. For a closed system under unitary evolution, the full density-operator spectrum and entropy remain constant.
References
Section titled “References”- K. M. R. Audenaert, “A sharp continuity estimate for the von Neumann entropy,” Journal of Physics A: Mathematical and Theoretical 40, 8127–8136 (2007). DOI: 10.1088/1751-8113/40/28/S18.
- M. A. Nielsen and I. L. Chuang, Quantum Computation and Quantum Information, 10th anniversary edition, Cambridge University Press, 2010, Chapters 2 and 11. Cambridge DOI.
- J. Watrous, The Theory of Quantum Information, Cambridge University Press, 2018, Chapter 5. Author’s book page and manuscript.
- A. Wehrl, “General properties of entropy,” Reviews of Modern Physics 50, 221–260 (1978). DOI: 10.1103/RevModPhys.50.221.
Exercises
Section titled “Exercises”- Let have nonzero eigenvalues . Show that if and only if is pure.
Solution
For ,
with equality only at or . Therefore
vanishes only if every eigenvalue is or . Since the eigenvalues sum to one, exactly one is and all others are zero. The density operator then has rank one and is pure. Conversely, the spectrum of a pure state is , which gives zero entropy.
- Show that the maximally mixed state on a -dimensional space has entropy . Why does this saturate the upper bound?
Solution
The state has eigenvalues equal to . Hence
The eigenvalues form the uniform distribution. Shannon entropy is maximized by the uniform distribution on a fixed number of outcomes, so no -dimensional density operator can have larger entropy.
- Derive the qubit formula
and determine its endpoint values.
Solution
The operator has eigenvalues , so
Therefore, in bits,
At , both eigenvalues are , giving one bit. At , the eigenvalues are and , giving zero. The result depends on the radius but not the Bloch-vector direction.
- The states and have the same computational-basis diagonal. Compute their state entropies and the Shannon entropies of computational-basis measurement outcomes.
Solution
The spectrum of is , so
The spectrum of is , so
Both states give computational-basis probabilities and therefore one bit of measurement-outcome entropy. For that randomness comes from measuring in a basis that does not contain the state vector; it is not spectral mixedness.
- Prove additivity for a product state directly from its eigenvalues.
Solution
Let the eigenvalues of and be and . The product-state eigenvalues are . Then
where was used in the third line.
- Consider the equally weighted ensemble . Compute the density operator, its eigenvalues, and its entropy in bits. Compare with the one-bit entropy of the preparation label.
Solution
The density operator is
Its trace is and its determinant is , so its eigenvalues are
Therefore
The preparation label has entropy one bit, but the two prepared states are not orthogonal and cannot be perfectly distinguished. Discarding the label leaves less than one bit of spectral entropy.
- For the Bell state , compute the entropy of the joint state and of each one-qubit reduced state.
Solution
The joint density operator is a rank-one projector, so
Tracing either qubit gives
Hence
The whole is pure while the parts are mixed because the qubits are entangled. For a pure bipartite state, the equal reduced entropies are the entanglement entropy.
- A two-level Gibbs state has energies and . Find its entropy in nats and its limits as and .
Solution
The partition function and excited-state probability are
The ground-state probability is , so
Equivalently, with natural logarithms,
As , the probabilities approach and . As , the ground-state probability approaches one and .